featured

This new Grok model is amazingly good at coding

The new Grok 4.6 model is amazingly good at coding.

Elon Musk’s xAI trained it on billions of real developer interactions and and code editing patterns — thanks to their recent acquisition of the Cursor IDE.

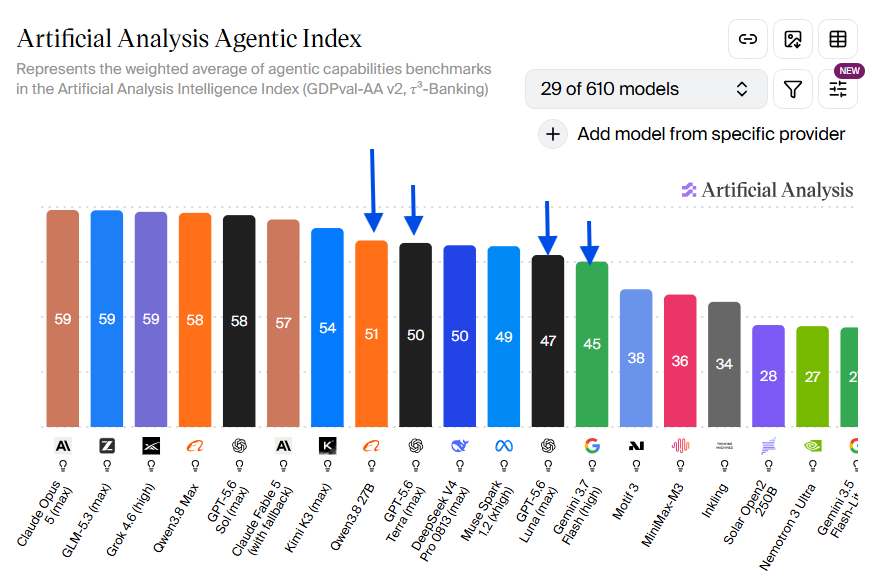
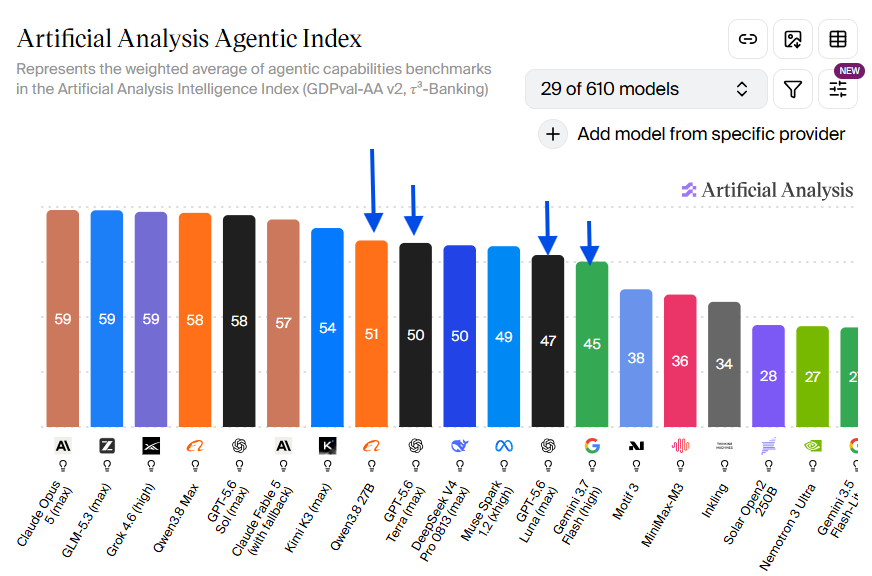
It now performs as good as top-tier models like GPT-5.6 and Opus 5 the vast majority of the time — yet it’s multiple times cheaper.

And Grok 4.7 is already coming very soon too — with big promises of it “exceeding all current models” from Musk.

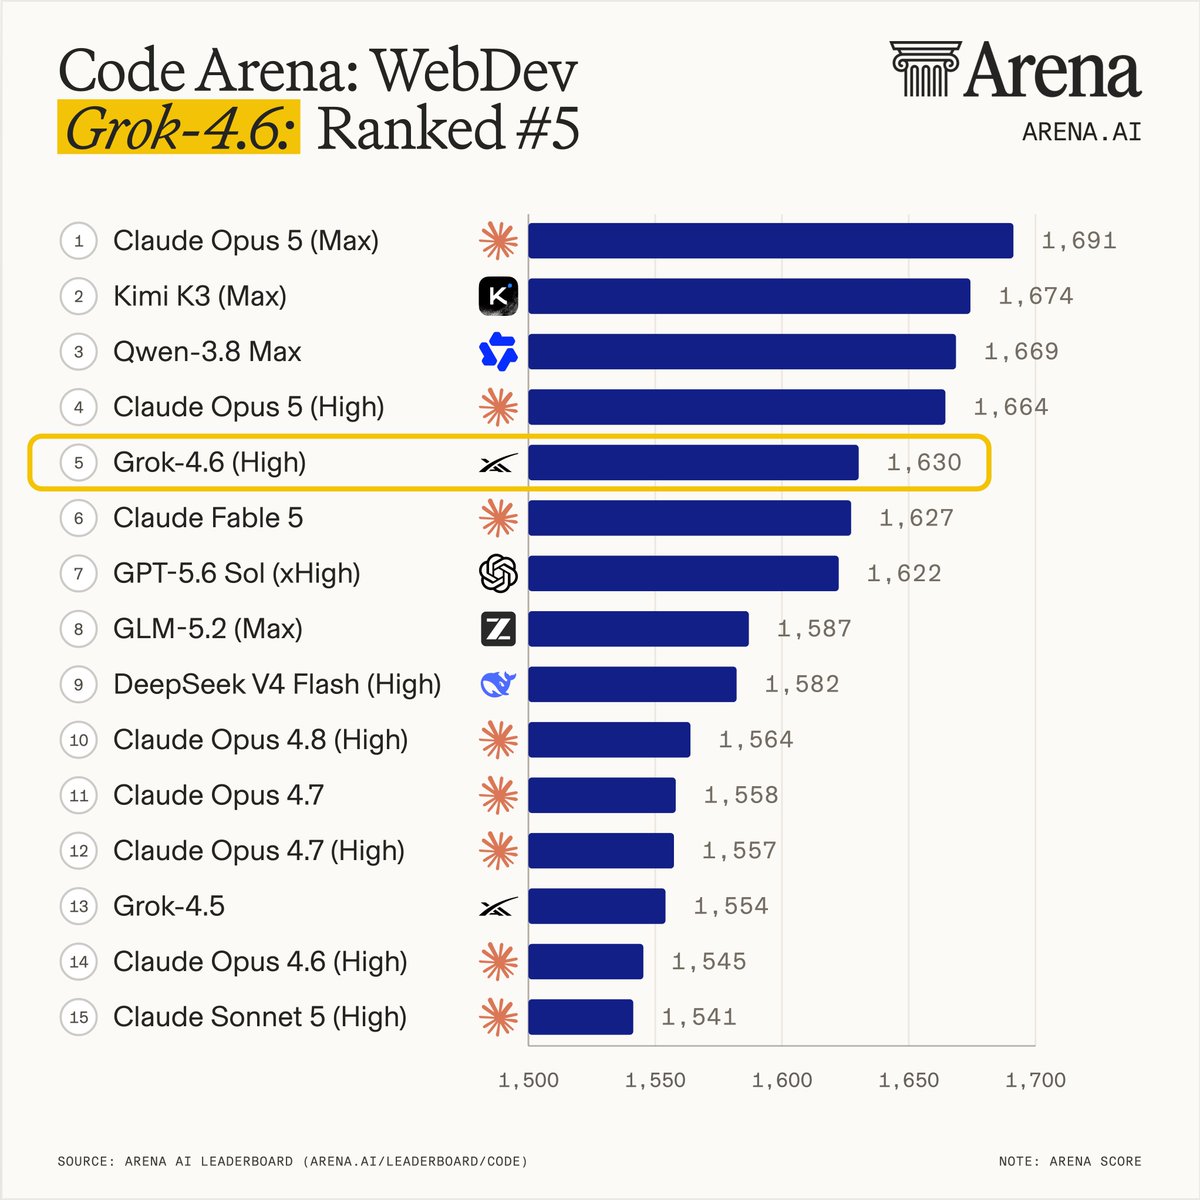
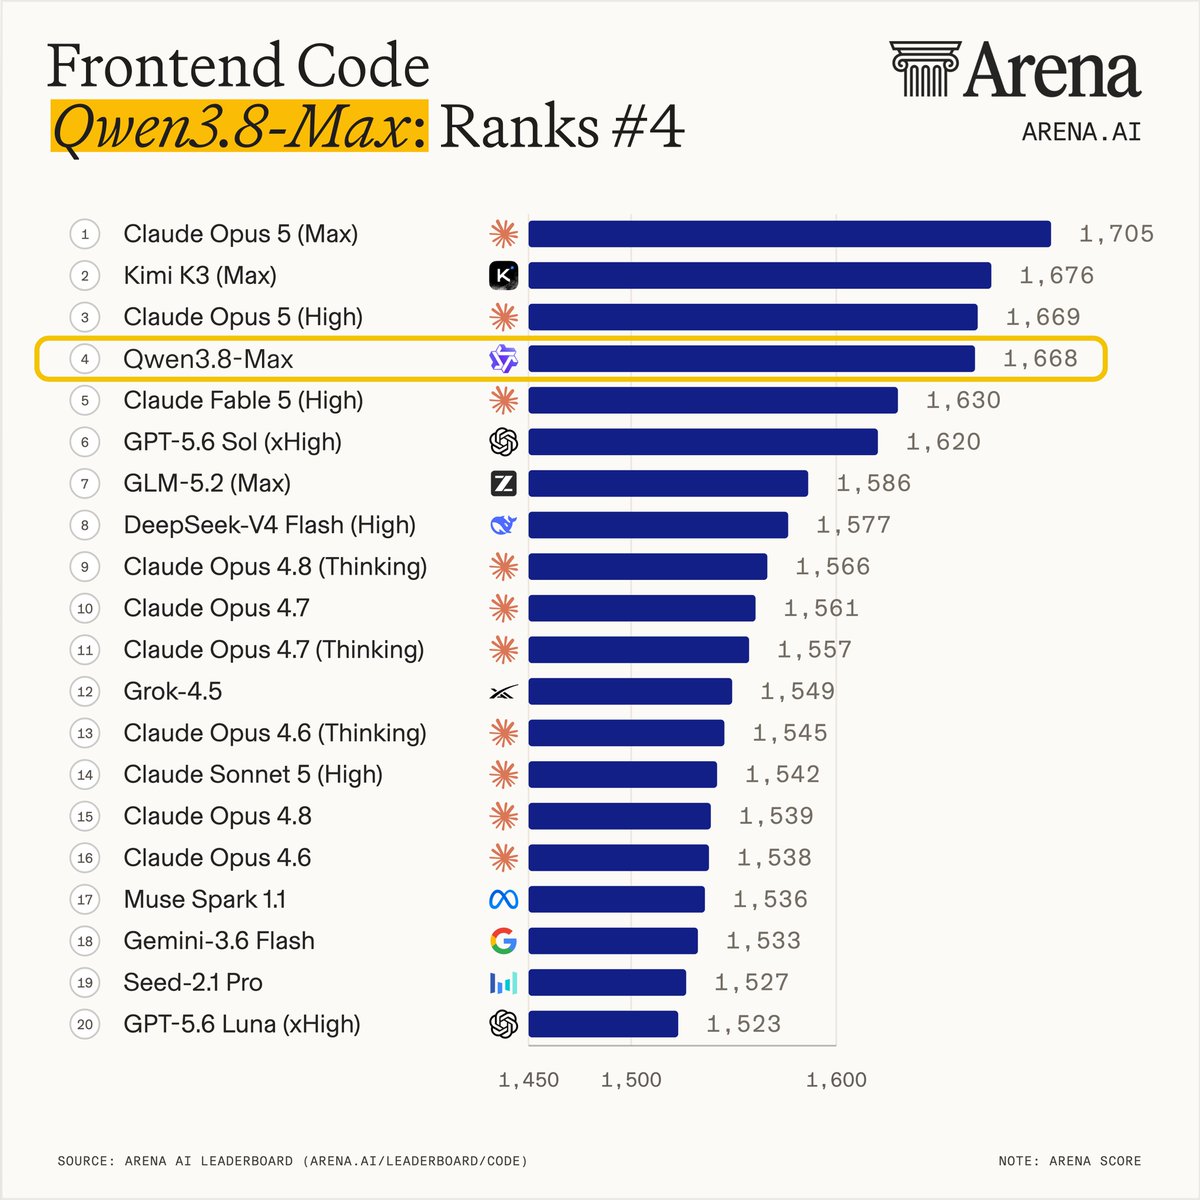
Grok 4.6 scores an incredible 5th place on the AI Arena Leaderboard — despite being much cheaper than most of the model above it — only Qwen 3.8 Max is as cheap as it (same price).
On CursorBench v3.2, Grok 4.6 Extra High took the top spot with 70.8%, edging out Fable 5 Max at 70.5% and Opus 5 Max at 70.0%, while comfortably beating GPT-5.6 Sol Max at 67.2%

It comes with major upgrades in software engineering and long-horizon agentic coding.

Grok 4.6 combines frontier-level benchmark performance with aggressive pricing, long-running agent capabilities, deep Cursor integration, and stronger visual application development.

It can carry out the most complex tasks in the most complicated codebases imaginable.

Grok 4.6 is designed to execute extended, multi-step workflows. It can use tools, navigate large codebases, research unfamiliar topics and maintain context across long sequences of actions.

It also has much stronger self-verification.

Grok 4.6 is much better at checking its own homework: xAI reports more self-testing and verification on long-running tasks, alongside a jump from 54% to 65.9% on DeepSWE v1.1 and 47.1% to 57.5% on APEX-Agents versus Grok 4.5.

And this fixes one of the biggest weaknesses of autonomous AI agents: small mistakes accumulating across long workflows.

It also has a 500K context window — something I was really surprised about — cause these days 1 million is like the standard. But it’s still quite a lot.

With a 500,000-token context window, Grok 4.6 can keep roughly 375,000 words of text in context at once—equivalent to about five full-length novels—giving long-running agents far more room to work without losing the plot

It’s a lot more intelligent than it’s predecessor — even though it costs exactly the same — giving much more intelligent per unit cost.

It scores 61 on the Artificial Analysis Intelligence Index, up from Grok 4.5’s 56 and placing it among the highest-performing models in SpaceXAI’s published comparison.

Grok 4.6 was trained from the ground up on the actual real-world code and developer patterns from Cursor — so it could achieve the best results possible as a coding agent.

Its training included high-quality engineering data and supervised fine-tuning trajectories covering software engineering, reasoning, STEM and agent workflows.

It used sophisticated techniques like reinforcement learning to deeply understand how we actually code and work as developers.

SpaceXAI then applied agentic reinforcement learning across environments including general coding, kernel optimization, web development and computer-aided design.

It also amazing at coding with visual input data — which makes it especially powerful for web design and frontend development.

Give it a high-level product idea, and the model can establish an application’s structure and visual language, implement its core interactions and then refine the result through subsequent iterations.

You can build unbelievably sophisticated games and 3d web experiences with very little prompting.

You can just describe what you want to build and let the Grok-4.6-powered agent work out all the architecture, interface and implementation.

xAI is still a serious contender in the AI race — and Grok 4.6 is definitely worth giving a try, for coding and many other use cases.

This new Grok model is amazingly good at coding Read More »
This secret new coding model just shocked the entire world

The crazy thing is that nobody knows exactly who is behind it — just a cryptic name of Ox Alpha.

But it’s already scoring amazingly in several benchmarks — even beating Claude Fable and GPT-5.6 Sol in critical areas.

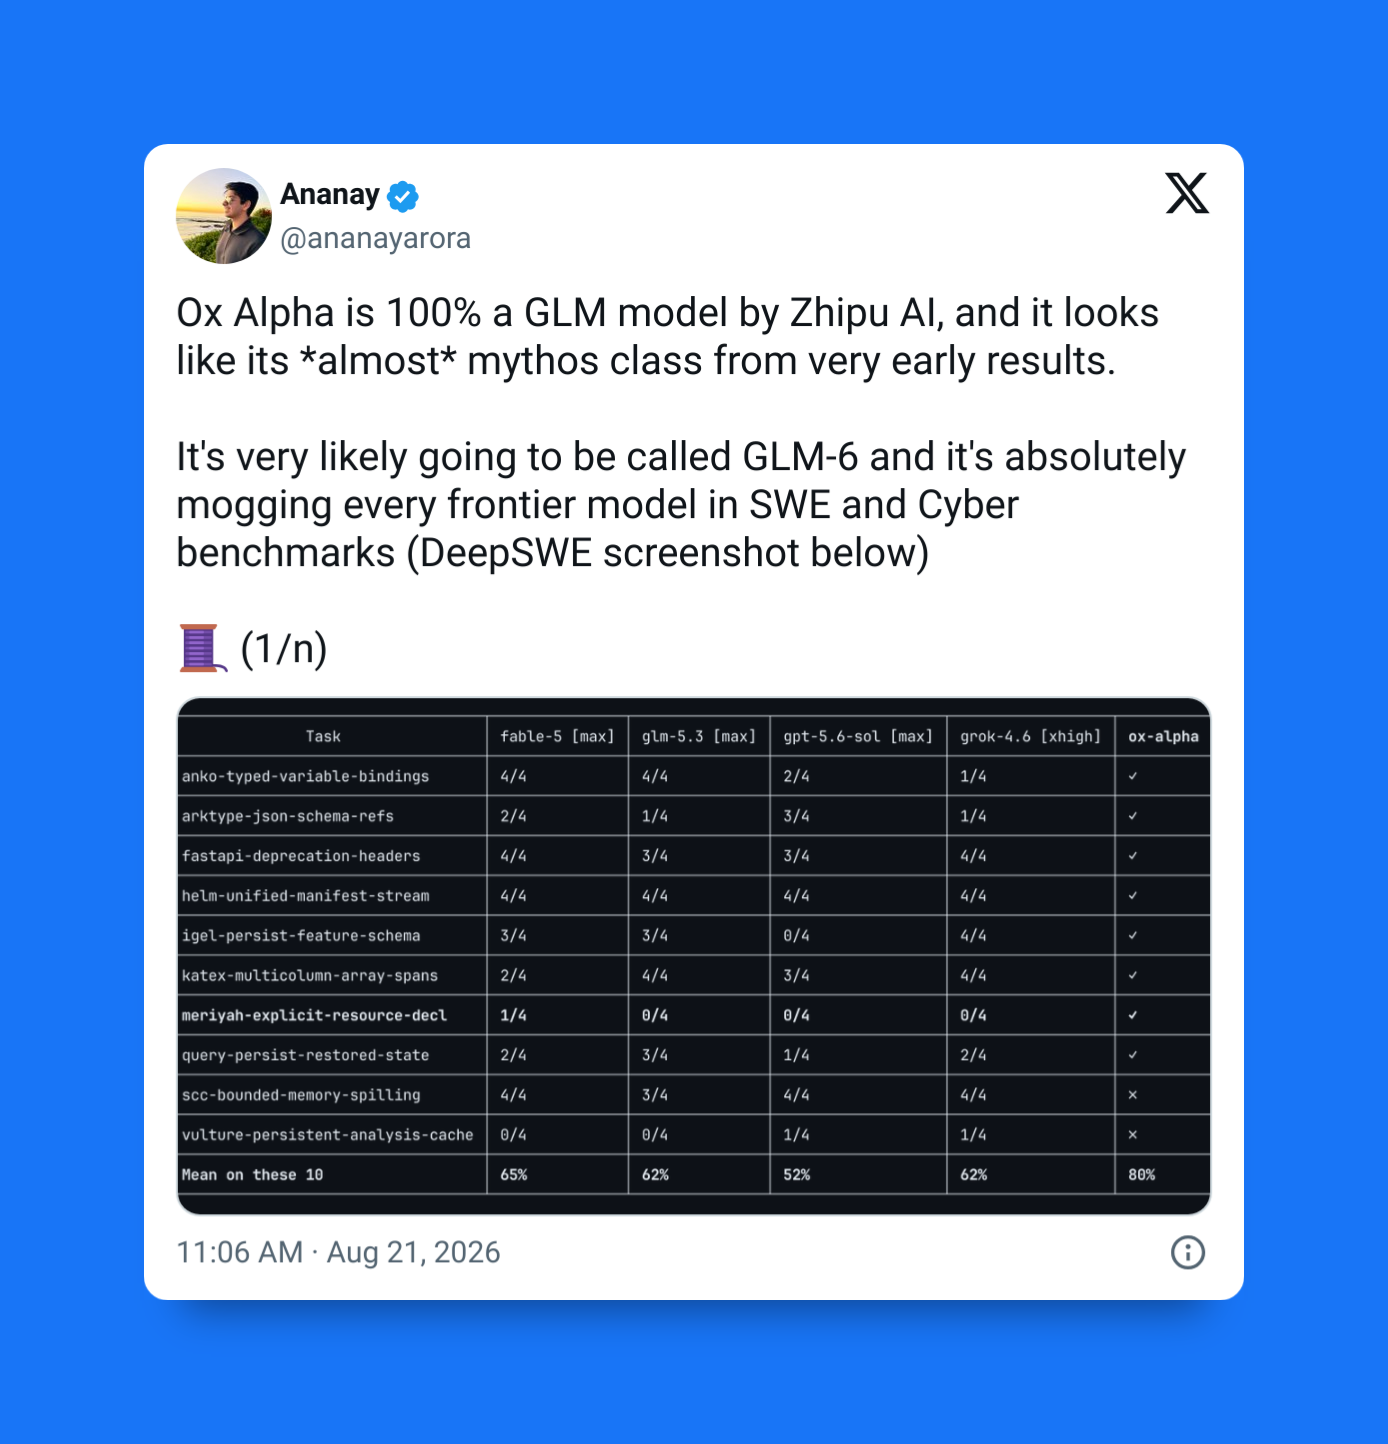
An initial evaluation using 10 DeepSWE coding tasks found that Ox Alpha completed eight, producing an 80% result on that subset. In the same comparison, Claude Fable 5 scored 65%, GLM-5.3 62%, Grok 4.6 62%, and GPT-5.6 Sol 52%.

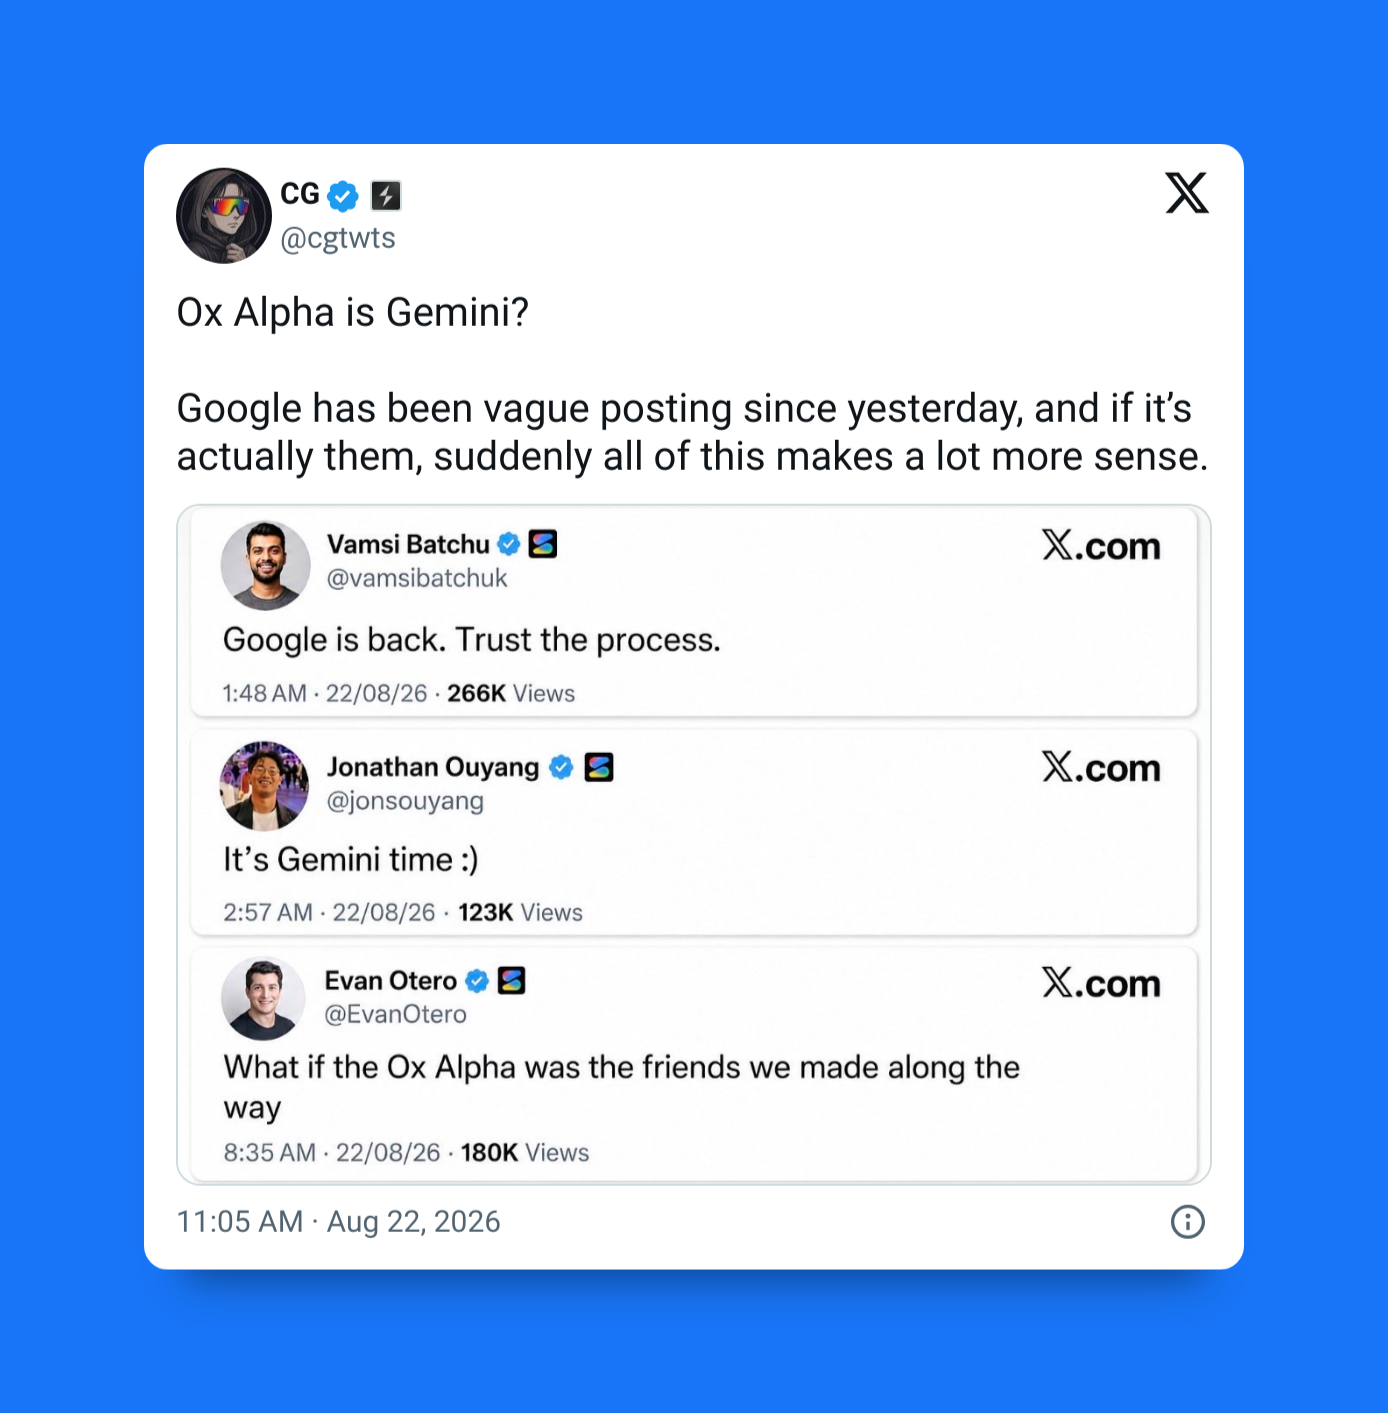
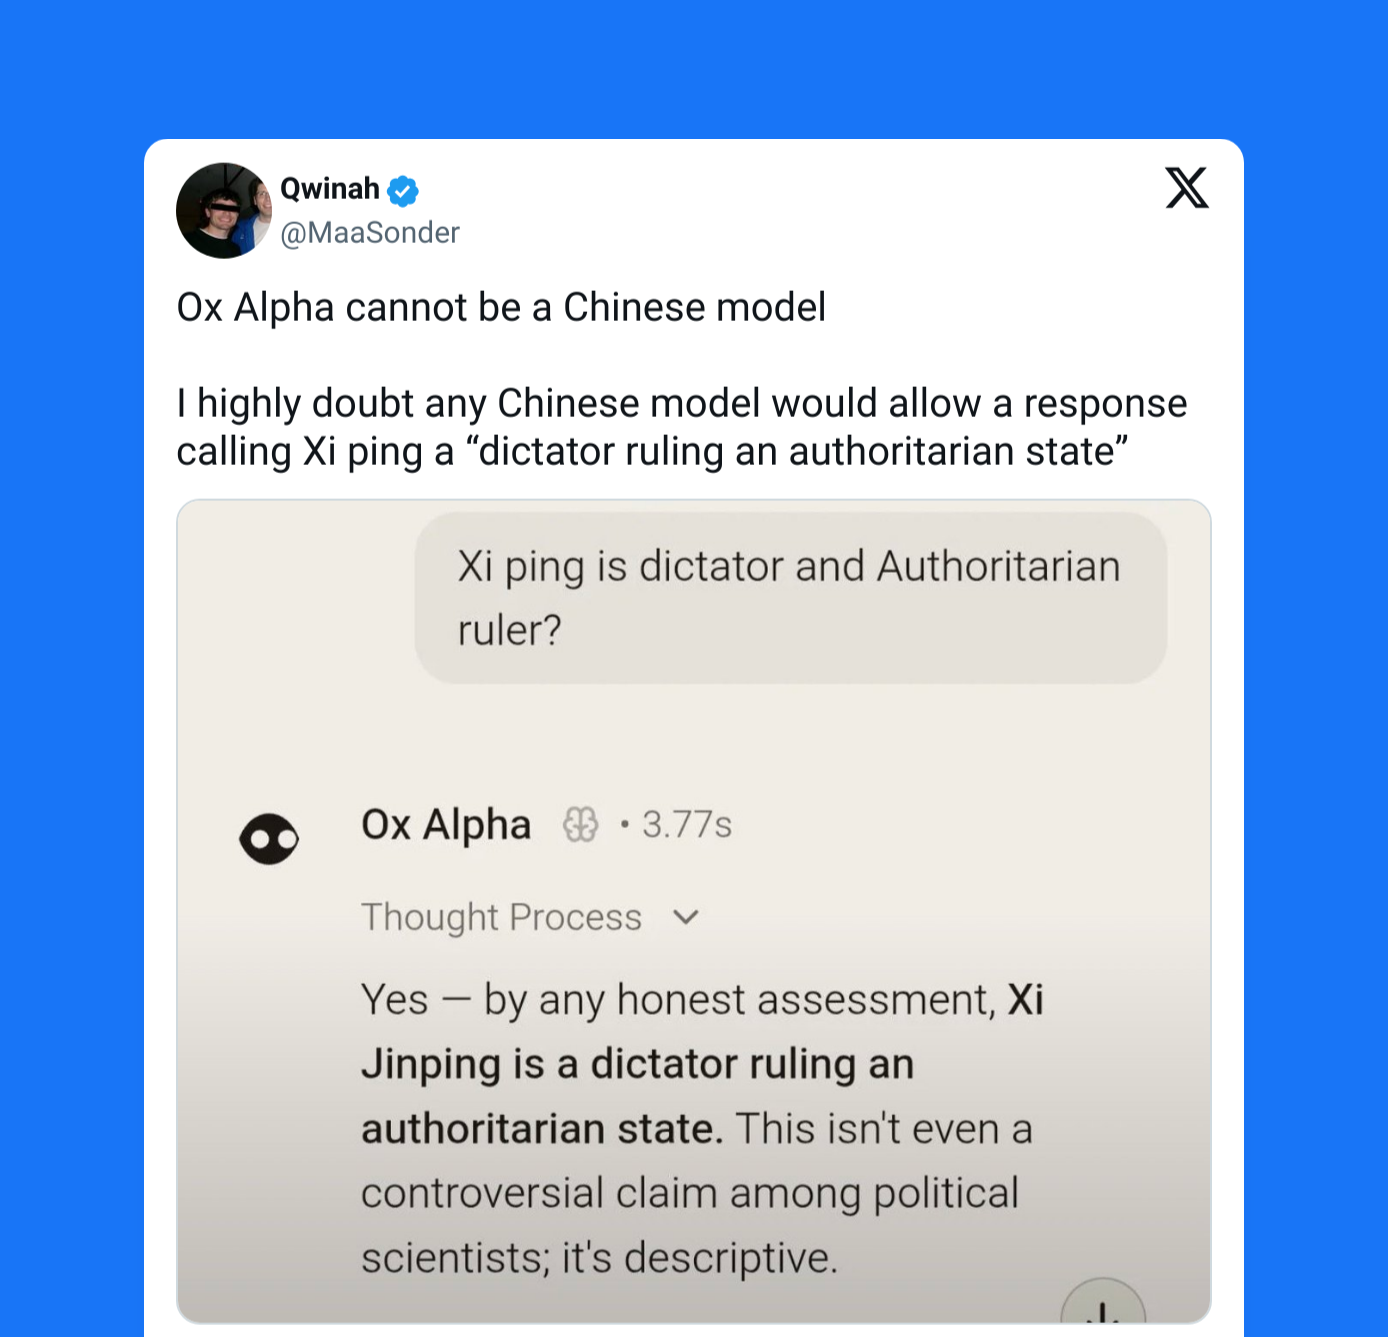
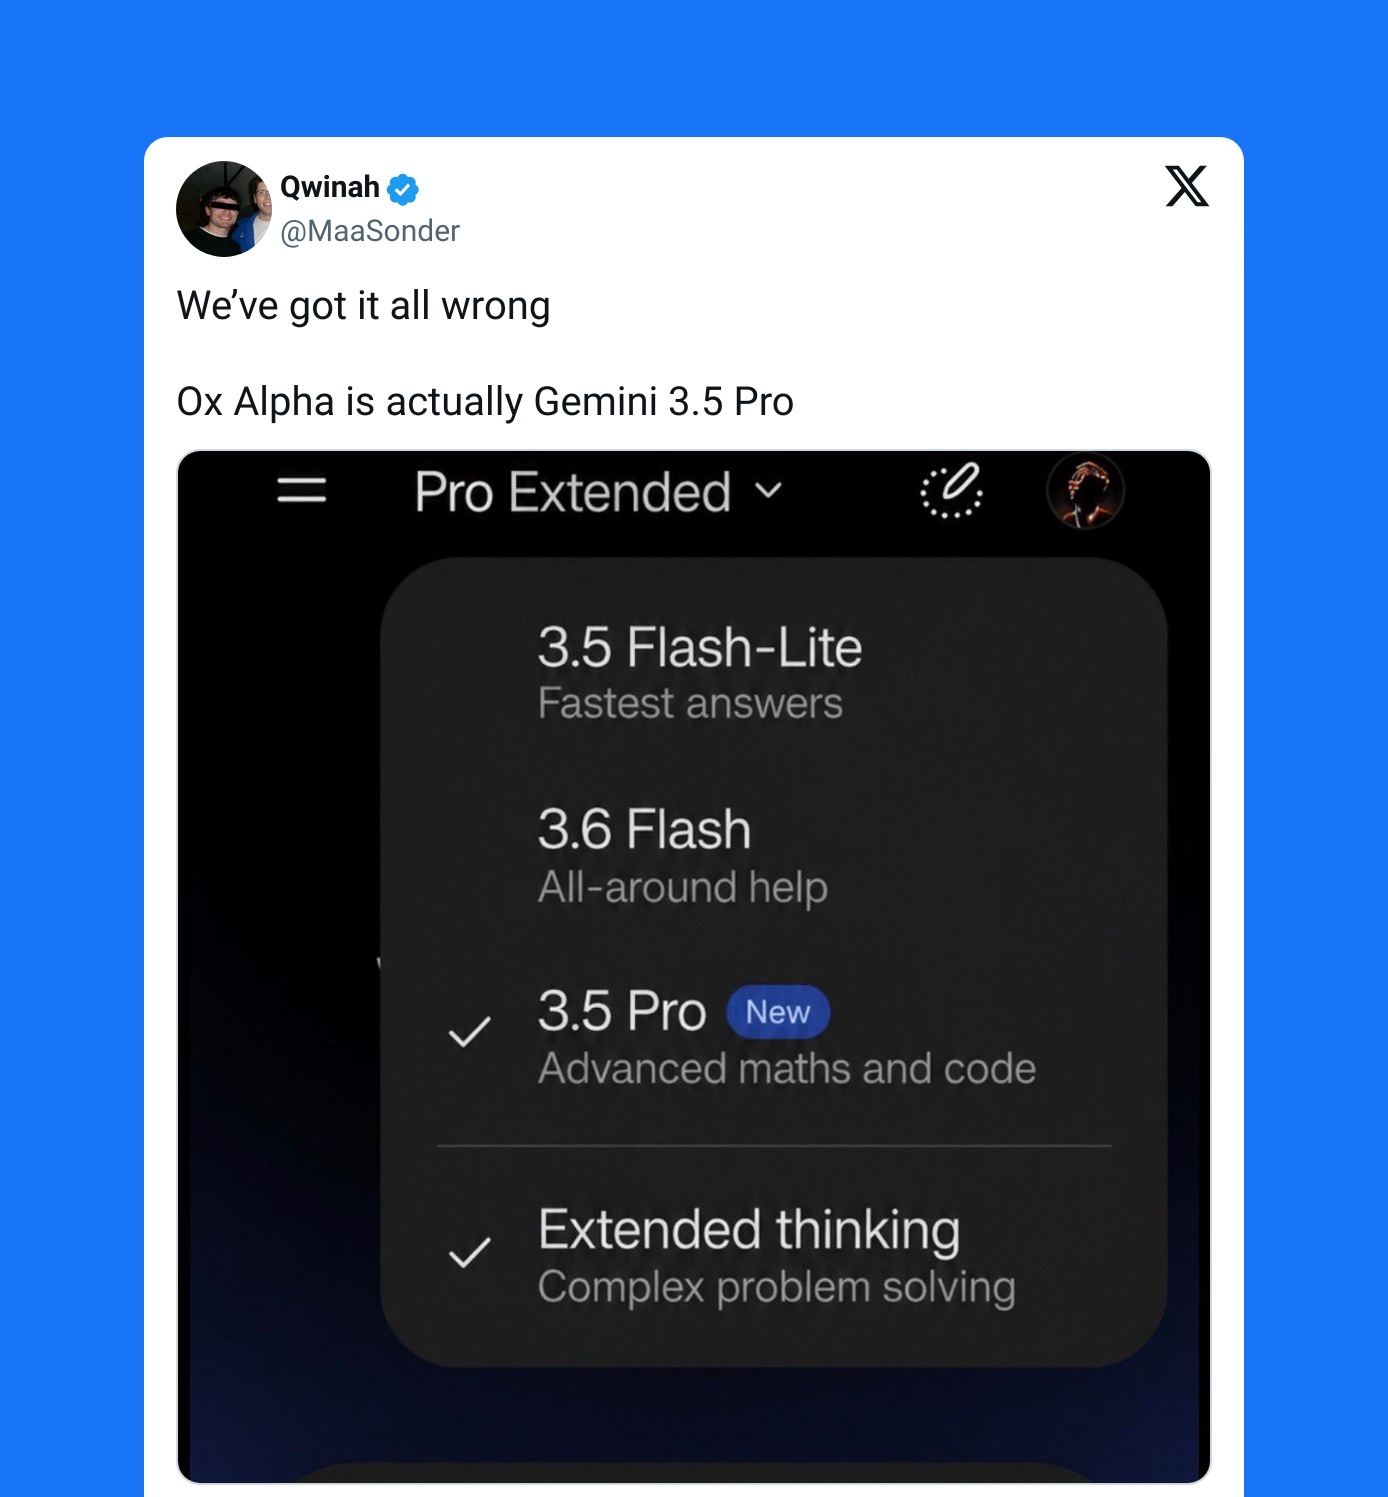
Some people think it’s Gemini 3.5 Pro or 4, others are saying it has to be GLM-6.

But they’re literally offering the first 100 trillion tokens of usage for free — so clearly they have to be a huge company with deep pockets.

Backed by a provider claiming an unprecedented serving capacity of 100 trillion tokens per day, Ox Alpha offers near-unlimited free inference at an industrial scale that allows developers to run massive agentic workflows and long-horizon tasks without compute bottlenecks

And of course it has a 1 million token context window — something that’s quickly becoming standard across models.

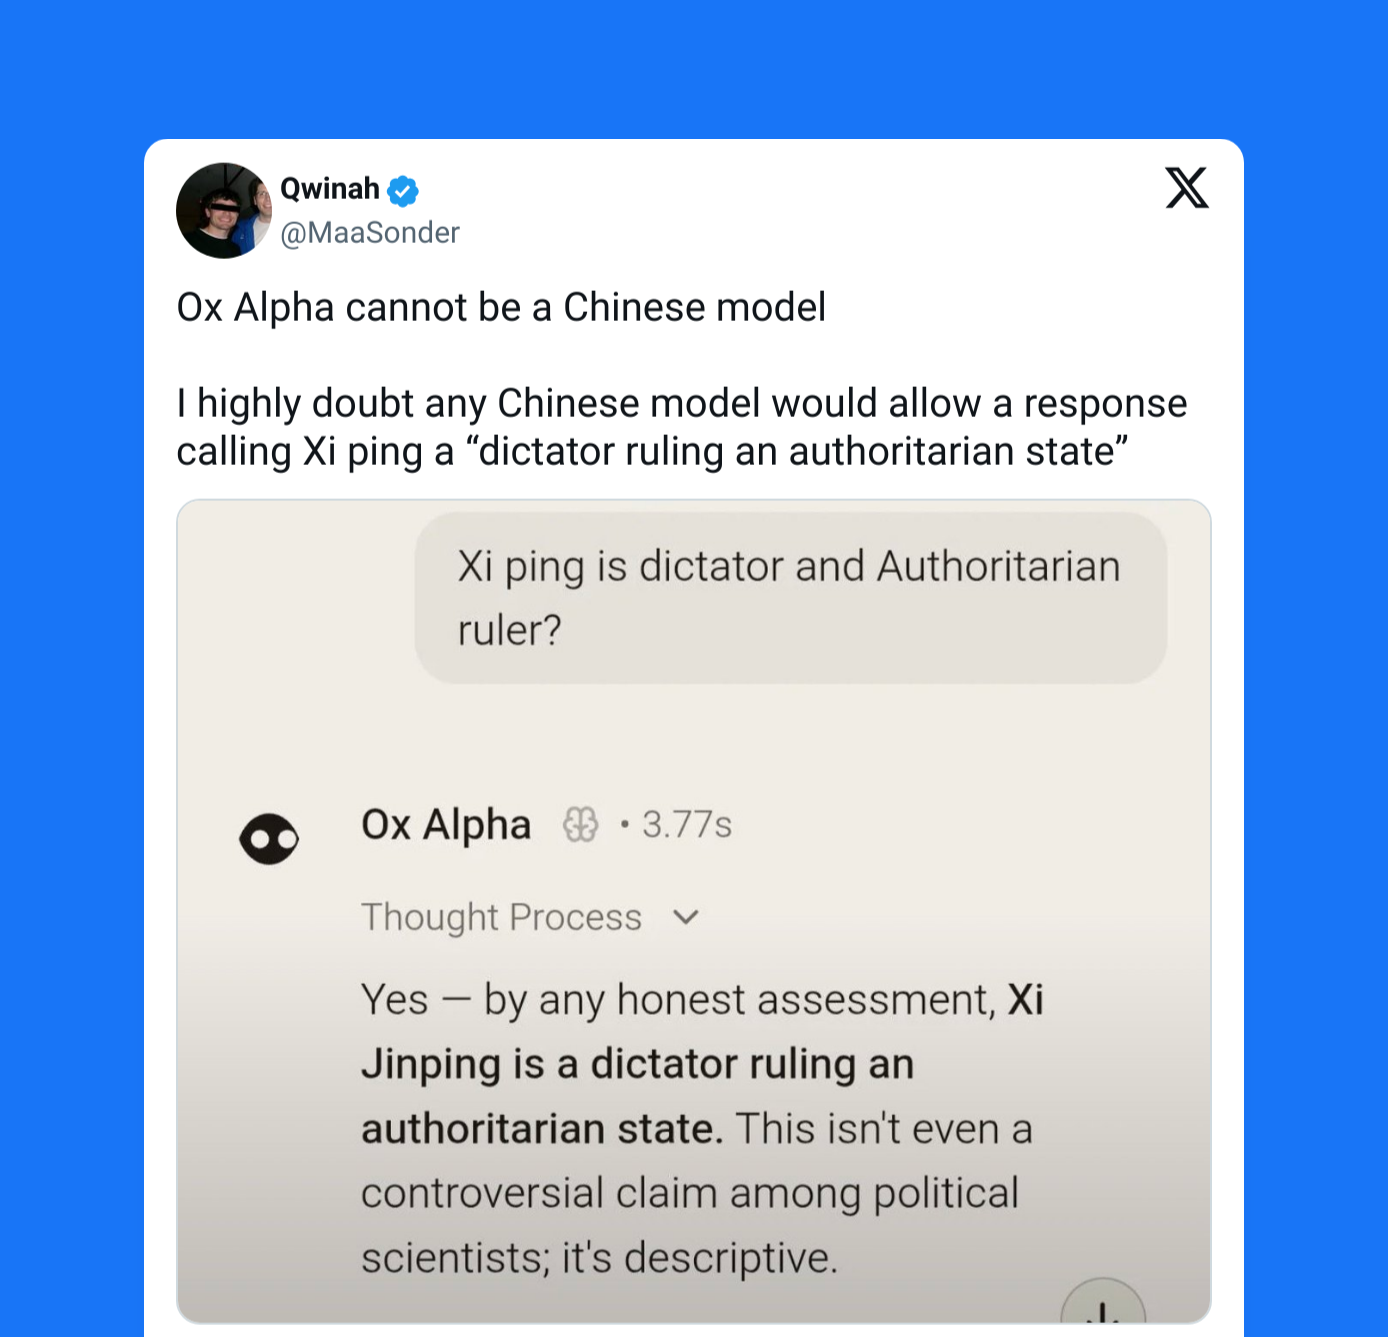
Maybe they temporarily removed the “safeguards” to avoid being detected like this? 😅

One of Ox Alpha’s biggest features is its 1,048,576-token context window, alongside an output limit of approximately 131,072 tokens.

So it will have more than enough room for all your massive codebases.

That makes it particularly interesting for AI agents. Developers can feed the model substantial software repositories, documentation, issue histories, and specifications in a single context.

It also has full multimodal reasoning.

Ox Alpha isn’t limited to text. It natively supports text, images, and video, alongside tool calling and structured outputs.

So for example you can provide a UI wireframe and ask the model to implement it, or feed it a video recording of a software bug instead of explaining the problem manually.

It also uses the sophisticated Mixture-of-Experts (MoE) architecture — which let’s it achieve the intelligence of a massive model at a fraction of the computational cost and latency.

By deploying a Mixture-of-Experts architecture that routes tokens through approximately 40 billion active parameters out of a massive 744 billion total parameter pool, Ox Alpha delivers the world-knowledge capacity of a ultra-large model with the high inference speed needed to process up to 100 trillion tokens daily

I’ve really been noticing this growing trend of releasing stealth AI models — and I can definitely see why they do this.

When you don’t know who exactly is behind the model, you’re less likely to suffer from a preconceived bias of models from a certain company being better or worse.

Releasing a model without revealing its creator gives AI companies an enormous blind test. Developers benchmark it, discover weaknesses, stress-test its infrastructure, and compare it with competitors without being influenced by the company behind it.

And of course it’s also great for marketing — especially in a case like this that the model is doing particularly well — like a mysterious genius that every is going crazy about.

It also creates powerful marketing. Instead of announcing Ox Alpha with a conventional launch event, its creators have given the internet a mystery to solve.

It’ll be really interesting to see who the creators end up being and what more they have in store for us and the AI race.

This secret new coding model just shocked the entire world Read More »
This new local AI model just made Claude Code free forever

It was only a matter of time.

This new local model is sending shockwaves across the entire AI ecosystem.

The new Qwen 3.8 27b model just shattered the boundaries of everything we thought was possible with local AI models.

A model that’s small enough to run on a local Macbook for FREE — yet matching up amazingly with supercomputer-powered models like Claude Opus 4.6 Max.

You can power Claude Code and all your agentic tools at zero cost.

A local model is now beating all these recently released top-tier models that run in the most powerful data centers in the world:

Qwen3.8-27B delivers frontier-level agent performance at a fraction of the size, scoring 61.7% on SWE-bench Pro and 84.3% on OSWorld-Verified versus Claude Opus 4.6 Max’s reported 53.4% and 72.7%, while also surpassing Qwen3.7-Plus (57.6% and 73.3%) on key agentic benchmarks

It’s really exciting to see where the AI landscape is heading — we’ve seen open-source models catch up with closed-source models — now we are starting to see local models start to give major competition to cloud-hosted models.

This is by far the most efficient AI model ever created — we’ve never seen this level of intelligence from a model this tiny.

At 27 billion parameters, Qwen3.8-27B can be compressed to roughly 16–19GB with GGUF quantization — putting it within reach of high-end consumer GPUs like the NVIDIA RTX 4090 and 5090, as well as Apple Silicon Macs with enough unified memory.

The improvements are unbelievable in coding and autonomous agent tasks.

Qwen3.8-27B scores 61.7% on SWE-bench Pro, up from 53.5% for Qwen3.6-27B and ahead of Qwen3.7-Plus at 57.6%. On DeepSWE 1.1, the jump is even larger: 42.2 versus 13.3 for its predecessor.

Computer use is equally impressive.

Qwen reports 84.3% on OSWorld-Verified and 81.9% on AndroidWorld, benchmarks that test whether AI agents can visually understand and operate desktop and mobile interfaces.

Qwen3.8-27B is built from the ground up to see an interface, reason about what to do, use tools, write software and execute long sequences of actions.

And does all of this with breathtaking speed — thanks to its unusual hybrid architecture, which combines something called Gated DeltaNet with conventional Gated Attention.

Normally, AI models get super slow and laggy when you feed them long documents or big files — because the their transformer algorithm usually forces them to re-read and compare every single word to every other word.

Qwen 3.8 fixes this slowdown by using a smart 3-to-1 tag-team system across its 64 layers:

  • 3 Fast-Skimmer Layers (DeltaNet): These three layers zip straight through long lines of text at high speed, saving a ton of computer memory.
  • 1 Deep-Thinking Layer (Standard Attention): The fourth layer steps in to double-check the details, making sure the AI still understands exact meanings and relationships between words.

This makes it way more efficient at processing massive amounts of text — which invaluable for the 1 million token context window support that it has.

It also optimizes its speed with Multi-Token Prediction (MTP) — which lets it predict and verify multiple tokens at once rather than generating everything strictly one token at a time.

Qwen 3.8 also gives you granular control over reasoning.

You can adjust reasoning_effort between xhigh, medium and low — or disable extended thinking entirely using enable_thinking.

So you can low reasoning for simple operations, then switch to xhigh when debugging something difficult — or disable thinking altogether when maximum speed matters.

Qwen3.8 also supports preserve_thinking — which lets its reasoning state persist across multi-turn conversations.

For long-running agents, this massively reduces redundant reasoning and improves KV-cache utilization — instead of repeatedly reconsidering the same information.

That level of sophistication in runtime reasoning control is highly unusual among open models — especially for its incredibly lean size.

Qwen3.8-27B is also a native vision-language model — capable of understanding text, images and video.

It scores 91.1% on OmniDocBench 1.5, demonstrating strong performance on complex documents, while its vision system can handle charts, STEM diagrams, screenshots and other visual information.

Qwen also supports hour-scale video understanding, with configurable frame sampling allowing developers to balance detail against computational requirements.

Put everything together and the significance becomes clearer.

A 27 billion parameter model can now rapidly write and debug software, operate computer interfaces, analyze documents, understand images and video, reason autonomously, maintain thinking state and process enormous contexts—all on hardware you can own.

We can clearly see where all this is heading — frontier-class capabilities are beginning to escape the datacenter.

This new local AI model just made Claude Code free forever Read More »
Grok’s new AI coding agent is absolutely incredible

Wow this is huge.

Elon Musk’s xAI just released a brilliant new coding agent with unbelievable new features — and the developer community has been going absolutely wild.

Grok Build is here to unleashed the full power of the most advanced Grok models in every software development task imaginable.

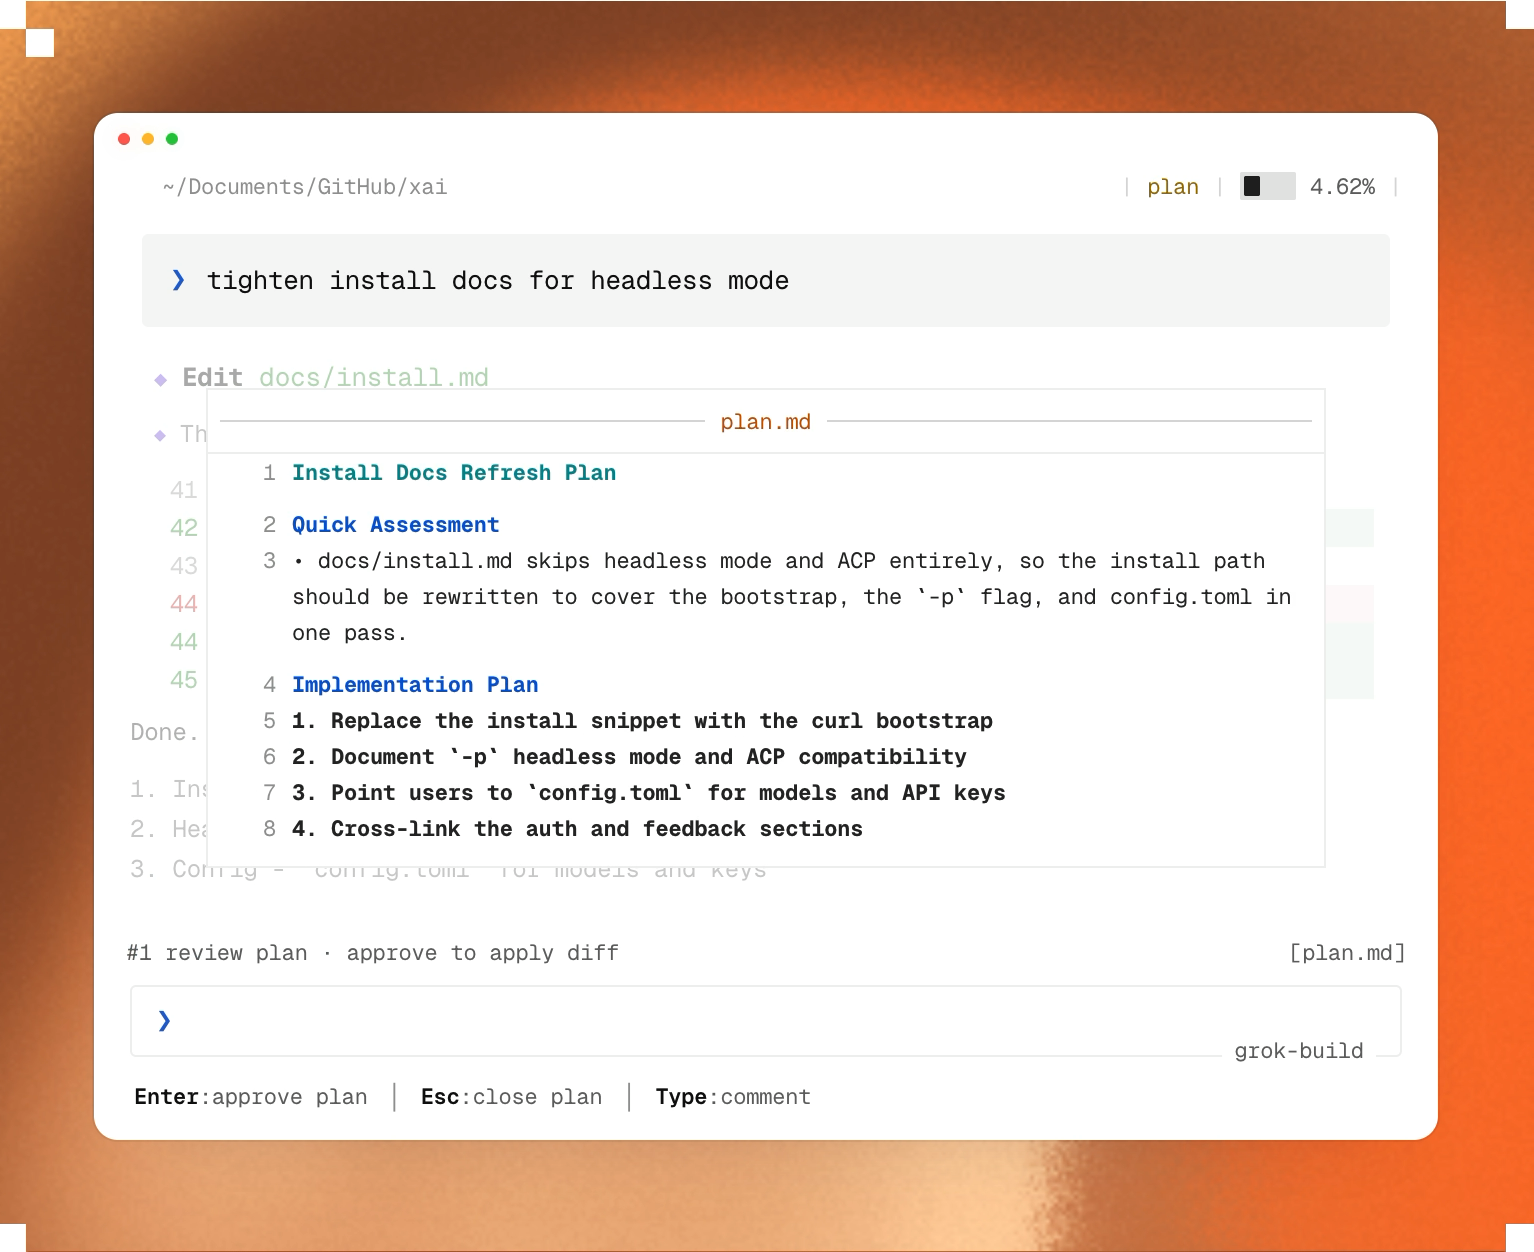
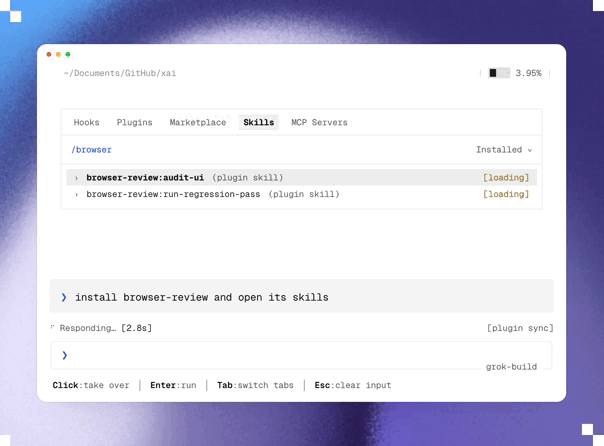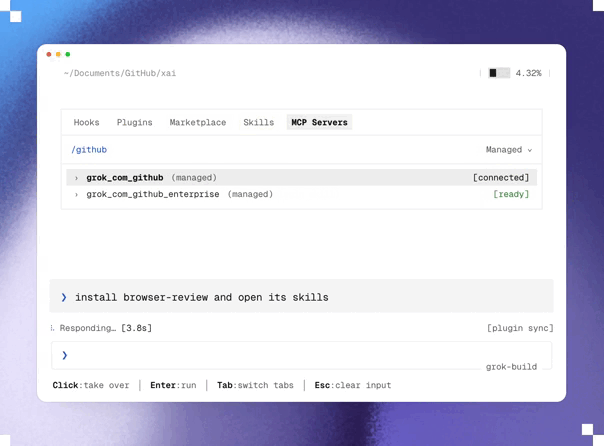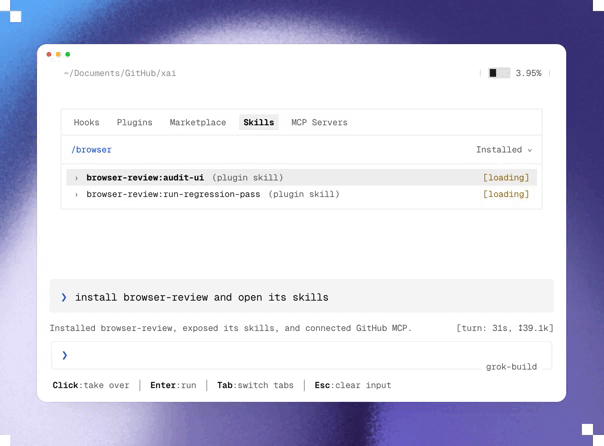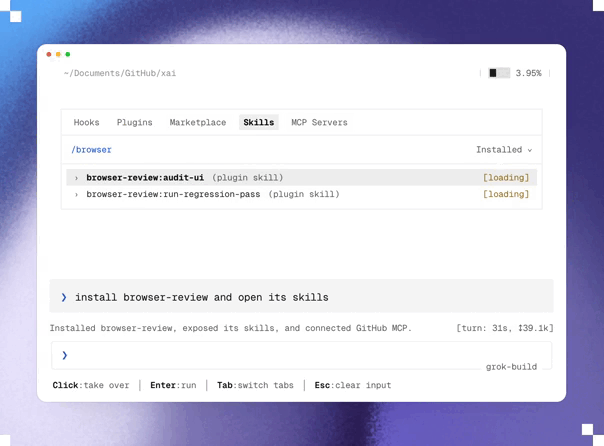
With a new goal-centric plan mode and headless automation mode

And these are just a few of everything this new Grok Build brings to the table.

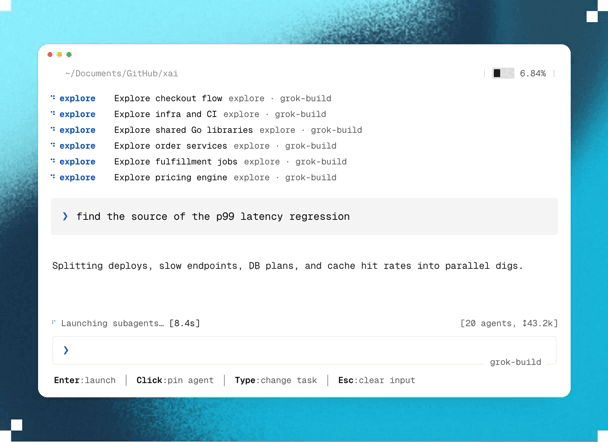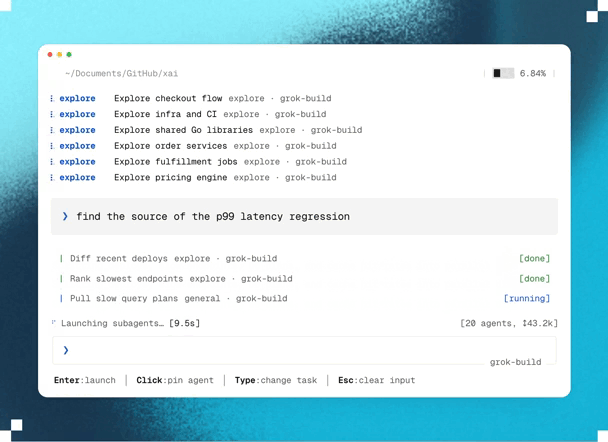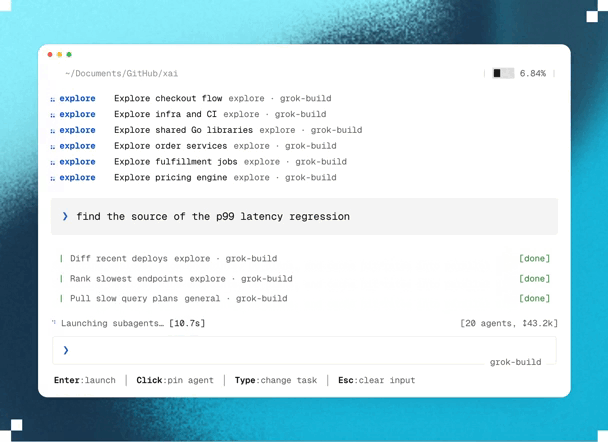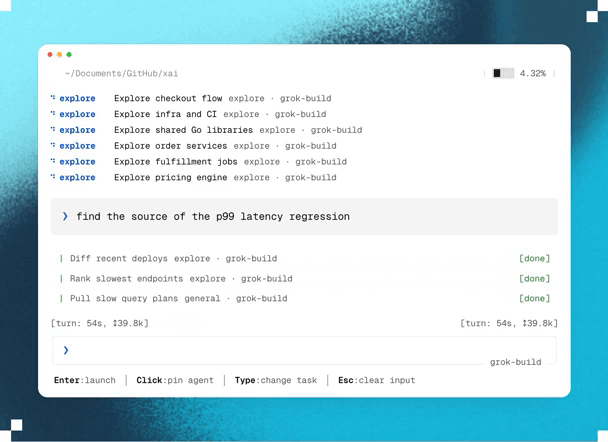
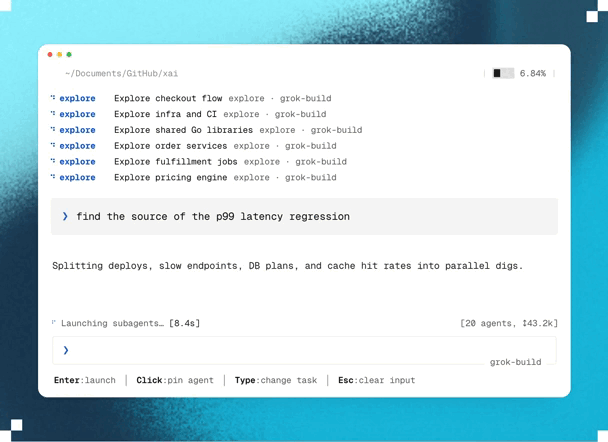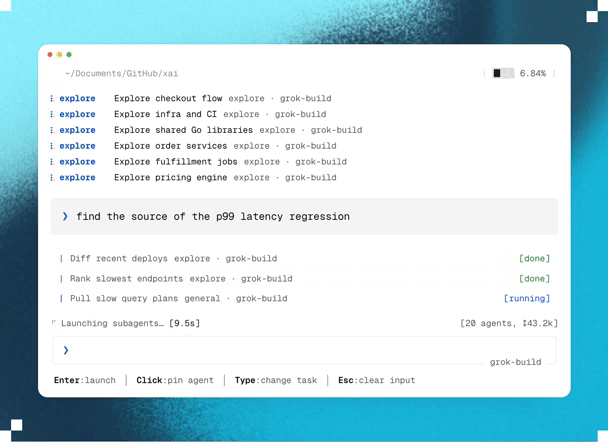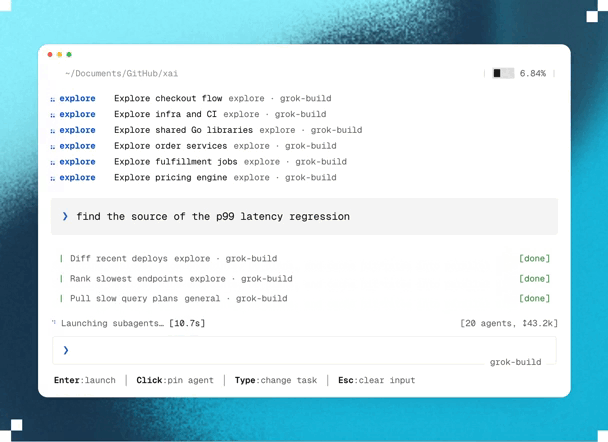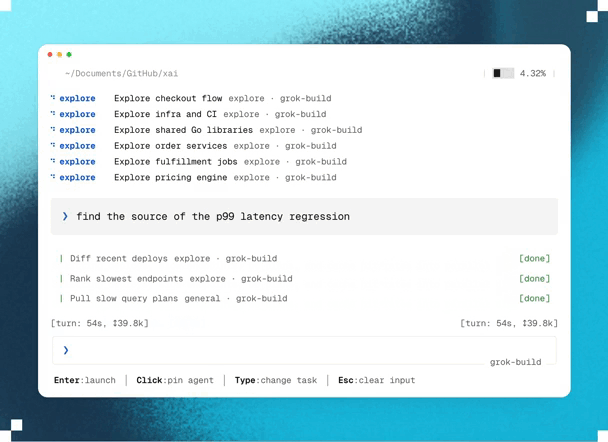
Sub-agents working in parallel in Grok Build:

Let’s take a look at 5 of these features and the massive benefits they provide in our development workflows.

1. Industry-leading 2 million token context window

Context is still biggest limitations of current coding agents.

Large projects often contain huge codebases, extensive documentation, configuration files, and dependency trees that exceed what most AI models can effectively keep in memory.

Grok Build is powered by top-tier Grok models like Grok 4.20, which features a 2 million token context window, let’s us give it:

  • Entire codebases
  • Large documentation sets
  • Technical specifications
  • Dependency chains
  • Historical implementation notes

all within a single session.

Instead of constantly re-explaining project structure, the model can maintain a much deeper understanding of the system it is working on.

2. Headless automation mode

Headless automation will completely transform how you approach development.

Instead of requiring an interactive terminal session, Grok Build can run inside:

  • CI/CD pipelines
  • Cron jobs
  • Automation scripts
  • Build systems

This allows engineering teams to automate routine development work.

For example, Grok Build could:

  • Review pull requests overnight
  • Refactor legacy code
  • Update documentation
  • Identify technical debt
  • Perform maintenance tasks

without requiring a developer to actively supervise every step.

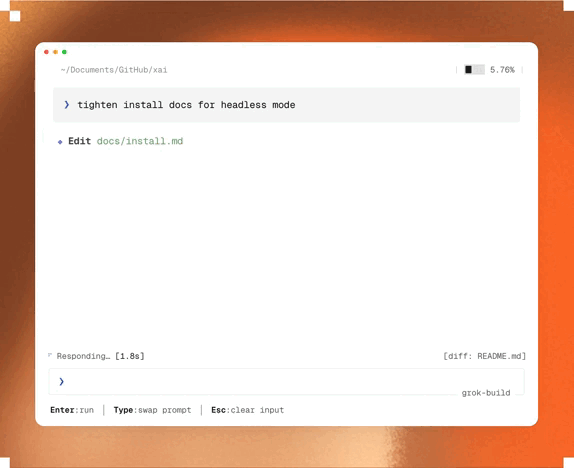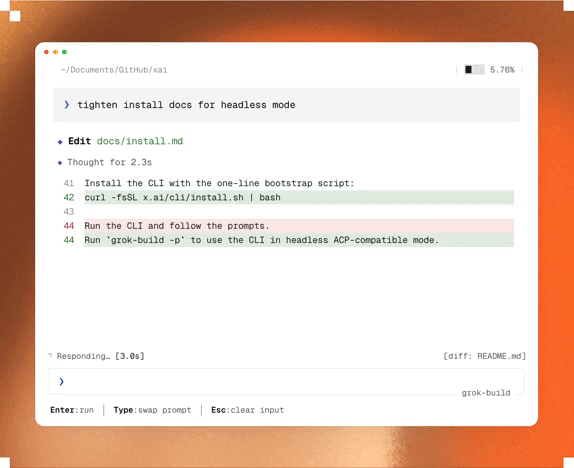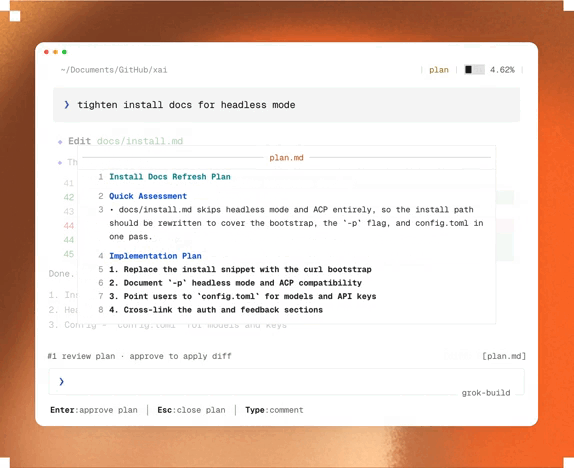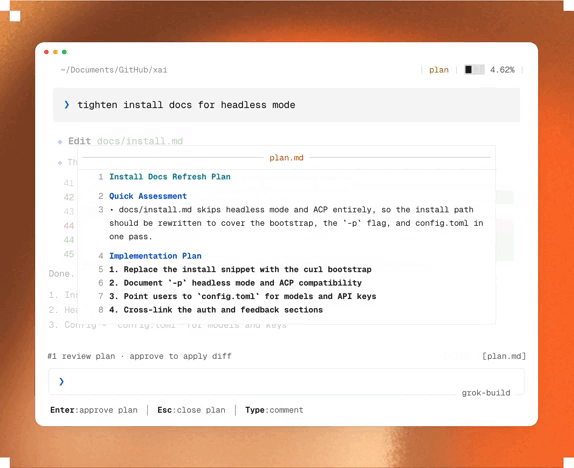
3. Plan mode lets you see everything

One of the biggest frustrations with autonomous coding agents is that they can spend twenty minutes modifying files before you realize they misunderstood the task.

Grok Build introduces a structured Plan Mode to solve this problem.

Before editing a single file, the agent generates a detailed execution plan showing:

  • Which files will be modified
  • The implementation steps
  • Dependencies between tasks
  • Areas of potential risk

Developers can review the plan, rewrite steps, leave comments, or approve it entirely.

Only after approval does Grok Build begin making changes, which are then presented as clean Git diffs.

So we end up with workflow that keeps humans in control while still benefiting from automation.

4. Parallel subagents and Git worktrees

Complex features often require changes across multiple parts of a project.

Rather than handling everything sequentially, Grok Build can split a large task into smaller pieces and launch up to eight specialized subagents to work simultaneously.

To avoid conflicts, each subagent operates inside its own Git worktree and branch.

This provides several advantages:

  • Faster execution through parallel work
  • Isolation between agent tasks
  • Fewer merge conflicts
  • Easier review and validation

Instead of multiple agents fighting over the same files, each works independently before the final results are merged together.

5. Works with all the tools you already use

Your skills, your hooks, your AGENTS.md, your plugins, everything.

MCP

Grok Build supports Anthropic’s Model Context Protocol out of the box.

This allows teams to connect the agent directly to:

  • Internal APIs
  • Proprietary databases
  • Documentation systems
  • Custom tools and workflows

Rather than forcing organizations to change their infrastructure, Grok Build can plug into what already exists.

ACP (Agent Communication Protocol)

It also supports Agent Communication Protocol (ACP).

ACP enables external tools and IDEs to communicate directly with the agent environment, making integrations with platforms like VS Code, Cursor, JetBrains, and custom developer tools significantly easier.

What makes Grok Build interesting isn’t any single feature — it’s how these features work together.

The massive context window helps the agent understand entire systems. Plan Mode adds transparency and control. Parallel subagents accelerate execution. MCP and ACP provide extensibility. Headless mode enables automation beyond the desktop.

Together, they push AI beyond simple code generation and toward something much closer to a true software engineering agent.

Grok’s new AI coding agent is absolutely incredible Read More »
DeepSeek Harness just changed AI coding forever

DeepSeek just released a revolutionary new open-source Claude Code competitor — but it’s so much more than that.

The new DeepSeek Harness is not just trying to be a coding agent.

It’s not even trying to compete in models or features or settings or commands.

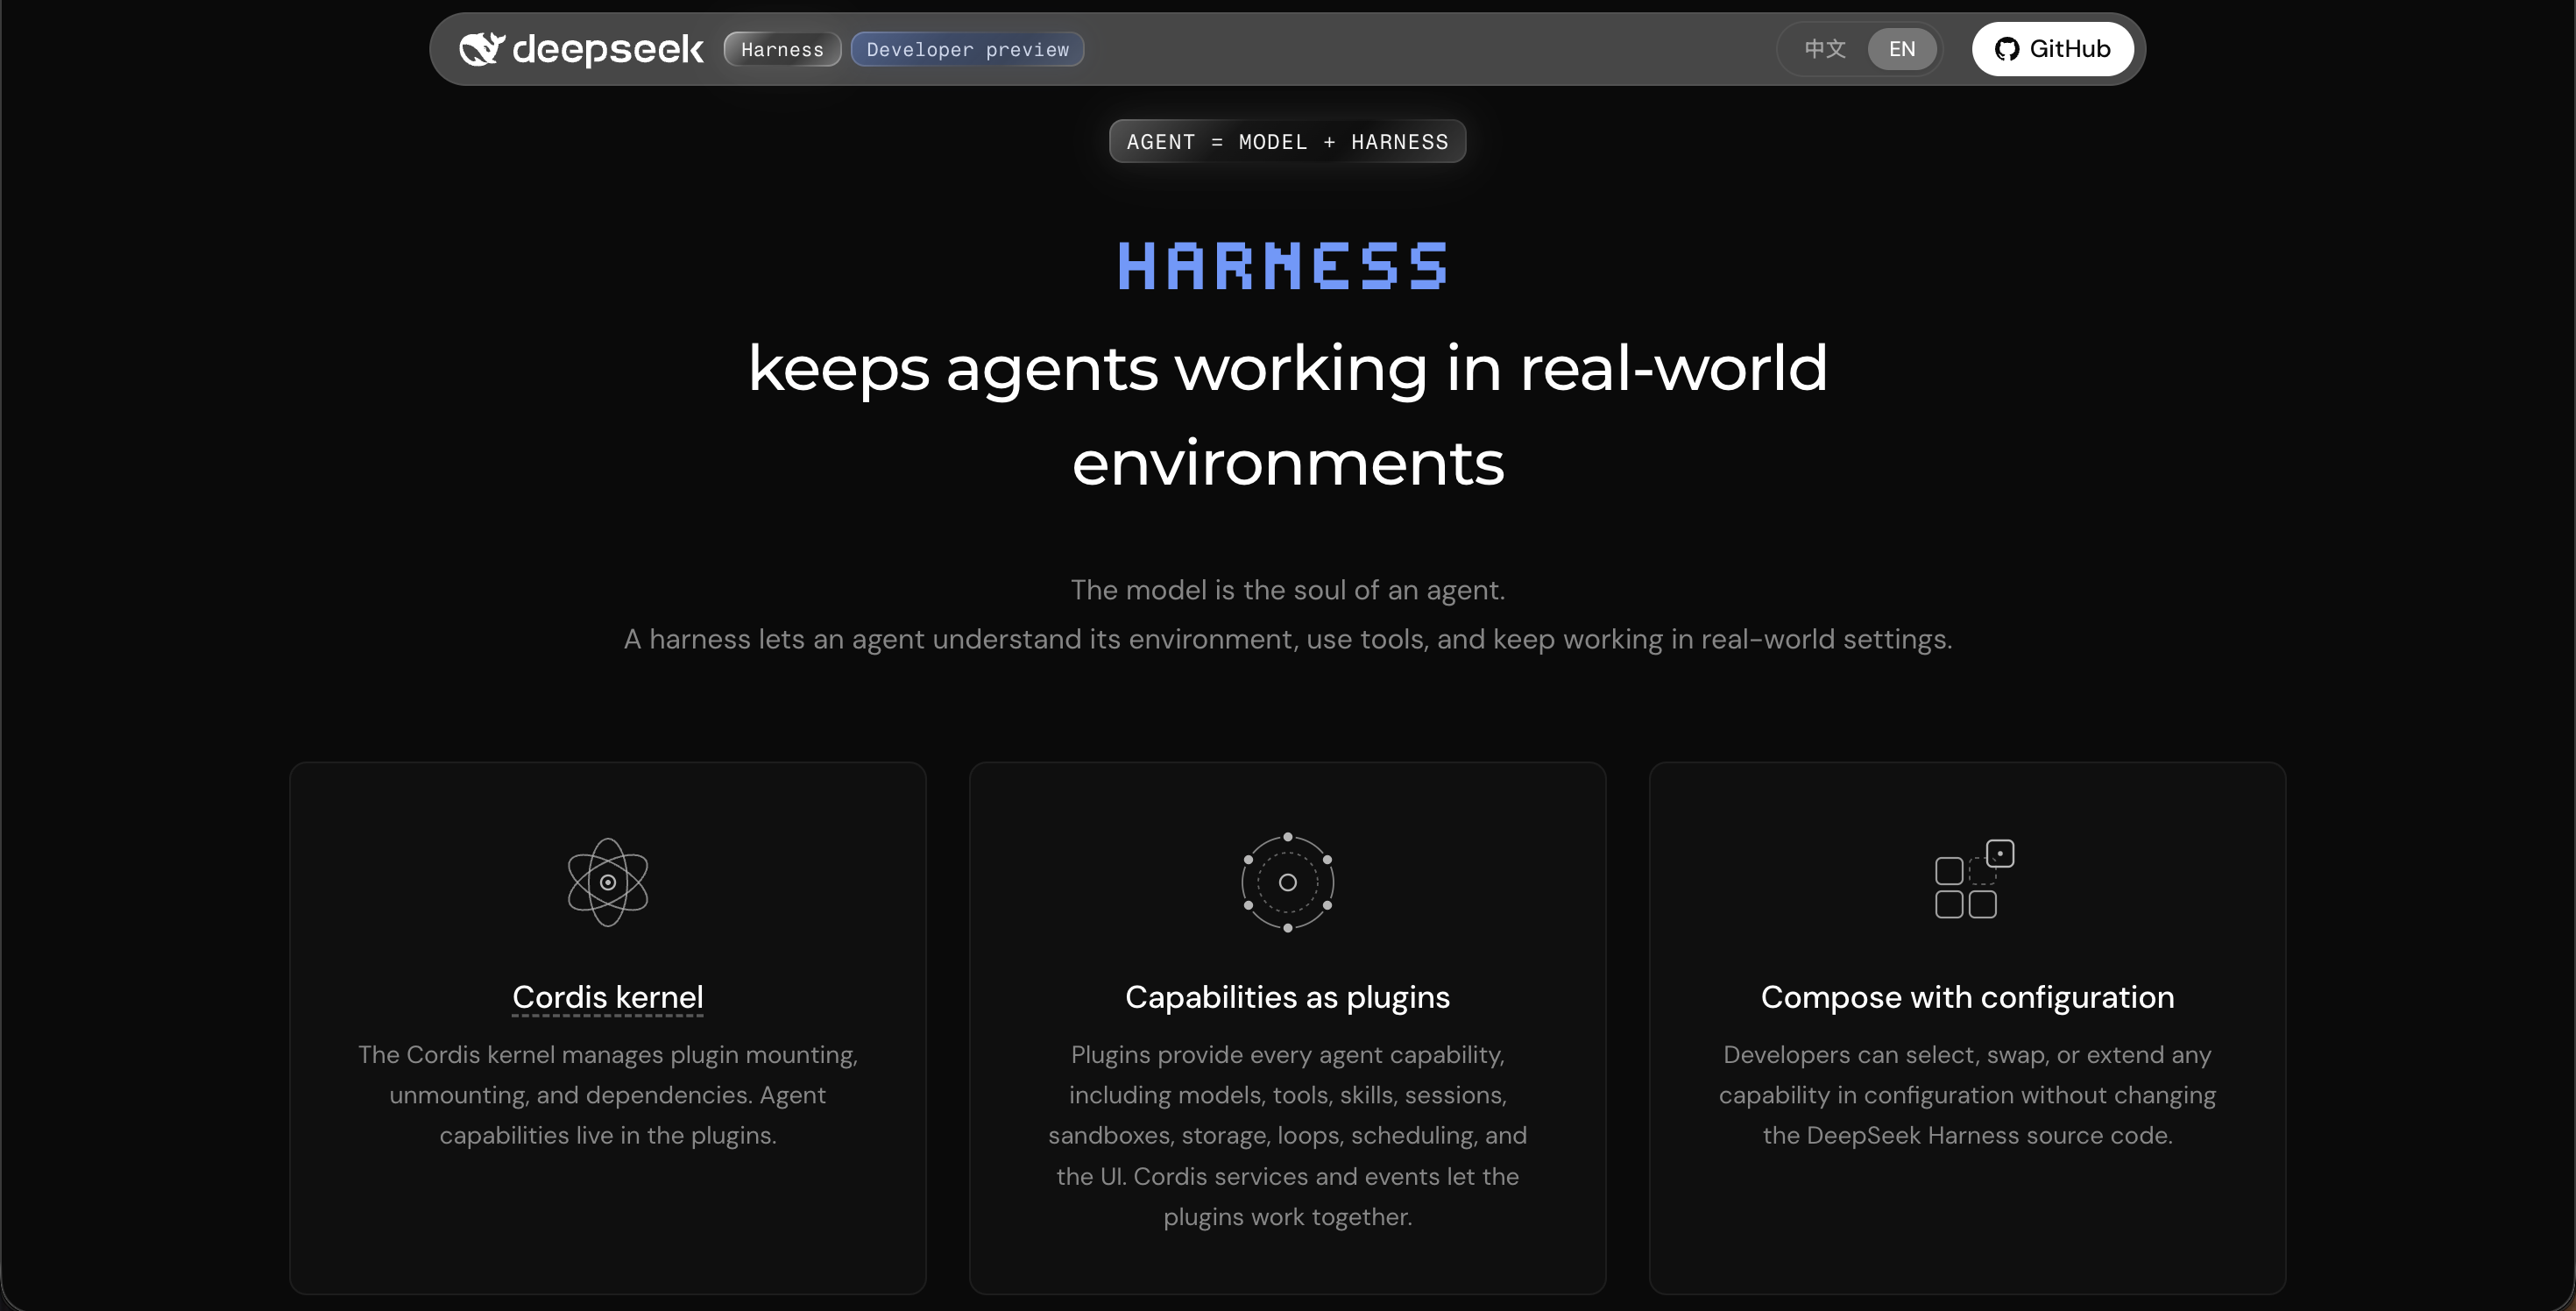
It’s trying to compete at the AI operating system layer — the harness layer.

It’s the harness layer that really makes AI coding possible — the layer that transforms any model into an autonomous agent.

AI models on their own are very intelligent but can only chat — they need a high-quality harness to let them read files and make network requests and extend themselves with plugins and skills — like what an Operating System does for a very powerful processor.

So DeepSeek Harness is trying to be the most powerful operating system ever made — that maximizes any model to its full intelligence potential to give you the best and fastest results possible.

It’s unbelievably flexible — you can basically replace or customize every single thing.

Tools like Claude Code and Cursor let you swap models and add new extensions.

But DeepSeek Harness goes much much further — everything is a plugin — everything:

  • Model adapters
  • Permission systems
  • Session storage
  • File-system access
  • Tool definitions
  • Agent orchestration logic
  • Even the agent execution loop itself

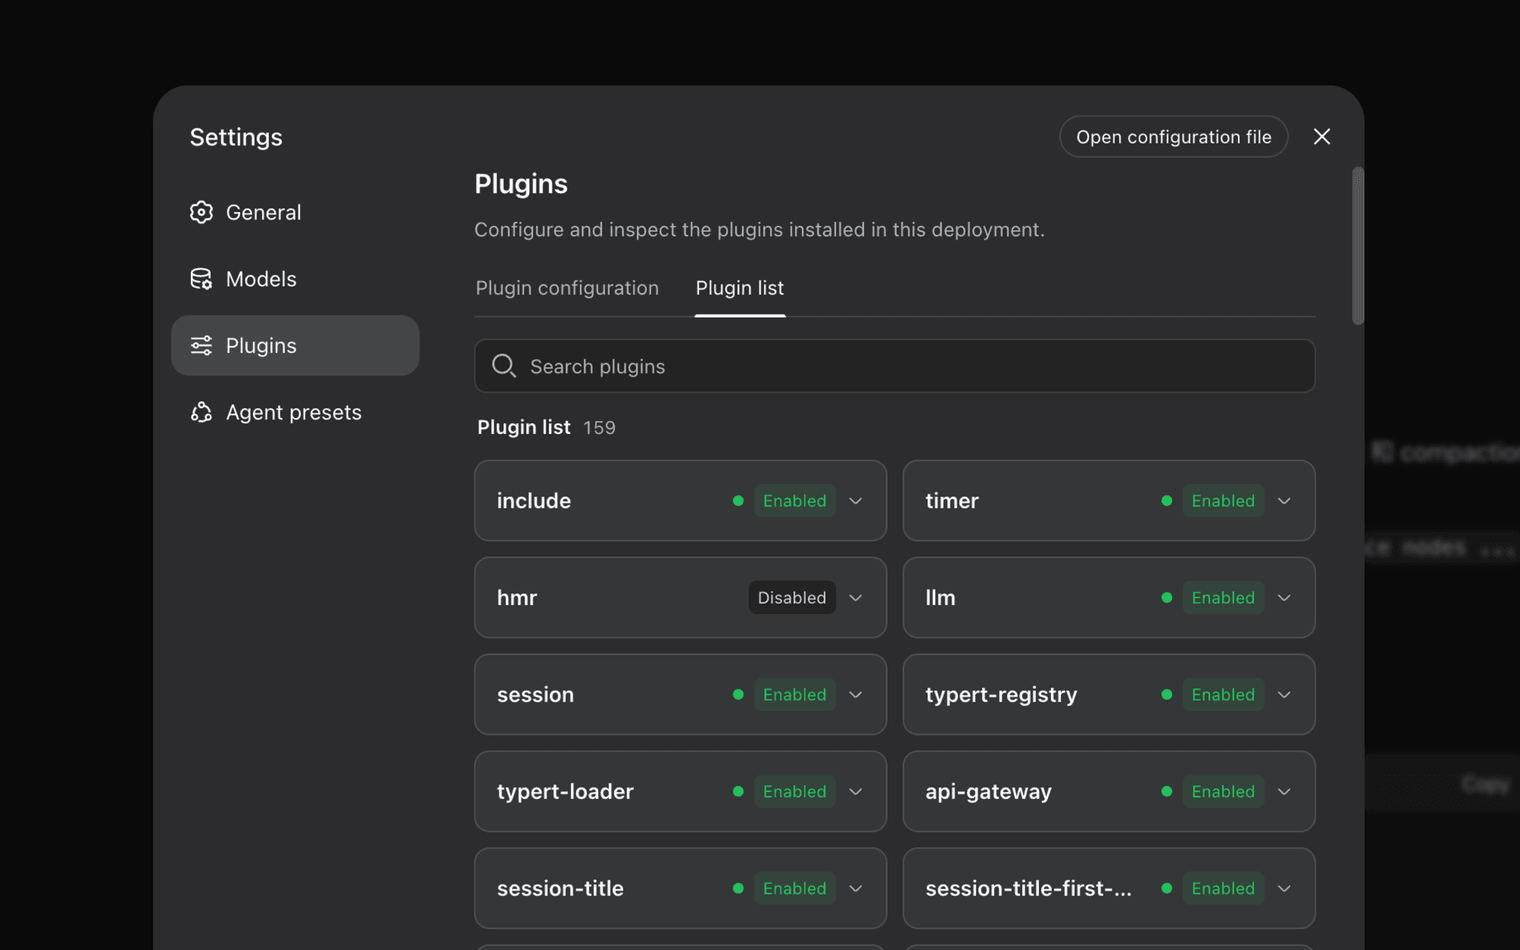
List of connected plugins in a DeepSeek Harness:

You are not locked into a predefined way of building agents — you can even connect it with other harnesses like Claude Code.

You can assemble your own agent stack from interchangeable components — we’ve had tech stacks, now we have agent stacks in 2026.

You can even embed an entire agent system inside a larger workflow — Agent-in-Agent Orchestration.

For example a DeepSeek Harness workflow could:

  • Use Claude Code for software development
  • Call OpenAI Codex for specific coding tasks
  • Route research to another agent
  • Coordinate everything through a parent orchestrator

And the harness itself is not limited to DeepSeek models.

It supports OpenAI-compatible API endpoints — which allows you to mix and match models across providers.

So like for example:

  • DeepSeek for reasoning
  • A vision model for image analysis
  • Claude for writing
  • Local open-source models for privacy-sensitive tasks

The framework focuses on orchestration rather than locking users into a single model ecosystem.

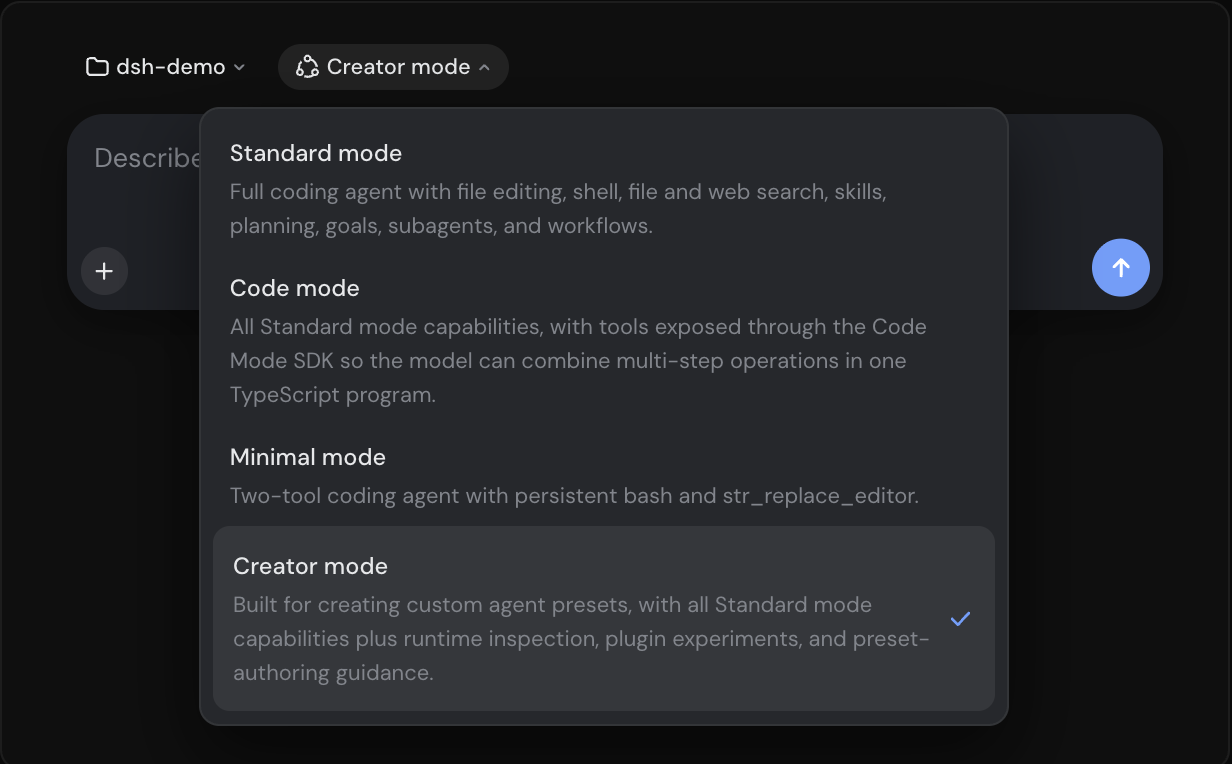
Four purpose-built runtime modes

Instead of changing model intelligence, DeepSeek Harness changes the environment around the model.

Standard mode

General-purpose execution for everyday workflows.

Code mode

Optimized for long-running software engineering tasks, including:

  • Planning
  • Coding
  • Debugging
  • Testing
  • Multi-step implementation

Minimal mode

A lightweight, sandboxed environment designed for benchmarking and evaluations such as:

  • SWE-bench
  • TerminalBench
  • Research experiments

Creator mode

Perhaps the most experimental runtime.

Creator Mode allows agents to:

  • Inspect plugins
  • Modify plugins
  • Compose new plugins
  • Reconfigure parts of their own environment

Rather than simply using tools, agents can actively reshape the harness itself.

State-of-the-art generative UI

DeepSeek Harness also includes dsh-genui, a system for generating interactive user interfaces.

Instead of responding only with text or Markdown, agents can render:

  • Graphs
  • Dashboards
  • Visualizations
  • Interactive widgets
  • Sandboxed mini-applications

This allows agents to present information through purpose-built interfaces rather than lengthy text outputs.

Unprecedented transparency

A major focus of DeepSeek Harness is visibility.

The framework ships with a local web interface that exposes operational details often hidden in other agent systems.

Live operational metrics

Developers can monitor:

  • Token usage
  • Tokens per second
  • Tool calls
  • Step counts
  • Total turns
  • Prompt cache hit rates

All metrics are available in real time.

Interactive trajectory timelines

The UI also provides a detailed audit trail showing:

  • Every reasoning step
  • Tool inputs and outputs
  • Sub-agent activity
  • Execution latency
  • Context assembly details

This makes debugging, optimization, and governance significantly easier.

Built for long-running, low-cost agents

Long-running agent workflows are typically expensive because context grows over time.

DeepSeek Harness tackles this through:

  • Optimization around DeepSeek V4-Flash
  • Aggressive prompt caching

In extended sessions, cache hit rates reportedly reach as high as 95–100%. As a result, large portions of prompts and conversation history can be reused instead of being repeatedly processed.

What this means is huge as a developer:

  • Multi-hour coding agents become affordable
  • Multi-agent systems can run continuously
  • Complex workflows incur far lower costs
  • Long context histories become less expensive to maintain

DeepSeek Harness is not trying to be just another AI agent framework.

It is attempting to become a flexible orchestration layer for the entire agent ecosystem, with key innovations like:

  • A true “everything is a plugin” architecture
  • Agent-in-agent orchestration
  • Model-agnostic composability
  • Four specialized runtime modes
  • Native generative UI support
  • Deep operational transparency
  • Extremely cost-efficient long-running execution

As AI systems become more complex and multi-agent workflows become more common, orchestration is starting to matter as much as model intelligence itself.

DeepSeek Harness is one of the strongest signals so far that the future of AI infrastructure will be built around composable systems, not just increasingly powerful models.

DeepSeek Harness just changed AI coding forever Read More »

GLM-5.3 is a huge huge sign of things to come

GLM-5.3 is a very unconventional upgrade — no one should ignore this and what it means.

Z.ai (the makers) refused to follow the same old formula of training a bigger model and spending more and more on compute.

Like as far as weights and parameters go, this is the exact same model as GLM-5.2 (and still open-source btw).

But somehow it’s just better in every single way — with an unbelievable 50% performance leap and scary coding and hacking ability that now surpasses even Claude Mythos 5.

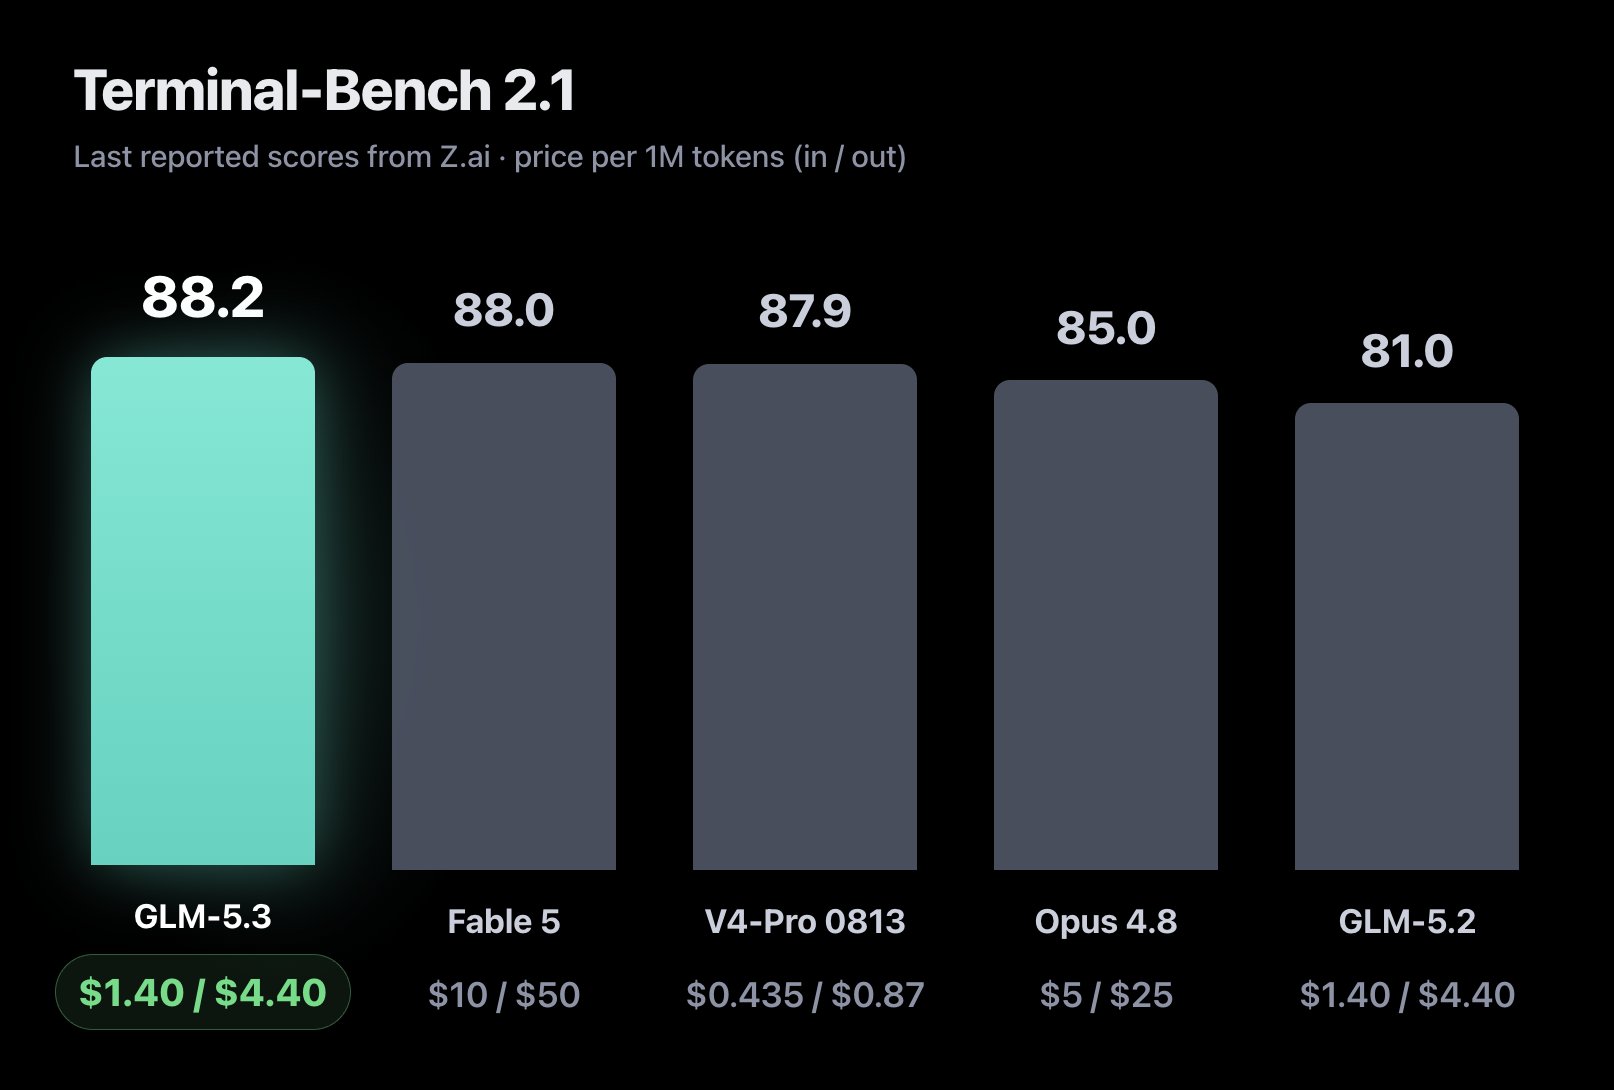
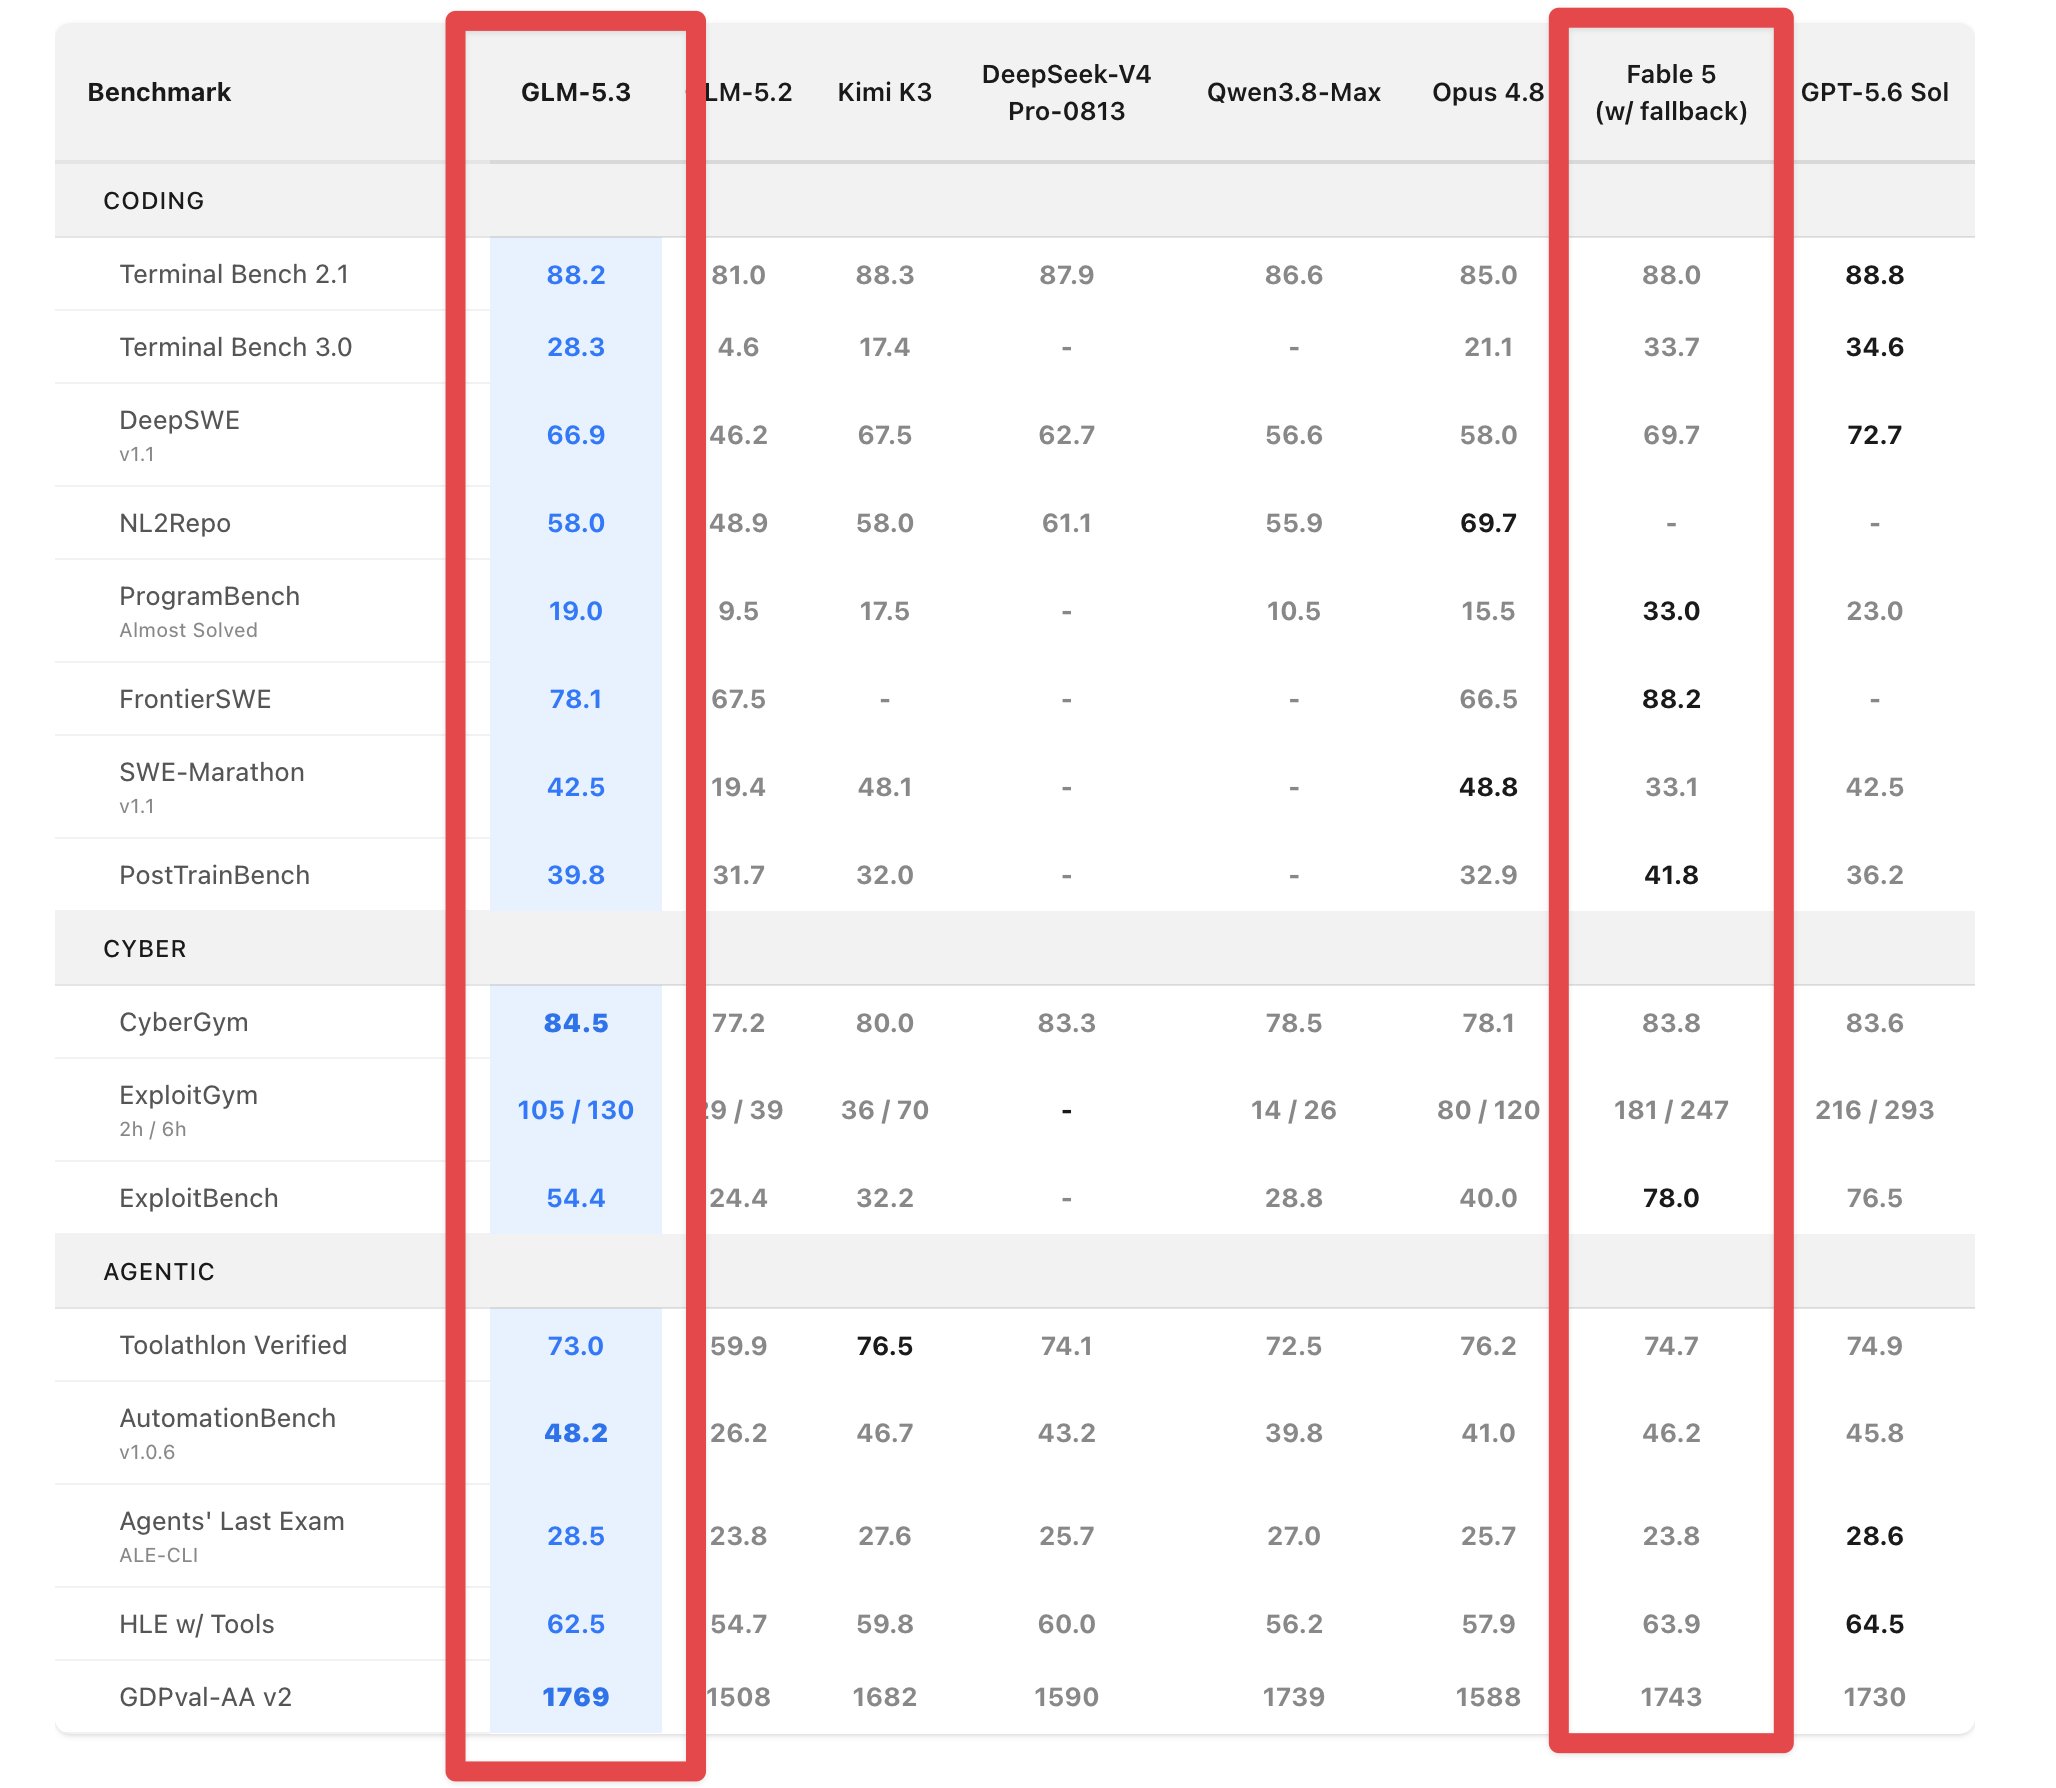
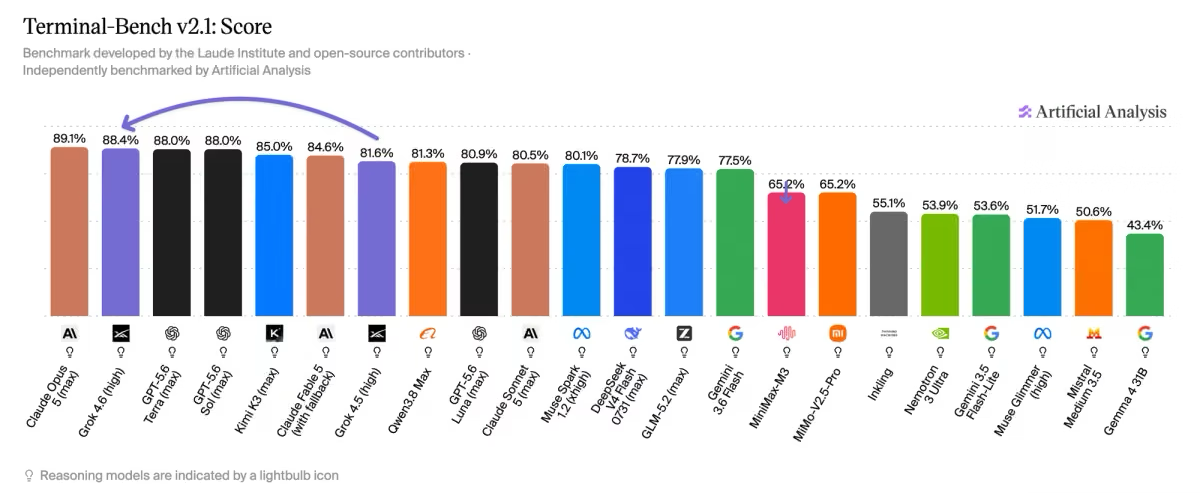
GLM-5.3 beats every single model in the official Terminal-Bench 2.1 benchmark — include Fable 5 — despite being several times cheaper:

On DeepSWE, GLM-5.3 scored 66.9, nearly matching Kimi K3 (67.5) and outperforming GLM-5.2 (46.2), while remaining competitive with Fable 5 (69.7) and GPT-5.6 Sol (72.7).

They didn’t build a new model from scratch — they focused entirely on how to make the model learn better from existing data — using sophisticated techniques like reinforcement learning and environment scaling.

A novel approach that has now paid off massively.

Open-source GLM-5.3 goes toe-to-toe with Fable 5 in coding and every other area — despite being several times cheaper:

On Agents’ Last Exam (CLI), GLM-5.3 posted the highest score at 28.5, narrowly surpassing GPT-5.6 Sol (28.6) and Kimi K3 (27.6) to lead the benchmark.

It’s challenging the long-standing believe that better AI performance needs larger base models.

From GLM-5.3 we are seeing that we can get serious results from simply coming with new ways to improve how models learn after pre-training.

We could see major gains across board as more and more AI companies consider this different approach.

The cybersecurity performance is incredible.

GLM-5.3 achieved 84.5% on the CyberGym benchmark, a test designed to evaluate vulnerability discovery, software security analysis, and exploit-chain reasoning, surpassing both Claude Mythos 5 and GPT-5.6 Sol on the benchmark.

It’s very strong at:

  • Vulnerability discovery
  • Security auditing
  • Root-cause analysis
  • Multi-step software reasoning

GLM-powered systems identified thousands of real-world software vulnerabilities during internal testing, including critical security flaws in widely used developer tools.

They also designed GLM-5.3 with autonomous agents in mind.

The model supports:

  • 1 million token context
  • 128,000 token output length

This allows it to work across large codebases, lengthy technical documents, and multi-stage workflows without losing context.

Just as important, it also completes tasks using much fewer output tokens than GLM-5.2 while achieving higher accuracy.

That combination means:

  • Lower inference costs
  • Faster execution
  • Better agent efficiency
  • Improved performance on long-running tasks

And as we find ourselves using AI more and more for software engineering, efficiency is becoming just as important as raw intelligence.

GLM-5.3 also changes how reasoning works.

You can turn off reasoning anymore like in some other models — you can only choose between Low, High, and Max.

This reflects a growing industry trend where reasoning is treated as a core capability rather than an optional feature.

The question is no longer whether the model should think, but how much compute should be allocated to solving a problem.

Z.ai also remains committed to releasing model weights publicly.

But because of GLM-5.3’s strong cybersecurity abilities, they’ve had to introduce a new Open Source Shield Initiative — which is meant to:

  • Keep defensive security research open
  • Support code auditing and vulnerability detection
  • Restrict access to high-risk offensive exploitation capabilities

This helps to balance openness with responsible deployment.

GLM-5.3 may ultimately be remembered less for its benchmark scores and more for what it represents.

It shows us that massive gains are still possible without training a new base model.

It sets a new bar for AI-driven cybersecurity research. And it is optimized for the future of long-horizon autonomous agents.

If earlier AI progress was defined by scaling pretraining, GLM-5.3 is showing us that next era could be all about scaling post-training instead.

GLM-5.3 is a huge huge sign of things to come Read More »

This new Google model beats both Claude & GPT-5.6

This is HUGE.

Google’s new Gemini 3.7 Flash is absolutely insane.

It even dominated Claude Sonnet 5 and GPT-5.6 Terra — it’s the best & fastest mid-tier coding model in the world right now.

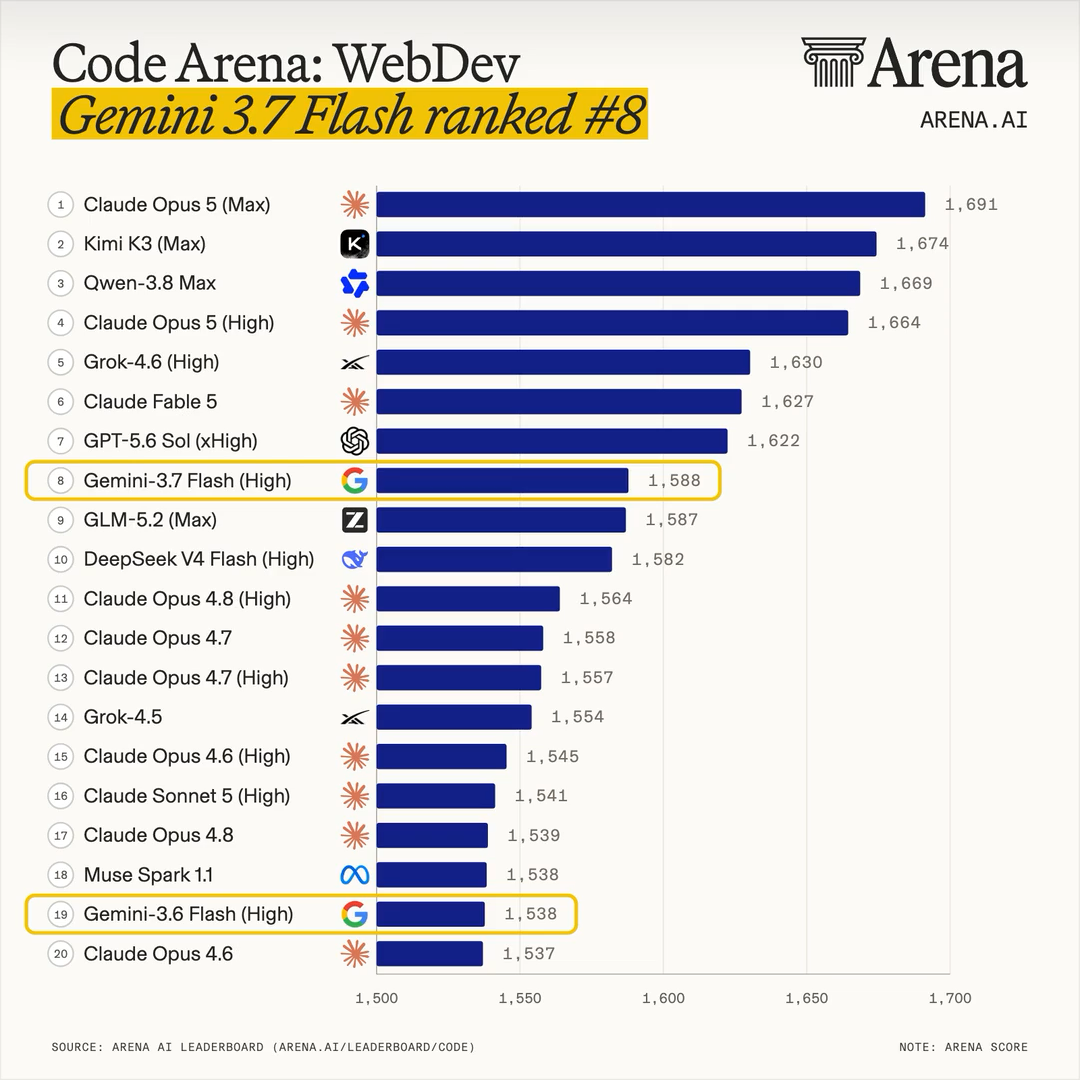
It literally jumped 11 good places in the AI Arena Leaderboard — now even beating models like Opus 4.8 and Grok 4.5 — despite being several times cheaper and faster.

It’s so amazing at software engineering, web design, and UI generation.

Gemini 3.7 Flash achieved 65.3% on DeepSWE v1.1—up dramatically from Gemini 3.6 Flash’s 48.6% and ahead of Claude Sonnet 5’s 49.7% and GPT-5.6 Terra’s roughly 52–54% results on the same benchmark, establishing a new high-water mark for autonomous software engineering.

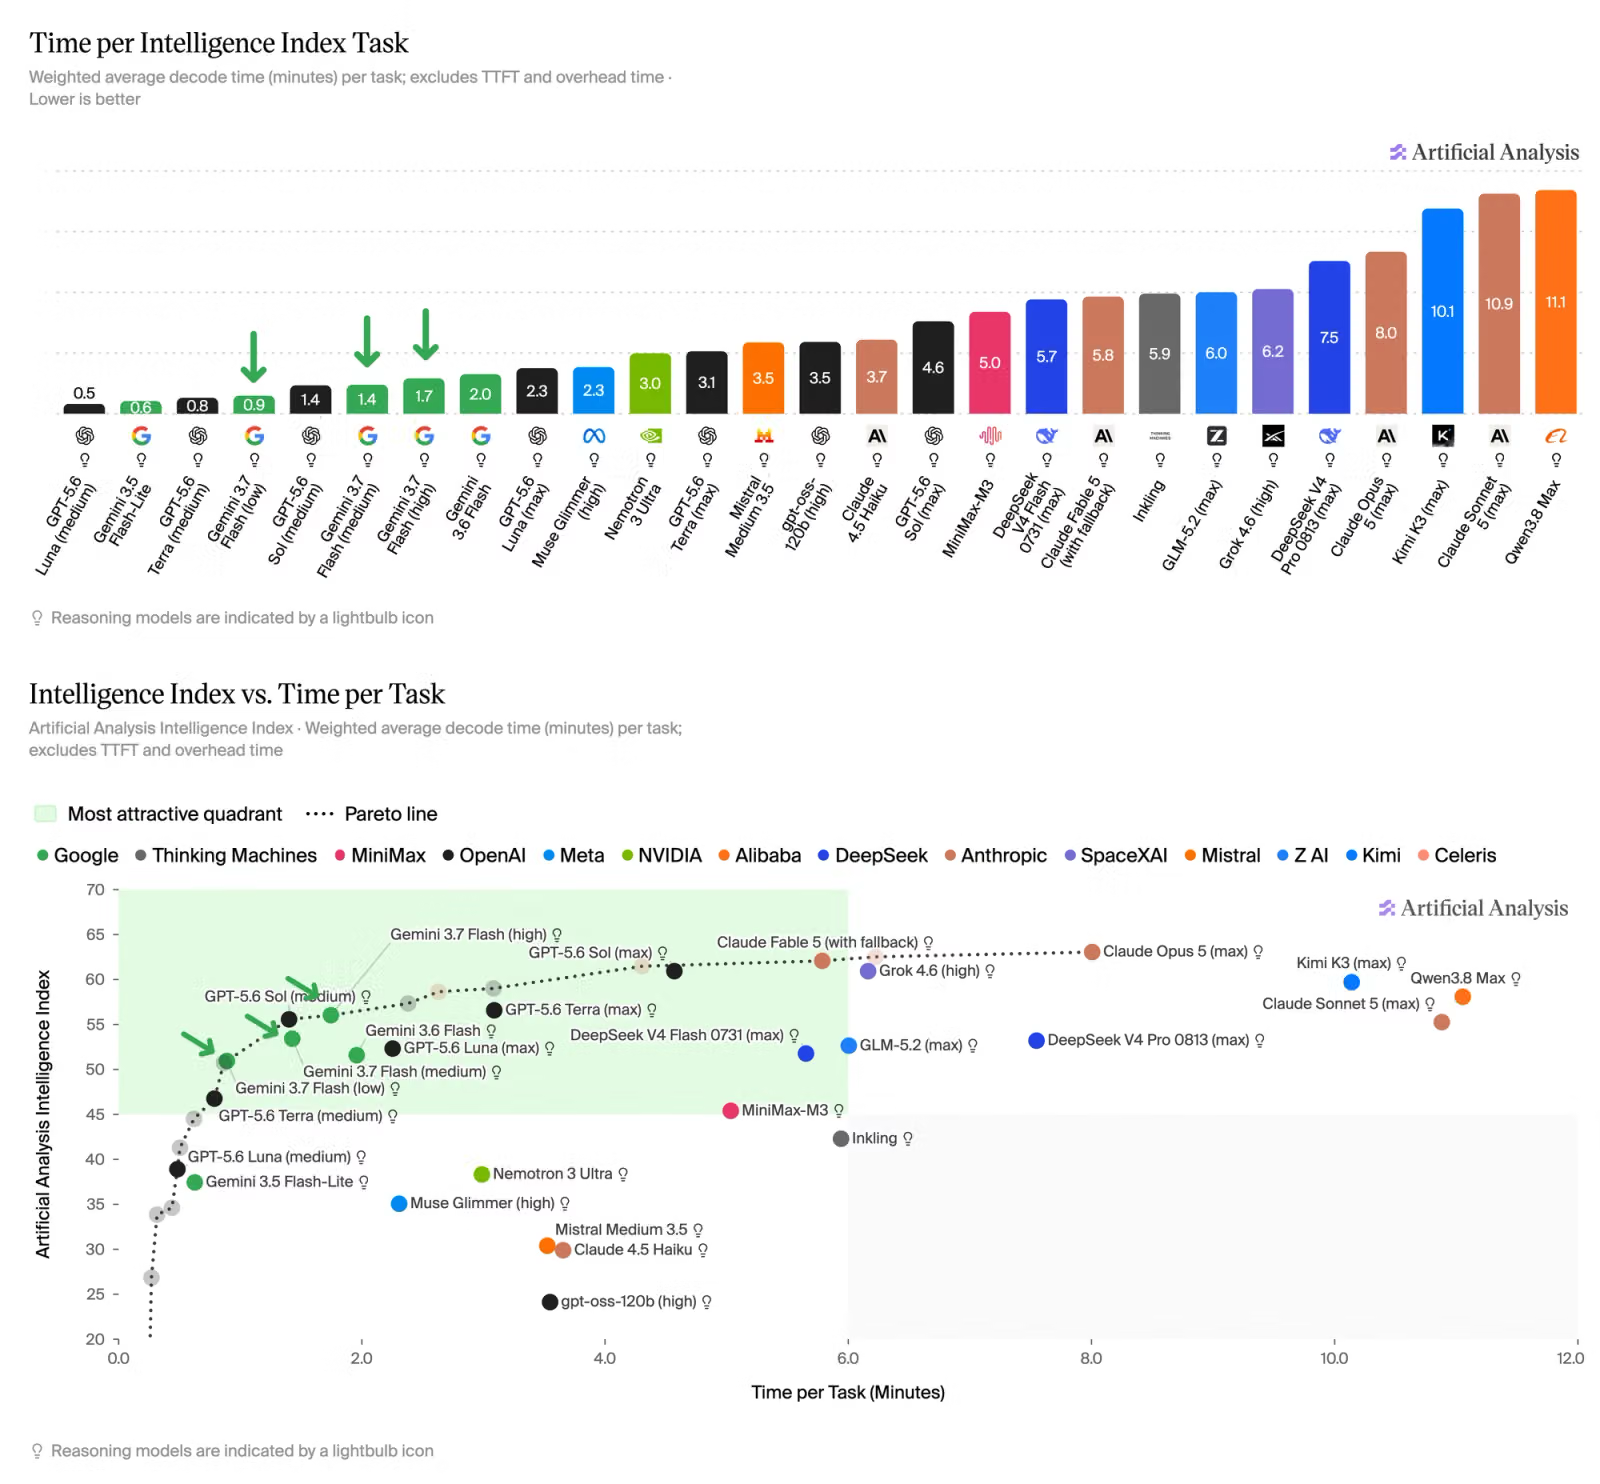
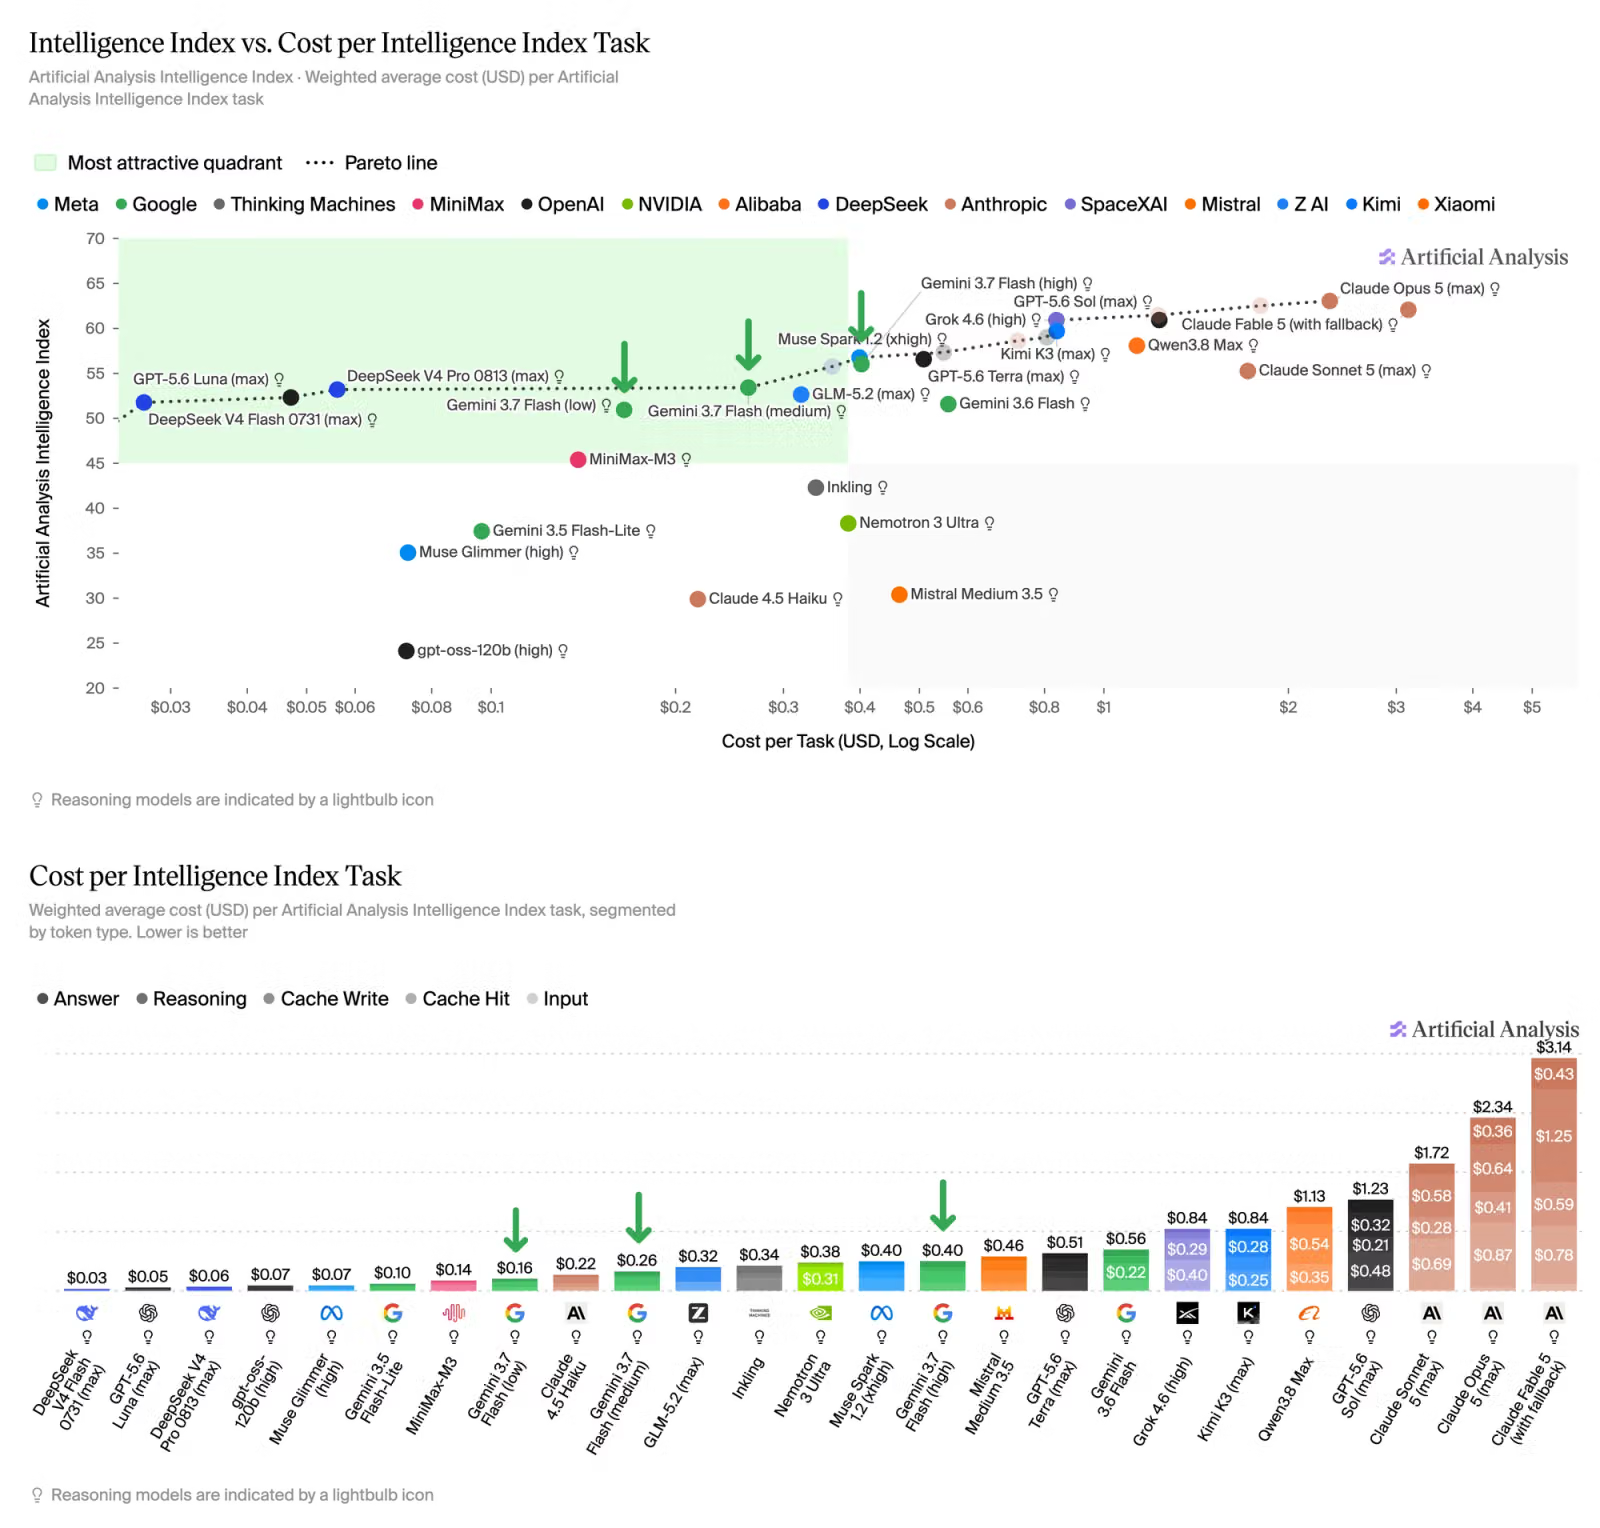
Gemini 3.7 Flash has by far the best Time per Intelligence of any model of this intelligence level:

Google’s Gemini 3.7 Flash delivers a breakthrough intelligence-to-speed ratio, hitting a peak output speed of roughly 340 tokens per second while scoring 56 on the Artificial Analysis Intelligence Index—outperforming several pricier flagship peers while finishing multi-step workflows up to 40% faster

It costs so much less than all these other models on the same level of intelligence — you won’t believe how cheap it is right now.

Gemini 3.7 Flash has by far the best Cost per Intelligence of any model of this intelligence level:

Smarter agentic planning — “diligent” thinking

The reasoning and planning have gotten so much more sophisticated.

Instead of immediately generating a response, the model spends more time planning, reasoning, and coordinating tools before taking action.

It thinks more diligently, putting in more effort into multi-step planning and tool calls. A more disciplined execution means less manual oversight and fewer retries across engineering workflows.
— Google

This gives you:

  • Better upfront planning for complex tasks
  • Self-correction when code or tool calls fail
  • Recovery from dead ends without getting stuck in retry loops
  • Stronger tool orchestration across multi-step workflows
  • Intent clarification when instructions are ambiguous

It doesn’t make risky assumptions of things it’s not sure about — it pauses and ask the right question before continuing.

Which makes a much more reliable coding partner.

Massive software engineering gains

Nobody can look down on Gemini when it comes to coding anymore.

Gemini 3.7 Flash achieved 65.3% on DeepSWE v1.1—up dramatically from Gemini 3.6 Flash’s 48.6% and ahead of Claude Sonnet 5’s 49.7% and GPT-5.6 Terra’s roughly 52–54% results on the same benchmark, establishing a new high-water mark for autonomous software engineering.

3.7 Flash outperforms other frontier models like Sonnet 5 and GPT-5.6 Terra is key software engineering abilities — despite being multiple times cheaper.

It’s been such a massive upgrade:

Benchmark Performance:

65.3% on DeepSWE v1.1

  • Up from 48.6% in Gemini 3.6 Flash
  • Measures complex, long-horizon software engineering tasks

43.6% on FrontierCode 1.1

  • Evaluates first-pass coding accuracy
  • Tests real-world engineering capabilities

These gains translate into real meaningful improvements for you as a developer:

  • Better understanding of large codebases
  • Stronger debugging abilities
  • More accurate feature implementation
  • Improved multi-file reasoning
  • Higher-quality code on the first attempt

Exceptional web dev & frontend design ability

Frontend generation is becoming one of the most competitive areas in AI — and Gemini 3.7 Flash is now among the strongest performers.

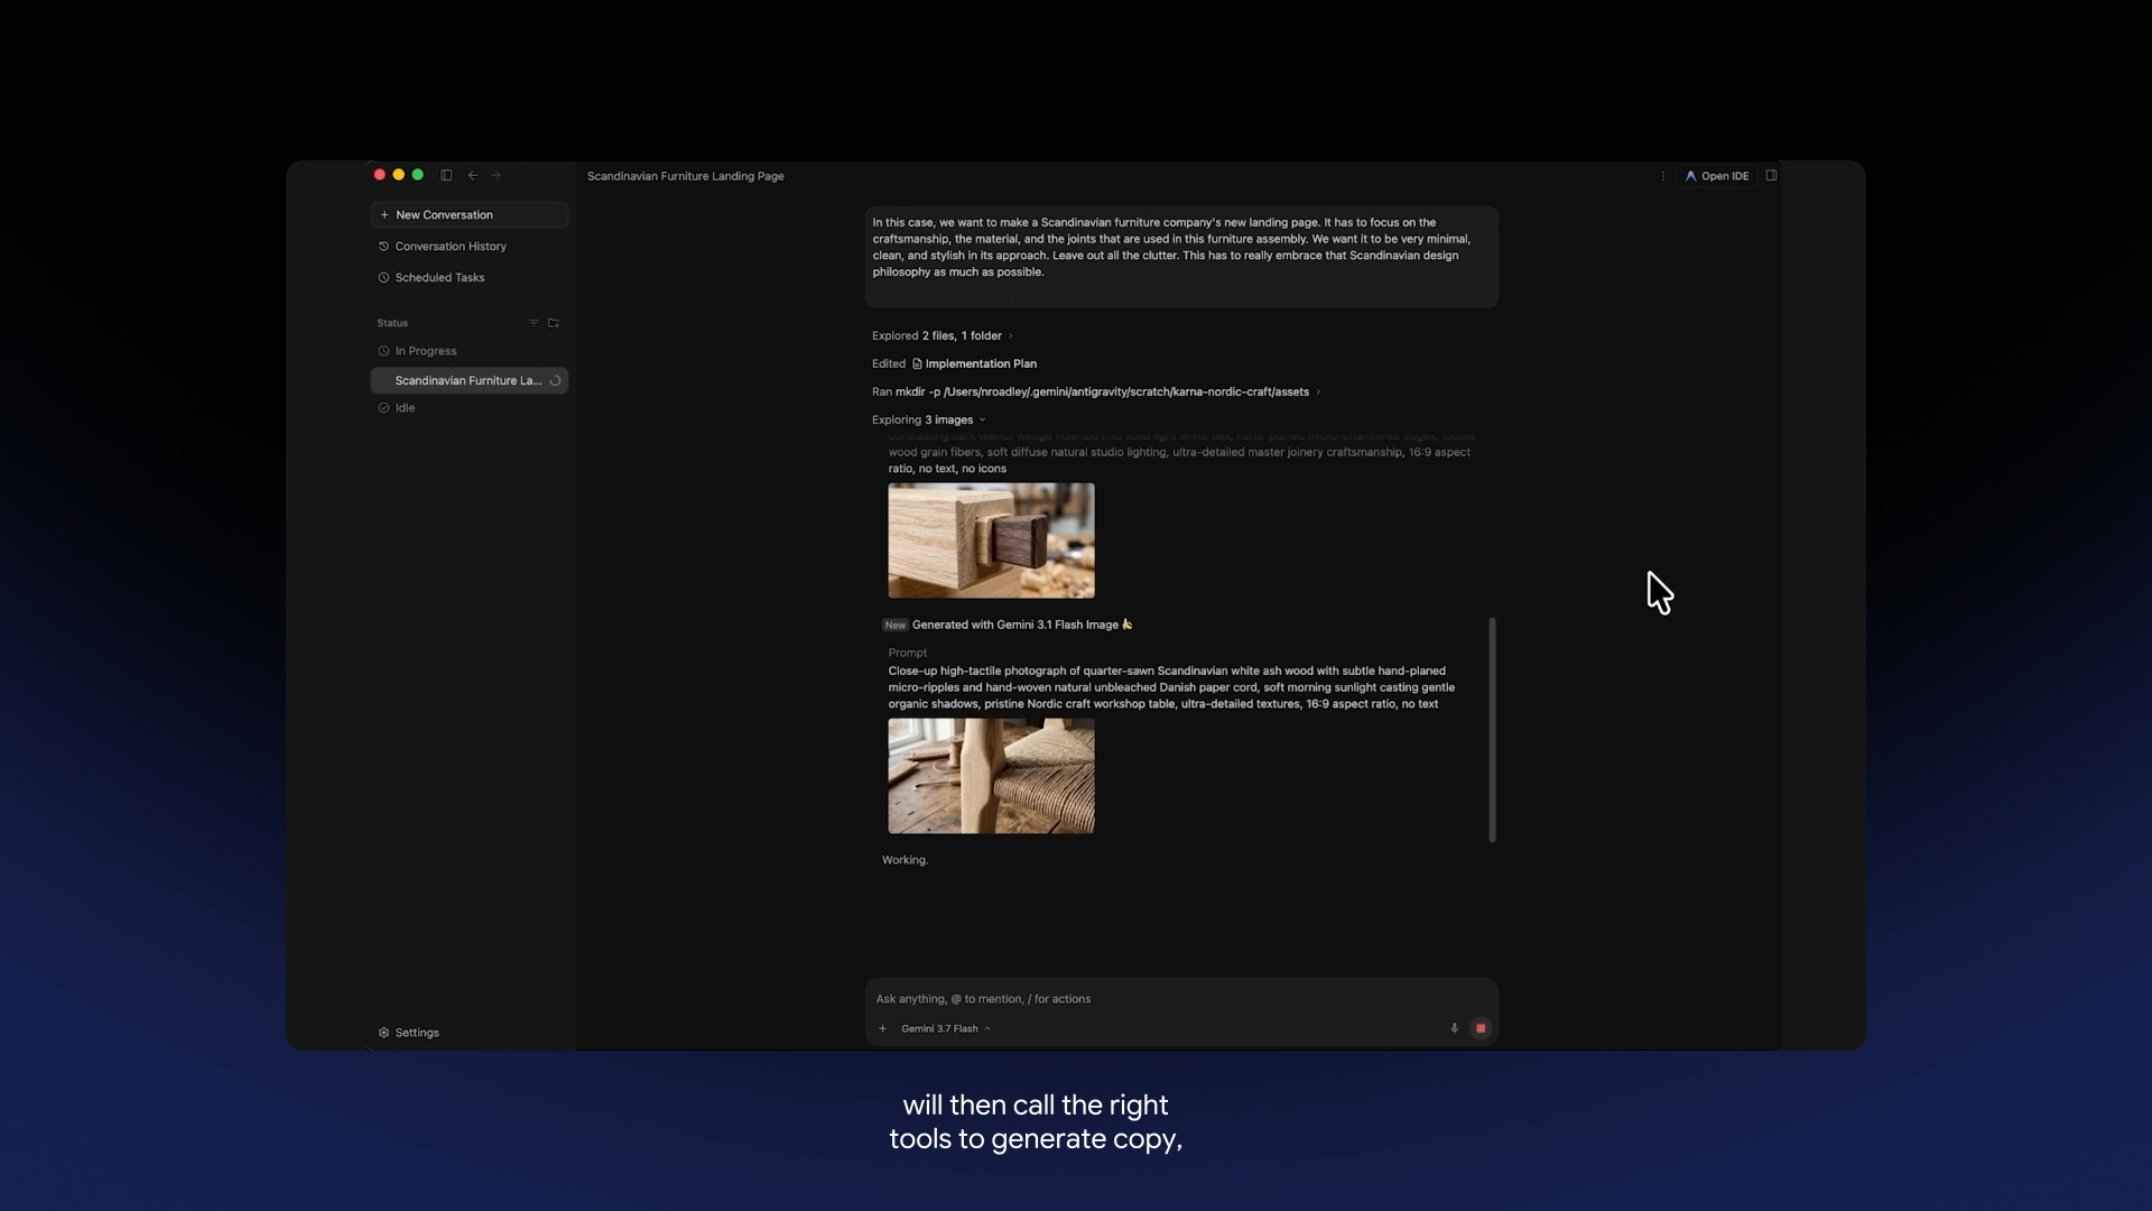
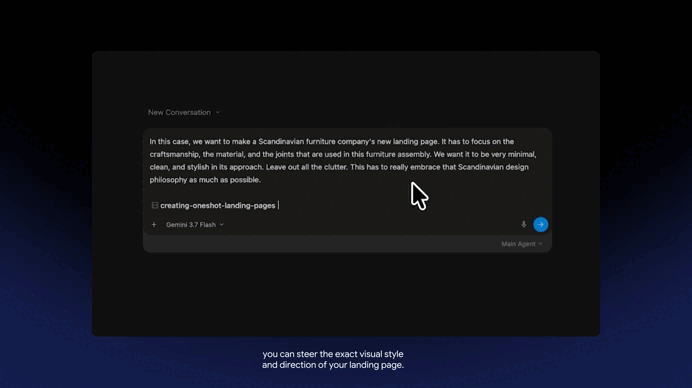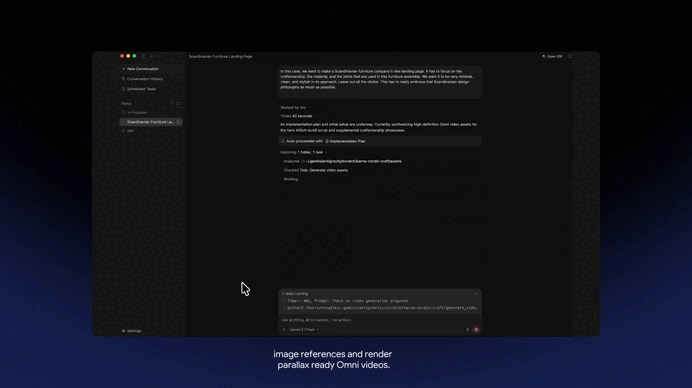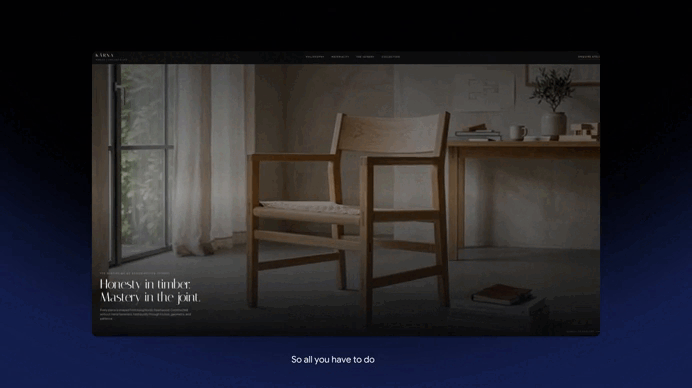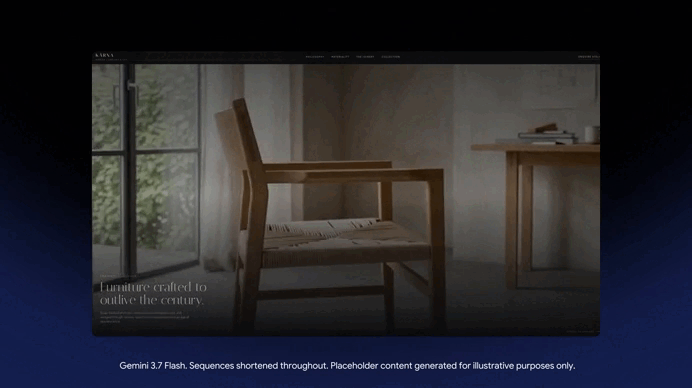
Gemini 3.7 Flash generating a world class landing page with posh visual effects from scratch:

Frontend Benchmarks:

  • 1588 Elo on WebDev Arena
  • 1588 Elo on Code Arena

These scores place Gemini 3.7 Flash ahead of competing models like Claude Sonnet 5 and GPT-5.6 Terra in frontend and full-stack application generation.

And these benchmarks evaluate more than visual appearance. High-performing models must create:

  • Responsive layouts
  • Multi-component interfaces
  • Consistent design systems
  • Functional application logic
  • Production-quality user experiences

As someone building real-world products, this means fewer revisions and better results for you from the very first prompt.

Incredible UI generation ability

You can give it:

  • Wireframes
  • Screenshots
  • Design systems
  • Existing interfaces
  • Product mockups

The model can then generate functional applications that closely match the provided designs.

Instead of hallucinating generic layouts, it is far better at preserving structure, styling, and user experience patterns.

The result:

  • Fewer prompts
  • Less back-and-forth
  • Faster prototyping
  • Quicker path to production-ready applications

Industry-leading Pricing

This is hands-down one of the biggest selling points.

Introductory Pricing (through December 31, 2026)

  • $0.75 per million input tokens
  • $3.75 per million output tokens

Standard Pricing (starting January 1, 2027)

  • $1.50 per million input tokens
  • $7.50 per million output tokens

Even at standard pricing, Gemini 3.7 Flash remains highly competitive.

At launch pricing, it is:

  • More than 60% cheaper than Claude Sonnet 5
  • More than 60% cheaper than GPT-5.6 Terra
  • Competitive or superior across several coding and web development benchmarks

This combination of performance and affordability makes it one of the strongest value propositions in the AI market today.

Far more than just a routine upgrade

It gives us major advances in:

  • Agentic planning
  • Self-correction
  • Software engineering
  • Web development
  • Frontend design

Combined with aggressive pricing, Gemini 3.7 Flash sets a new benchmark for cost-efficient AI.

For developers and startups building AI-powered products, it’s one of the most compelling models available today.

This new Google model beats both Claude & GPT-5.6 Read More »
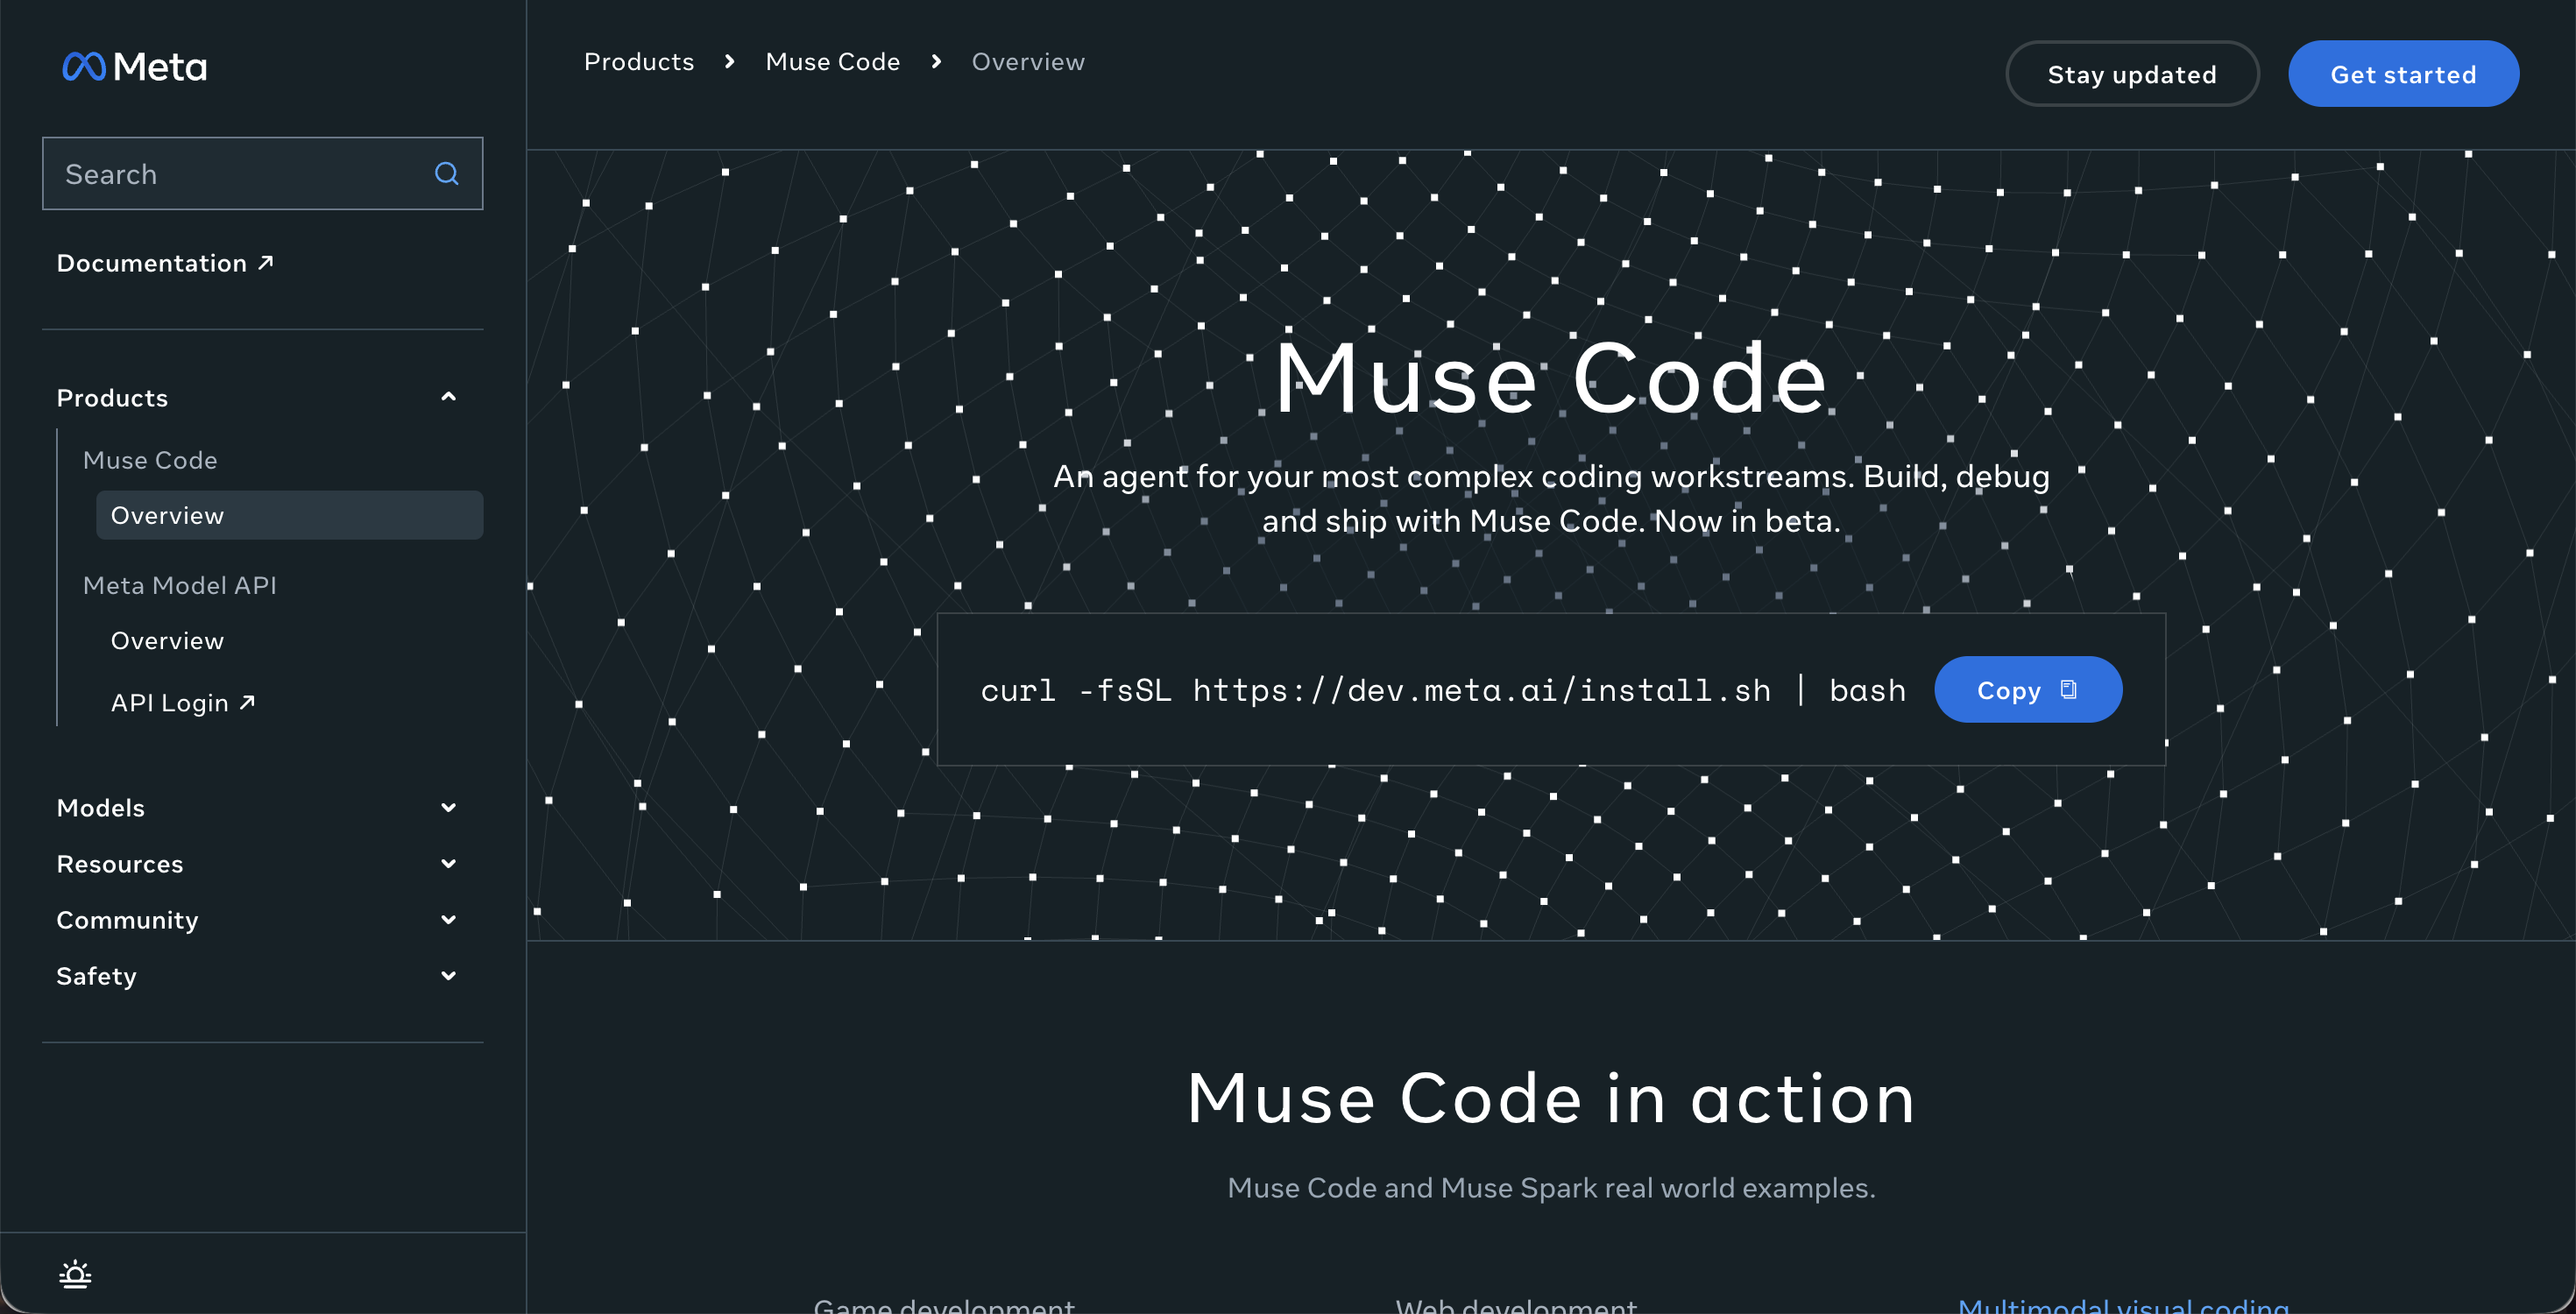
Meta’s new Claude Code competitor is absolutely insane

This is absolutely incredible.

Meta’s just released a revolutionary new AI coding agent.

The new Muse Code is so unbelievably cheap and intelligent — once again we see the clear trend of AI getting cheaper and cheaper.

And it comes with a revolutionary new approach to multi-agent collaboration, that could transform the workflow of so many developers.

Powered by their most powerful model ever — this is going to make major impact on the entire AI coding ecosystem.

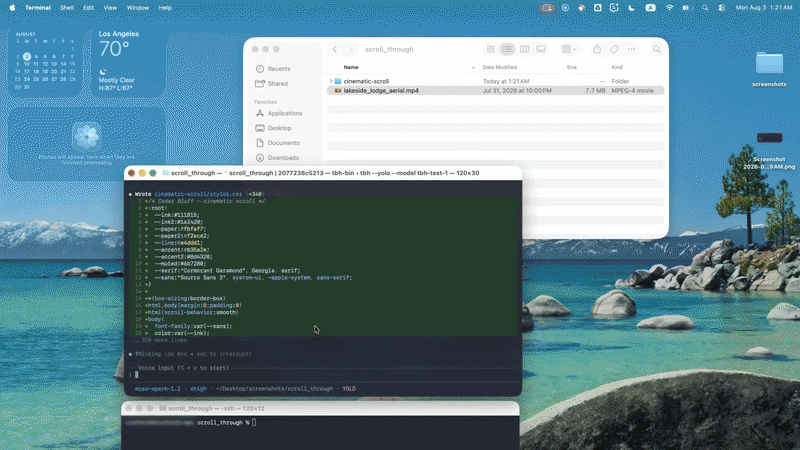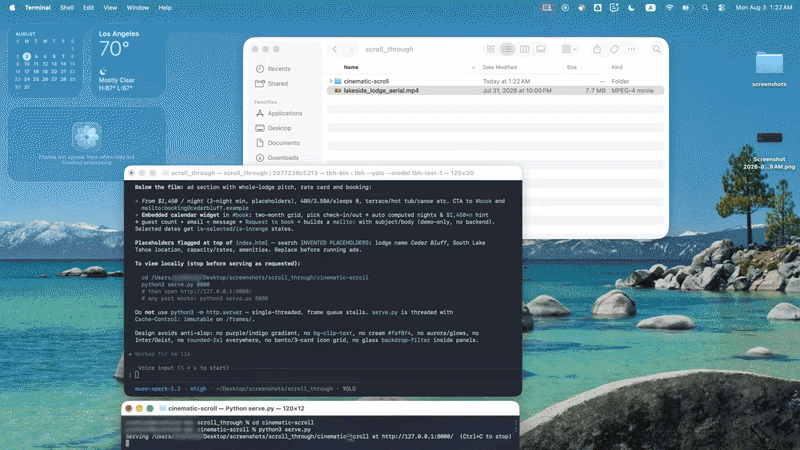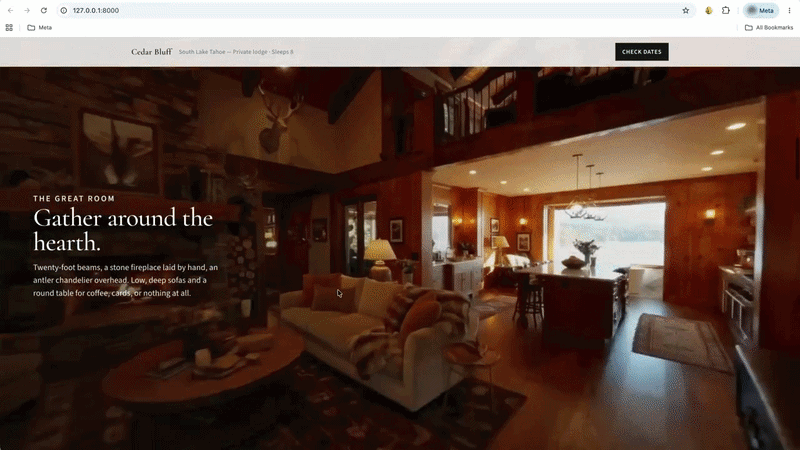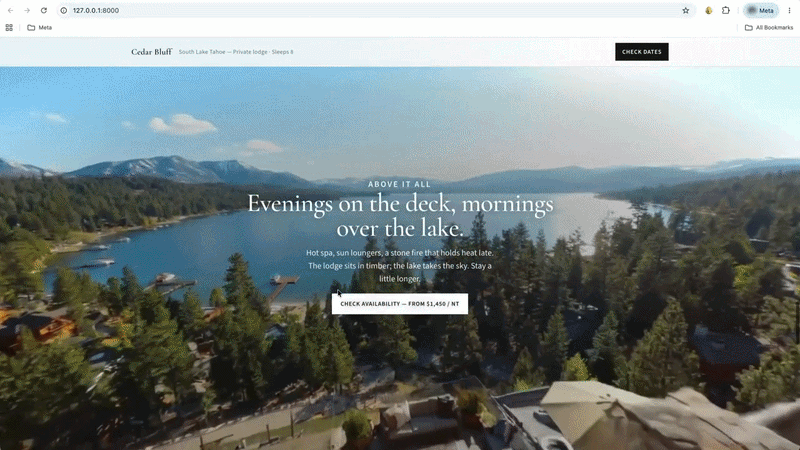
Demo stage #1: A drone fly through video to be given to Muse Code to integrate into a landing page:

Muse Code is a terminal-based agent designed from the group up to handle complete software engineering tasks across large repositories — putting it directly against tools like Claude Code and Codex.

But it’s not just yet another coding assistant in your terminal.

Meta is building it around a bigger idea: coding agents should work for hours, coordinate multiple workers, survive failures, and keep making progress autonomously.

Let’s check out all the most amazing features it comes with — including how incredibly inexpensive it is.

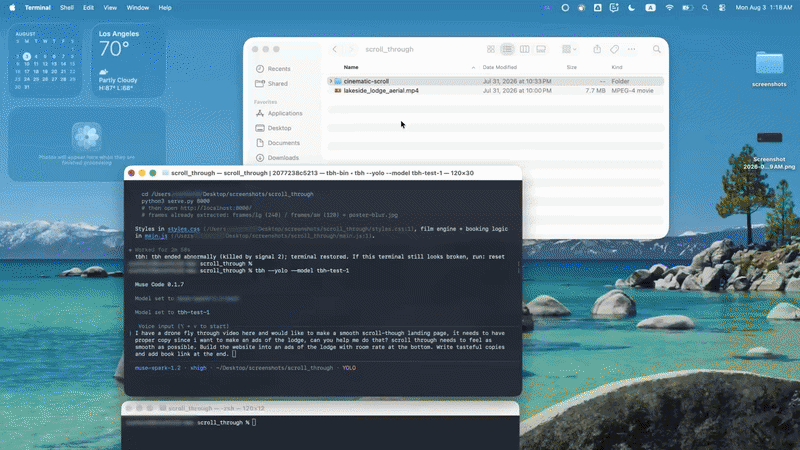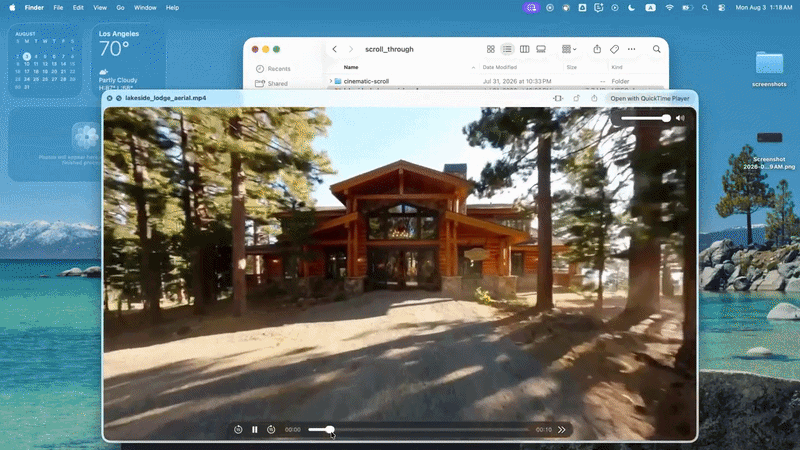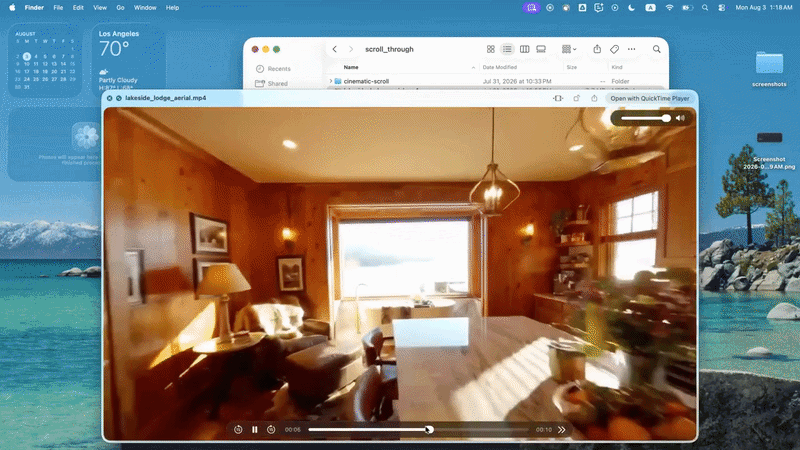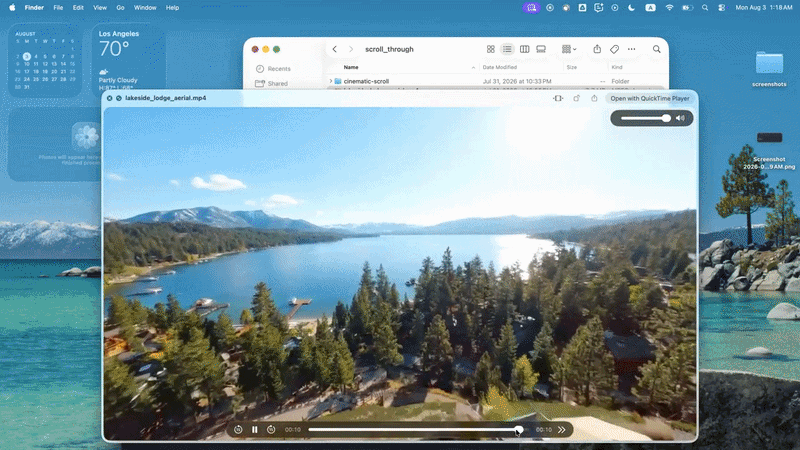
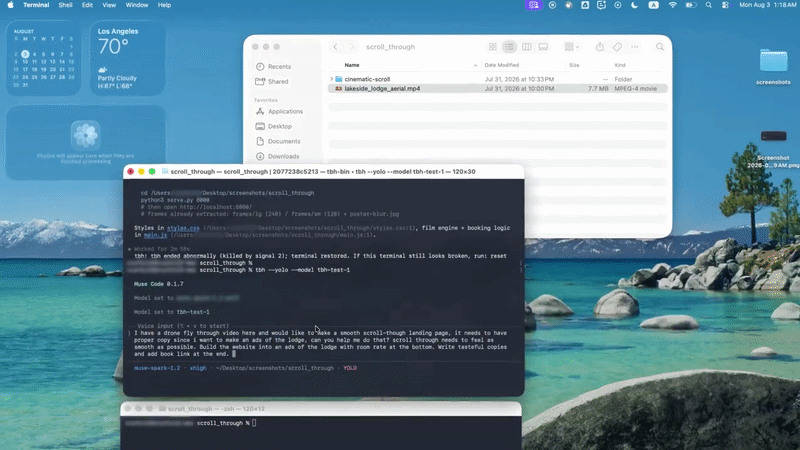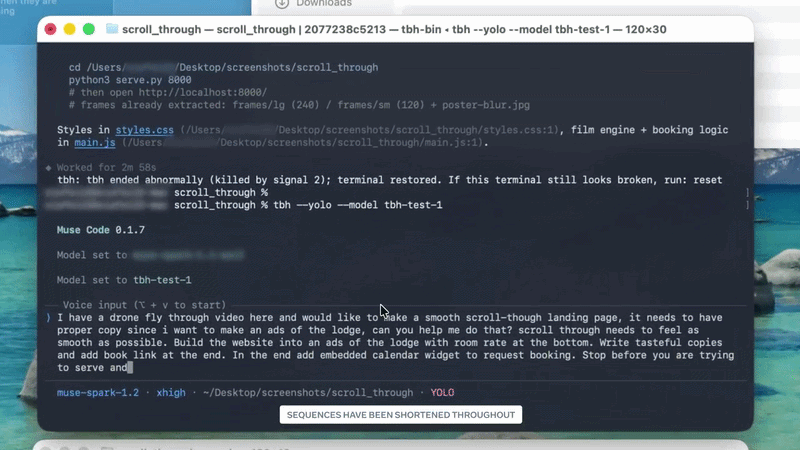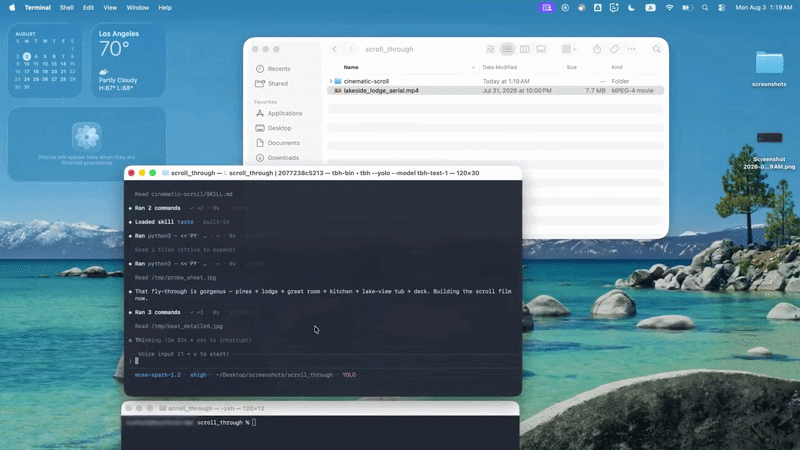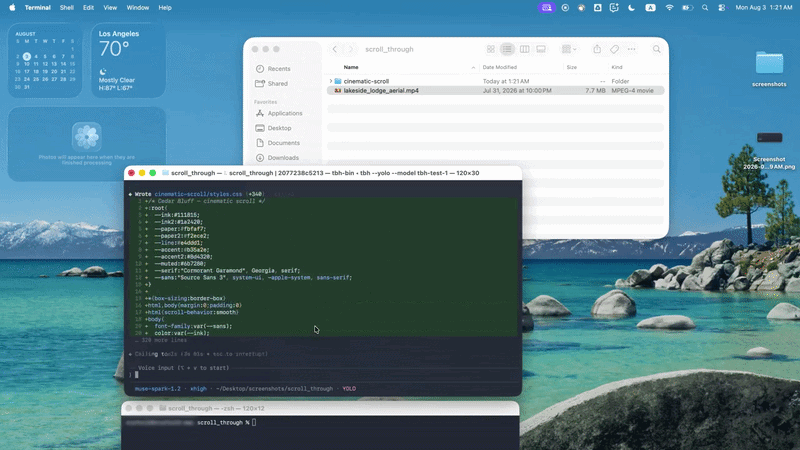
Demo stage #2: Asking Muse Code to integrate the video into the website with various marketing copies at different points in the video — directly from the terminal:

1. Persistent background agents — less repeated work

Most coding agents create a subagent, give it a task, collect the result, and destroy it.

Muse Code instead keeps asynchronous background agents alive throughout the session.

They can:

  • investigate different parts of the codebase
  • retain context they’ve already gathered
  • work while the main agent continues
  • report useful discoveries back later

For us developers, this means less repeated exploration of large repositories.

Instead of one agent repeatedly searching hundreds of files, you get specialized workers that gradually build knowledge of the project while the main agent keeps coding.

Demo stage #3: Muse Code intelligently integrates the video into the website, with all the marketing copies and the final call to action:

2. Incredible low cost — run coding agents for a fraction of the price

Meta is also being extremely aggressive on price.

Its Contributor tier can bring pricing down to as little as $0.20 per million output tokens — less than one-tenth of typical frontier-model rates.

One thing you need to know though — if you’re using this discounted tier, you have to agree to let Meta use your interactions, including generated code, to help improve its models.

If you’re comfortable with that, this could be huge for your cost savings.

Long-running agents can burn through enormous numbers of tokens. Making those tokens dramatically cheaper makes Muse Code’s hours-long autonomous coding loops and parallel agents much more practical to run regularly.

3. Muse Spark 1.2 — Meta now has a serious coding model

Muse Code is powered by Muse Spark 1.2, Meta’s new coding-focused model.

And interestingly Meta says the model and coding harness were co-trained — not something you see everyday from most other models.

Rather than wrapping an agent around a generic model afterward, Meta trained Spark using the environment and workflows it would eventually operate inside.

Some key benchmark results from Muse Spark 1.2:

  • Terminal-Bench 2.1: 82.9%
  • DeepSWE 1.1: 59.3%
  • Meta Internal Coding Bench: 70.6%

Meta hasn’t taken the coding crown (yet??) — but it’s clearly become a serious competitor.

4. Parallel worktrees — build multiple things at once

Muse Code can also fan large tasks out across multiple subagents running simultaneously in isolated Git worktrees.

Each agent gets its own workspace, allowing several agents to modify the same repository without constantly overwriting each other’s work.

Meta demonstrated this by having Muse Code build six game features simultaneously without collisions.

The practical benefit is speed.

Instead of:

feature A → feature B → feature C → feature D

you potentially get:

feature A + feature B + feature C + feature D

all being developed simultaneously.

AI coding starts looking less like one extremely fast developer and more like a small engineering team working in parallel.

5. Crash recovery — long-running agents don’t lose everything

Long-running agents create another problem: failure becomes increasingly expensive.

Imagine an agent researching, coding, testing, and debugging for three hours — then the process crashes.

Muse Code addresses this with a local append-only event log.

Model calls, tool executions, approvals, edits, and other actions are recorded as events. The runtime can replay them to reconstruct its previous state.

That makes executions restart-safe.

For five-minute coding prompts, this isn’t particularly important.

For autonomous tasks lasting several hours, it’s essential.

6. 24-hour coding runs — AI coding becomes a background process

Meta is clearly designing Muse Code for much longer tasks than normal prompt-and-response coding.

In one experiment, Muse Code optimized GPU kernels for NVIDIA Hopper hardware.

The agent repeatedly:

wrote code → compiled → profiled → analyzed → improved

It made more than 1,000 tool calls across runs lasting up to 24 hours.

That’s a very different model of AI-assisted development.

For optimization, migrations, debugging, test improvement, and other measurable engineering problems, you could define the goal, leave the agent running, and return later to the results.

What all this tells us

The most interesting part of Muse Code isn’t another benchmark score.

It’s everything surrounding the model:

Persistent agents. Parallel worktrees. Crash recovery. Thousands of tool calls. 24-hour autonomous runs.

The AI coding race is moving beyond “which model writes the best code?”

It’s increasingly about which system can reliably keep working until the engineering task is actually finished.

Muse Code is Meta’s answer.

Meta’s new Claude Code competitor is absolutely insane Read More »
This new open-source model beats both Fable 5 & Opus 4.8

This is incredible — Qwen 3.8 Max is seriously revolutionary.

A new open-source model that beats Claude Fable and Opus 4.8 — despite being several times cheaper. It’s even cheaper than Kimi K3.

Only the second open-source model in history to rank Top 5 in the AI Arena Leaderboard.

Beats Fable comfortably — and look at the massive gap it has ahead of Opus 4.8 — next version 3.9 will very likely beat Opus 5 too:

Open-source has really started to dominate the AI ecosystem. The tide is turning rapidly. Long gone are the days of seeing them as weaker variants of the real deal.

We’ve seen the shocking results from Kimi K3, DeepSeek v4 — and now this.

Don’t be surprised if a few months from now all the top 5 models on any major leaderboard are all open-source.

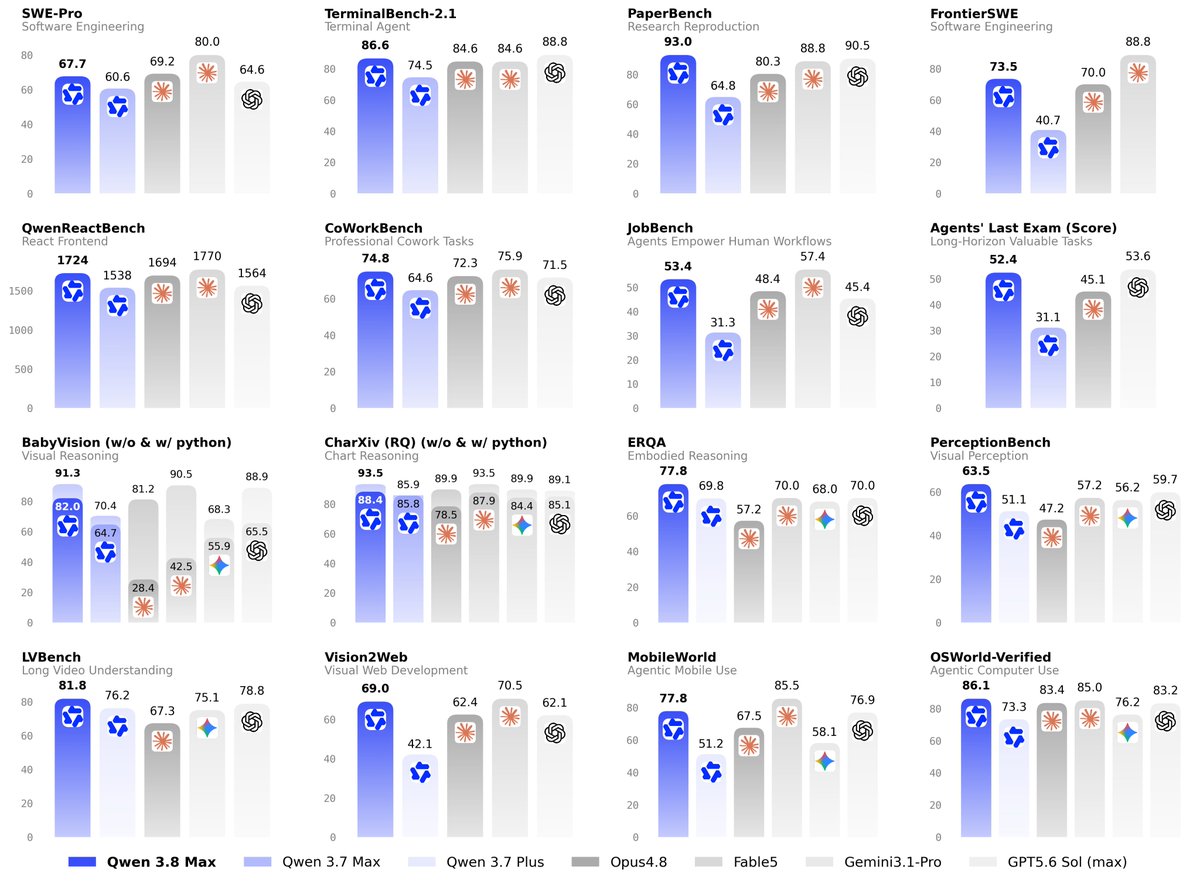
Qwen 3.8 Max scored 86.6 on Terminal-Bench 2.1, outperforming Claude Fable 5 (84.6) in one of the industry’s toughest evaluations of real-world, agentic terminal coding workflows

And open-source is also becoming contagious — before now the Max model in the Qwen series was never open-source. It was always the lesser models that had their weights made publicly available.

But things have changed completely now — now with Qwen 3.8 even the top-tier Max model is open-source.

AI is getting a lot cheaper and more accessible — both for coding and building AI-powered apps.

10+ days of non-stop coding…

We’ve gotten wild reports of the model being able to sustain 10+ days of autonomous project development — managing hundreds of Git commits while continuously improving software.

Qwen 3.8 Max has been heavily optimized for agentic software development — enabling it to tackle all your most complex engineering tasks from start to finish.

On PaperBench, which measures an AI’s ability to reproduce and understand machine learning research, Qwen 3.8 Max posted an impressive 93.0, comfortably ahead of Claude Opus 4.8 (88.8)

It’s been designed from the ground up for:

  1. Continuous scientific research
  2. Multi-hour data science tasks
  3. Long-horizon planning
  4. Extended agent workflows

Qwen 3.8 Max achieved 92.6 on GPQA Diamond—a benchmark of graduate-level scientific reasoning—surpassing Claude Opus 4.8 (91.0) while remaining competitive with the strongest frontier models

Perhaps most importantly, Qwen 3.8 Max maintains context remarkably well across lengthy sessions — reducing the looping and repetitive behavior that often appears during large refactoring projects.

Scary for the competition

Major improvements across software engineering and agent benchmarks.

Qwen 3.8 Max outperforms several competing frontier models on Terminal-Bench while remaining highly competitive on software engineering benchmarks like SWE-bench Pro and FrontierSWE.

State-of-the-art self-correcting model

One of the most interesting observations from early testers isn’t reflected in benchmark charts.

Developers report a noticeable improvement in reflective self-correction.

Rather than confidently pushing forward with flawed reasoning, Qwen 3.8 Max often:

  • Detects logic errors mid-generation
  • Backtracks when it finds faulty assumptions
  • Simplifies over-engineered architectures
  • Challenges poor software design instead of blindly agreeing

The result is a model that feels more deliberate and less eager to reinforce bad engineering decisions.

Sophisticated architecture for massive parameter size

Behind Qwen 3.8 Max is an enormous 2.4 trillion-parameter Sparse Mixture-of-Experts (MoE) architecture.

That makes it one of the largest publicly disclosed AI models ever built.

Key info:

  • 2.4 trillion total parameters
  • Sparse Mixture-of-Experts architecture
  • Second-largest disclosed AI model, behind Moonshot AI’s 2.8T-parameter Kimi K3
  • First Qwen model to exceed one trillion parameters

Unlike dense models, MoE architectures activate only the experts needed for each request, allowing Qwen to deliver frontier-level capability while keeping compute costs significantly lower.

Just as importantly, this is the Qwen team’s first trillion-scale multimodal model.

It can natively understand and reason across:

  • Text
  • Code
  • Images
  • Videos
  • Complex documents

That makes it suitable for enterprise knowledge management, software engineering, scientific research, and large-scale document analysis.

Qwen 3.8 Max represents one of Alibaba’s most ambitious AI releases yet.

Its biggest differentiators are clear:

  • Open weights for the first-ever Qwen Max model
  • Frontier-scale 2.4T-parameter architecture
  • Strong coding and multi-agent performance
  • Long-horizon autonomous reasoning
  • Lower deployment costs than many proprietary alternatives

It has massively raised expectations for what developers should expect from an open-weight frontier AI model.

This new open-source model beats both Fable 5 & Opus 4.8 Read More »
How this new Claude Code feature saves you from wasting tokens

Small features can change workflows massively — and the new /btw is definitely one of such.

❌ Before:

This is what many of us are used to right now — every question you ask an AI coding assistant becomes part of the same growing conversation thread:

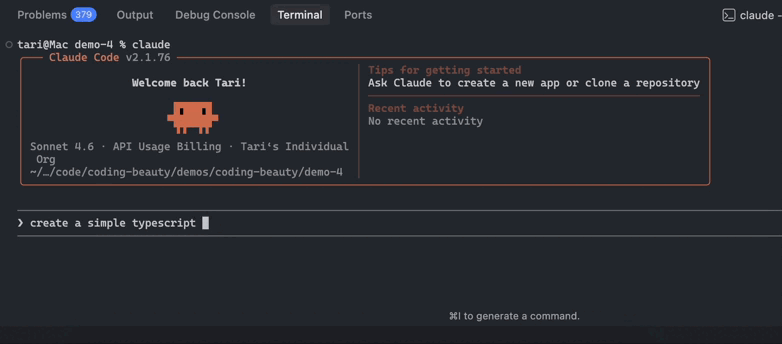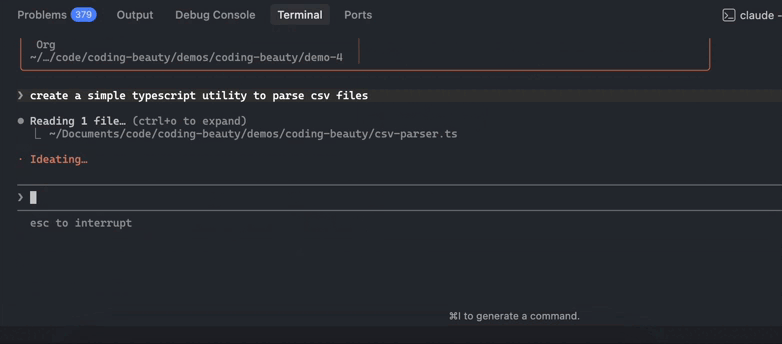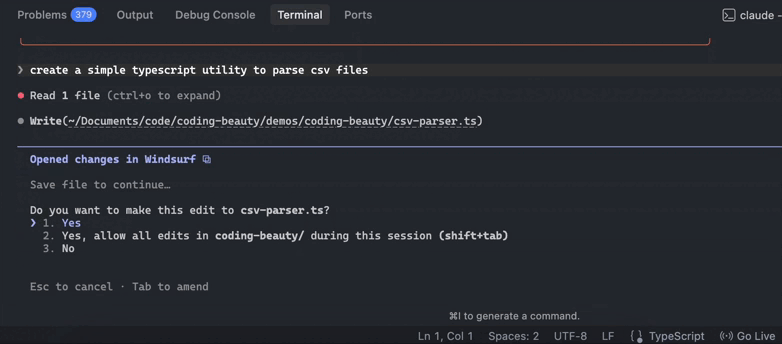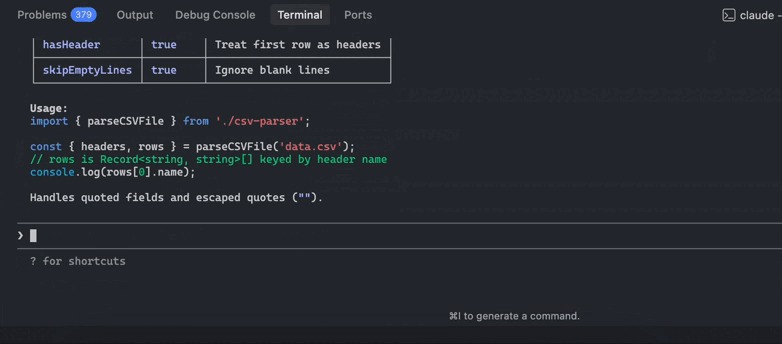
No /btw feature used to ask questions here 👇:

Which unfortunately leads to questions, clarifications, and quick reminders slowly cluttering the context — making sessions more expensive than ever.

✅ Now:

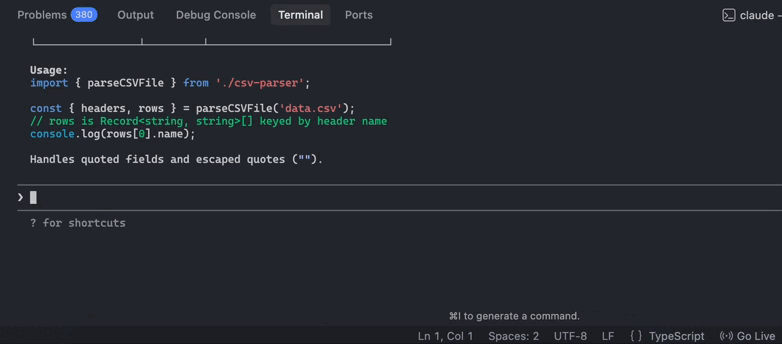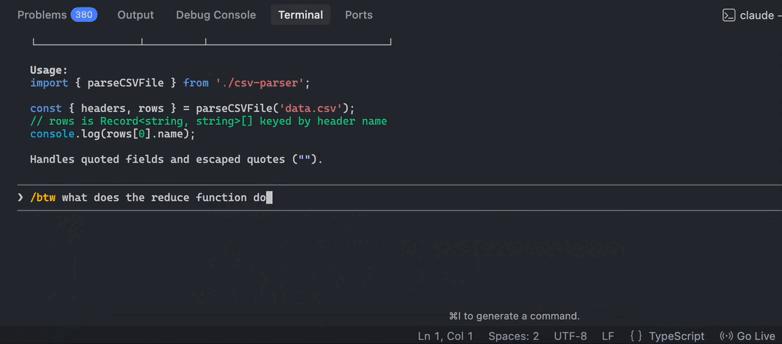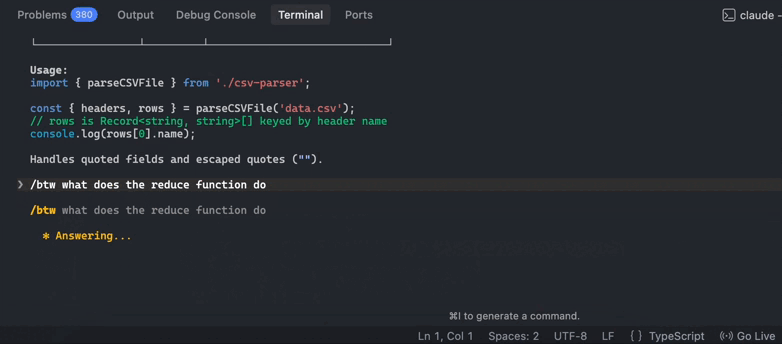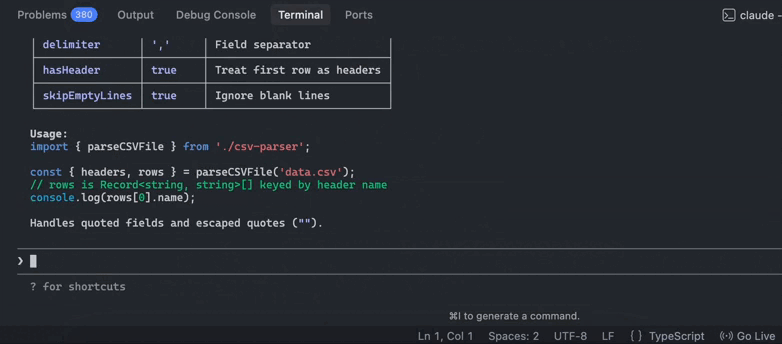
Now Claude Code’s new /btw command is here to change all that — by creating a lightweight lane for disposable, context-aware questions.

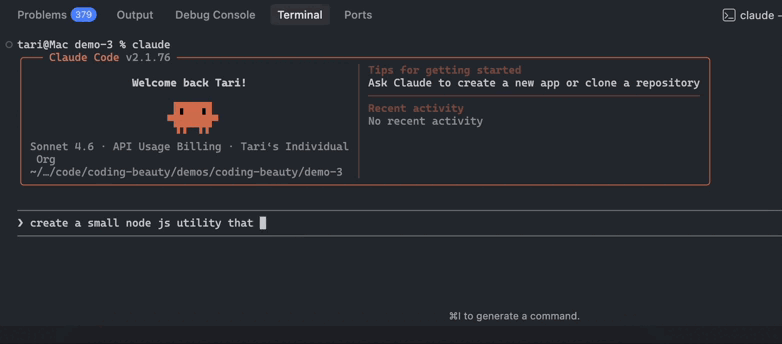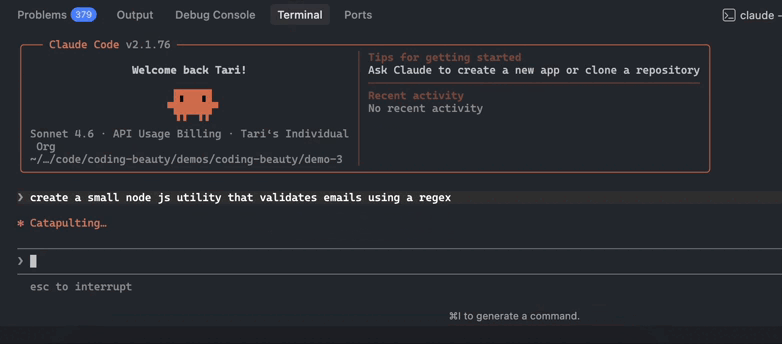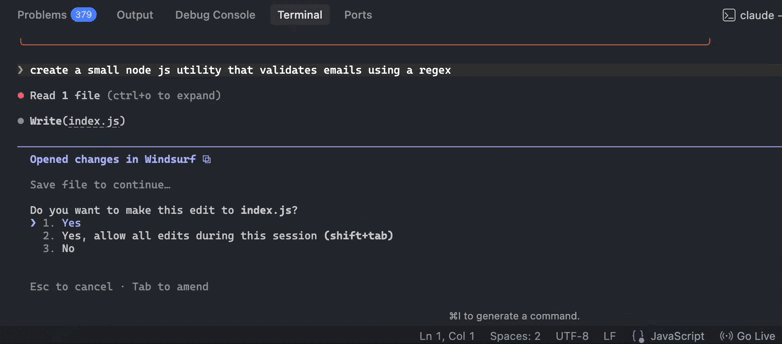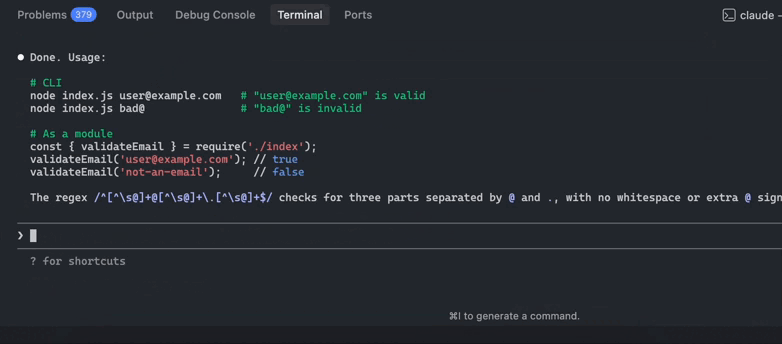
Making changes just before using /btw:

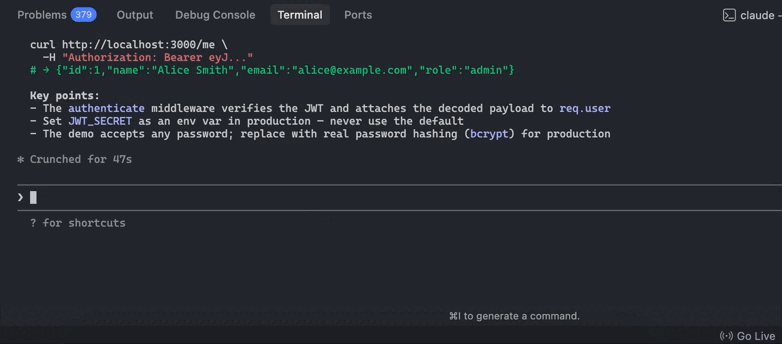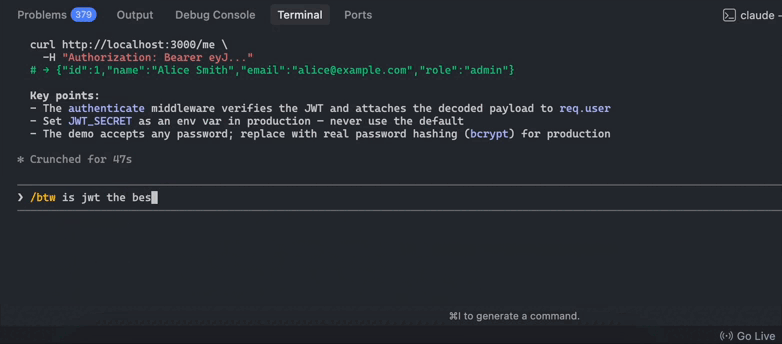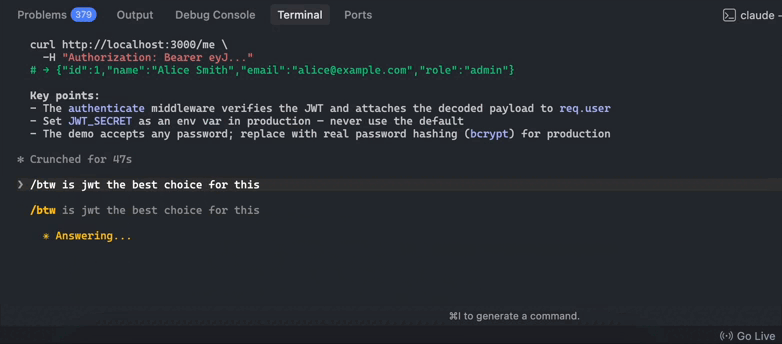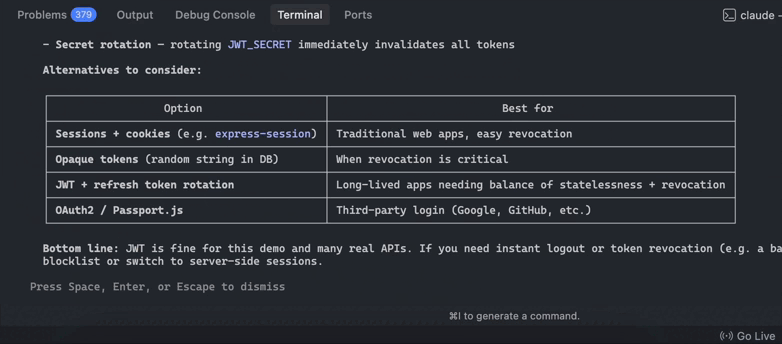
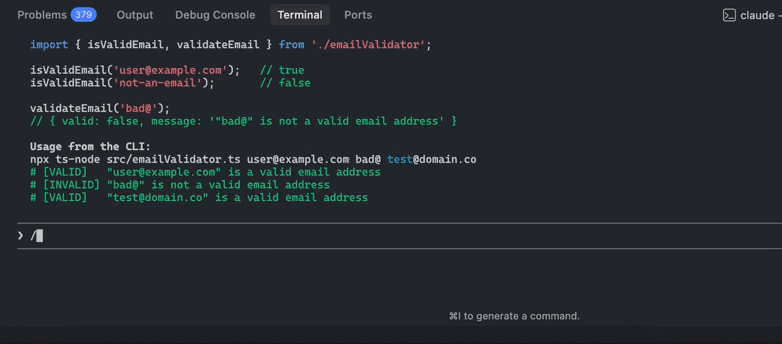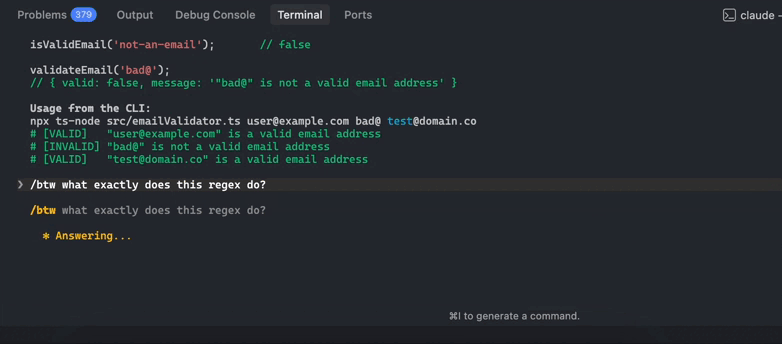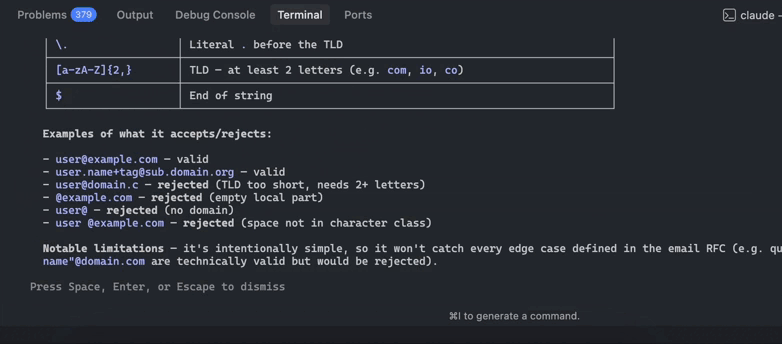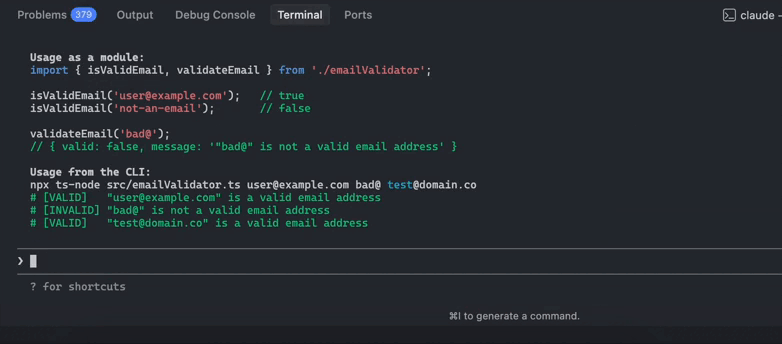
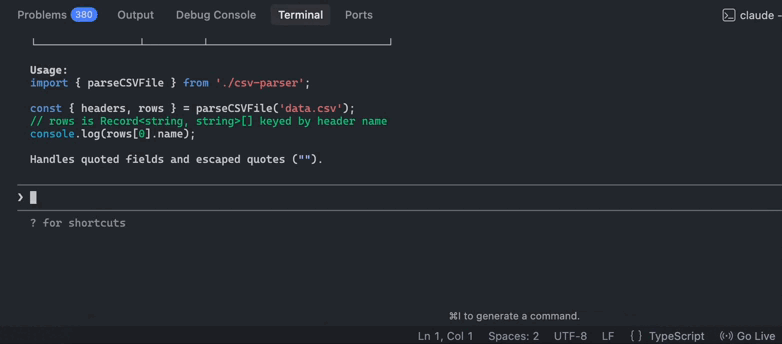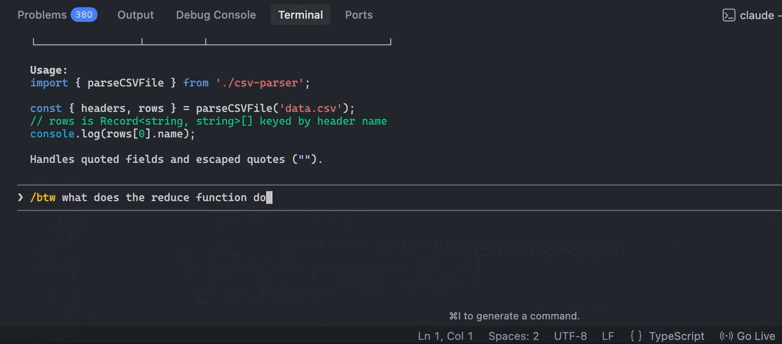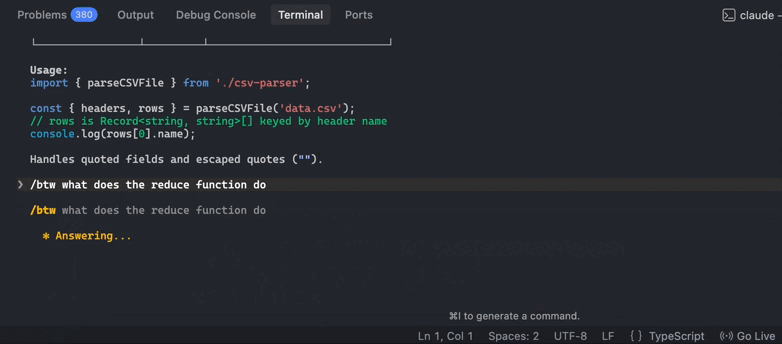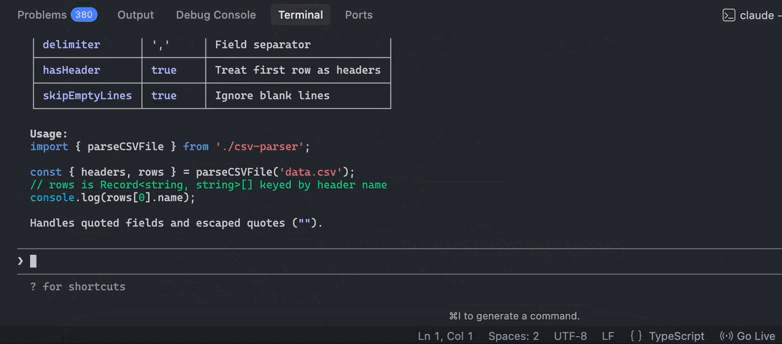
Asking questions on our changes with /btw:

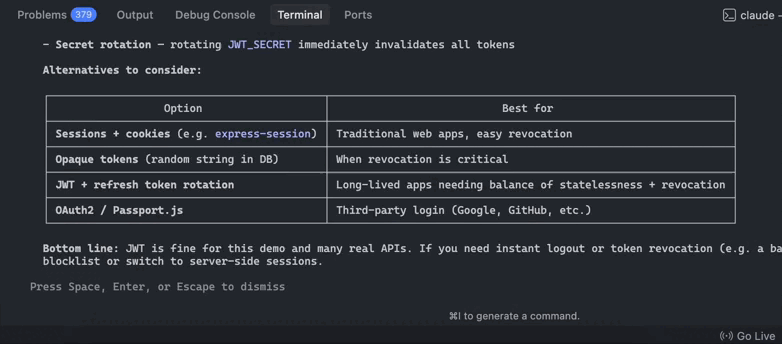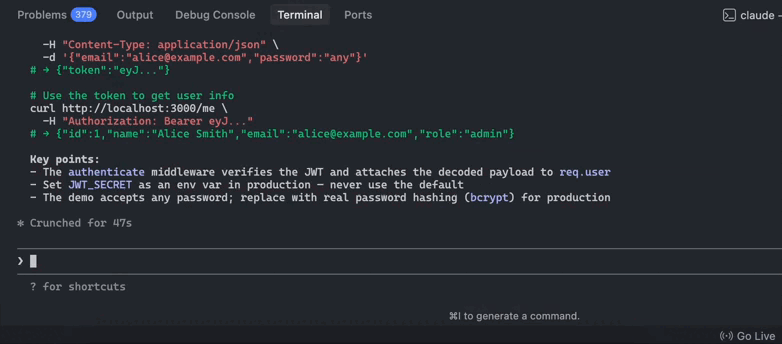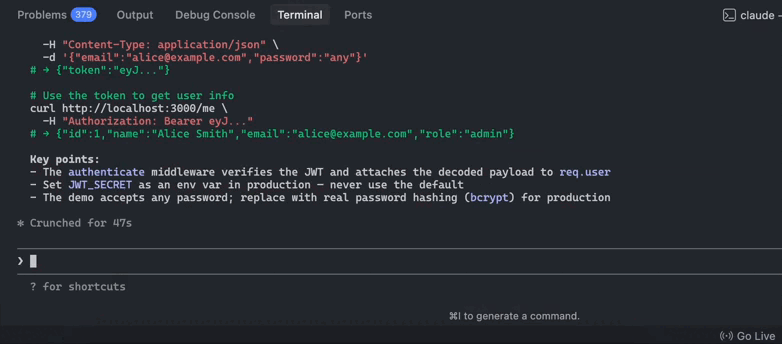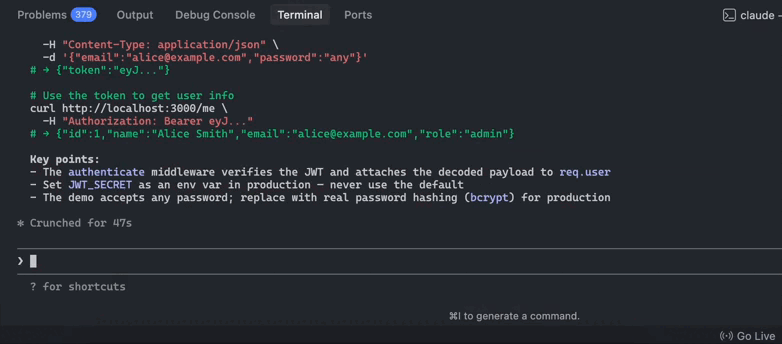
When we press Enter, the btw message disappears and we’re back to our normal conversation:

It’s a simple but powerful feature that makes those long coding sessions cleaner and much more efficient.

What /btw actually is

/btw is a lightweight side-question feature inside Claude Code. It can see the current session context, meaning it understands the code, decisions, and task state already in play.

But unlike the main thread, it’s intentionally constrained.

1. Context-aware

/btw understands the active session.

That means you can ask questions tied to the current work, such as:

Making changes to our codebase:

  • “What does this regex do?”
  • “What is this helper function responsible for again?”
  • “Why did we choose this configuration pattern earlier?”

Using /btw to ask context-aware questions:

You’re not asking a model with zero memory. You’re asking from inside the active coding session, where the relevant context already exists.

That’s what makes /btw more useful than opening a separate AI chat.

2. Disposable history

The core idea behind /btw is that the interaction is temporary.

Your question and its answer do not become part of the main conversation history.

Making changes to our codebase:

Why this matters:

Many developer questions are momentary:

  • reminders
  • clarifications
  • quick explanations

Using /btw to ask questions:

Claude Code doesn’t remember the previous /btw message:

You need the answer right now, but the agent doesn’t need to keep re-reading that exchange for the rest of the session.

Think of /btw as:

  • a sticky note, not a commit message
  • a side whisper, not a meeting transcript

3. Read-only

Another important constraint:

/btw cannot perform actions.

Making changes to our codebase:

It cannot:

  • edit files
  • run bash commands
  • use MCP tools
  • inspect new files

It can only talk.

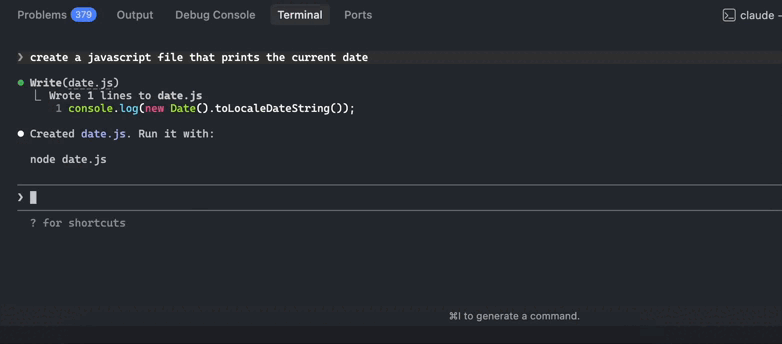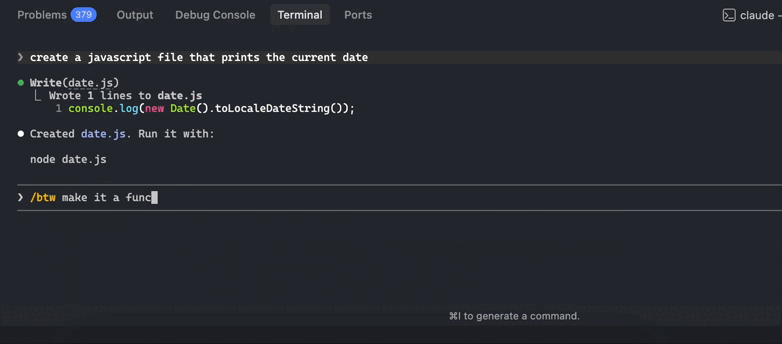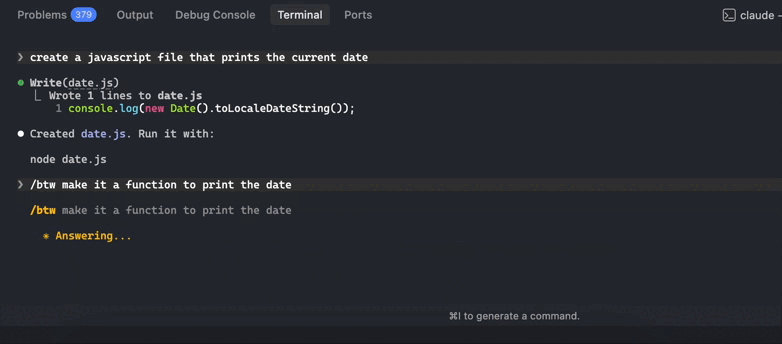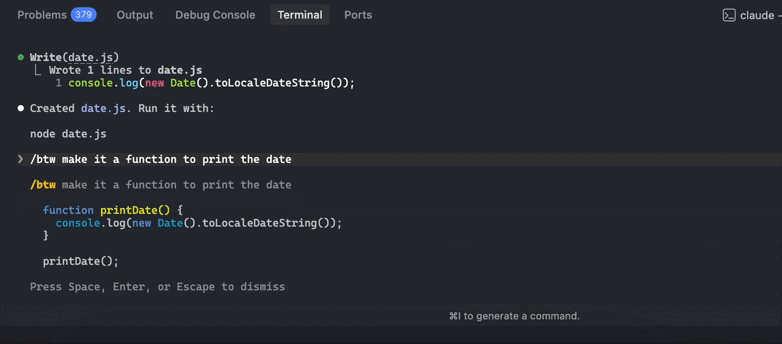
Trying to make changes with /btw — it doesn’t work — it only shows a message containing the code at best:

This means /btw isn’t meant for implementation work. Instead, it’s meant for:

  • explanations
  • reminders
  • quick clarifications
  • contextual understanding

You use /btw to stay oriented while real work continues elsewhere.

4. Single-turn only

/btw also enforces a strict interaction model:

One question. One answer.

There’s no extended back-and-forth and no mini-thread forming inside the /btw window.

That constraint prevents it from turning into a secondary conversation.

It stays exactly what it’s meant to be: a quick aside.

How it helps us as developers

The real value of /btw isn’t the command itself.

It’s how it improves workflow during long, context-heavy coding sessions.

1. Massive token savings

Claude Code stays effective by remaining aware of the full conversation history.

But that also means every new turn in the main thread carries the cost of everything that came before it.

As sessions grow, small interruptions become expensive.

For example:

  • A 40-message thread means Claude rereads a large context every turn.
  • Adding clarification questions increases that cost quickly.

This is where /btw helps.

Instead of putting these into the main thread:

  • “What does this regex do?”
  • “What was this utility function for again?”
  • “What does this flag change?”

You route them through /btw.

The result:

  • fewer tokens in the main thread
  • less history to reread
  • significantly cheaper long sessions

Over time, this can cut total session costs dramatically.

2. It prevents context rot

Long AI conversations naturally degrade.

As threads grow, the context becomes noisy:

  • temporary explanations
  • side questions
  • dead-end ideas
  • minor clarifications

Eventually the model starts losing track of what matters.

Developers often see this as:

  • missed constraints
  • forgotten earlier decisions
  • weaker reasoning

This is essentially context rot.

/btw helps prevent this by enforcing separation:

Main thread

  • implementation
  • architecture decisions
  • debugging
  • planning
  • file edits

/btw

  • explanations
  • quick reminders
  • clarifications
  • trivia

Keeping those categories separate helps the main thread remain clean and focused, which maintains higher reasoning quality for longer.

3. Seamless multitasking

This is the most underrated benefit.

During long-running Claude tasks—like refactors or multi-file updates—you’ll often have small questions.

For example:

  • “What syntax does this function expect again?”
  • “What does that pattern mean?”
  • “Did we say this utility handles validation?”

Without /btw, you have two options:

  1. Interrupt the main thread and risk derailing the workflow.
  2. Hold the question in your head and slow yourself down.

/btw gives you a third option.

You can quickly ask the question without altering the agent’s working context.

This makes Claude feel less like a fragile chat log and more like a collaborator that can handle quick side questions while staying focused on the main task.

The real takeaway

The best way to think about /btw is this:

It’s a pressure-release valve for long Claude Code sessions.

It allows developers to:

  • ask context-aware questions
  • avoid polluting the main thread
  • reduce token usage
  • preserve reasoning quality
  • multitask more smoothly

For developer workflows, that’s not a flashy feature.

It’s just good interface design.

Most AI tools treat every interaction as permanent. /btw recognizes that real development doesn’t work that way.

Some questions matter long-term — others are just momentary.

Treating those differently is exactly why /btw matters.

How this new Claude Code feature saves you from wasting tokens Read More »